CS 200: Concepts of Programming with C++
Table of Contents
- 1. Home
- 2. Syllabus
- 3. Weekly schedule
- 4. Quick reference
- 5. Course contents
- 5.1. Week 1: Welcome, computer basics, programming basics
- 5.2. Week 2: main(), variables, input/output
- 5.3. Week 3: Structs, branching, strings
- 5.4. Week 4: Boolean logic, branching (if statements, switch statements)
- 5.5. Week 5: For loops, arrays, vectors, c-strings
- 5.6. Week 6: Memory, pointers, and dynamic arrays
- 5.7. Week 7: Functions, recursion, and testing
- 5.8. Week 8: Debugging, searching, and sorting
- 5.9. Week 9: Classes
- 5.10. Week 10: Inheritance and composition
- 5.11. Week 11: Project
- 5.12. Week 12: Project
- 5.13. Week 13: Project
- 5.14. Week 14: Project
1. Home
CS 200: Concepts of Programming with C++
Fall semester, 2026
Course contents and page created by R.W. Singh.
- Class time: Tuesdays/Thursdays, 11:00 am - 12:15 pm, RC 353 (and via Zoom)
- Canvas page: https://canvas.jccc.edu/courses/83922
- This document: (url)
- Course catalog: https://catalog.jccc.edu/coursedescriptions/cs/#CS_200
- Syllabus: (url)
- Instructor: R.W. “Moose” Singh (they/them) - rsingh13+cs200@jccc.edu
- Office hours: Wednesdays 9:00 am - 2:00 pm (in person and via Zoom)
1.1. Navigating this course
1.2. Zoom instructions
2. Syllabus
LINK TO STANDALONE SYLLABUS PAGE ▶▼
3. Weekly schedule
| Week # | Tues/Thurs | Content |
|---|---|---|
| 1 | Welcome, computer basics, programming basics | |
| 2 | main(), variables, input/output | |
| 3 | Structs, branching, strings | |
| 4 | While loops, casting, file I/O | |
| 5 | For loops, arrays, vectors, c-strings | |
| 6 | Memory, pointers, dynamic arrays | |
| 7 | Functions, recursion, testing | |
| 8 | Debugging, searching, sorting | |
| 9 | Classes | |
| 10 | Inheritance, composition |
4. Quick reference
4.1. Computer usage
4.1.1. Files, directories, and the filesystem
4.1.2. Terminal aka shell aka command line
4.2. Programming tools
4.2.1. Compiler - g++
4.2.2. make
4.2.3. Git
4.2.4. GitLab
4.2.5. Debugger - gdb
4.2.6. Debugger - lldb
4.2.7. IDE - emacs
4.2.8. IDE - vs code / vs codium
4.3. C++ reference
5. Course contents
5.1. Week 1: Welcome, computer basics, programming basics
int main() { return 0; }
git commit -m "Test example"
This is a text file
5.1.1. 📚 Intro: Navigating the course
WIP
5.1.2. 📚 Intro: Computer Basics - The Filesystem
- Files, directories, and the filesystem
On your computers, tablets, and phones, there is a filesystem structure that organizes all the files on your system - Programs, images, videos, documents, and so on. Being able to navigate your system's files is an important part of computer literacy, and will help with locating your source code and built programs. The filesystem is a representation of items on your device's hard-drive.
- Files
Files on your computer can be text documents, images, videos, audio, or even executable programs (apps). Each file has a name and usually has an extension. The extension is a short-cut for you to tell what type of file the item is. Some common file types are:
Document extension File type FILENAME.docx MS Word document FILENAME.xlsx MS Excel document FILENAME.mp4 Video file FILENAME.mp3 Audio file FILENAME.jpg Image file FILENAME.png Image file FILENAME.zip Compressed file If you're on Windows, I would recommend turning on file extension view so you can see what kind of files are what.
Go to the Start Menu and type "Folder options" and select the "File Explorer Options".

Open the "View" tab, then UNCHECK the "Hide extensions for known file types" box. Click "OK" afterwards.

- Folders/directories
Besides files, the filesystem is also split up into folders (also known as directories). Folders have a name but no file extension - they're not files. They are just locations that store files and other folders. A folder inside of another folder is known as a subfolder.
For instance, in your Photos directory on your computer, you might keep separate folders for different dates ("2025", "2026"), or different projects ("Landscapes") or anything else. On your tablets and phones, you can make "Albums", and behind-the-scenes these become Folders on your device.

Figure 1: Side-by-side screenshots from my Android device: The view of Albums from my Photos app, and then the actual folders on the Filesystem.
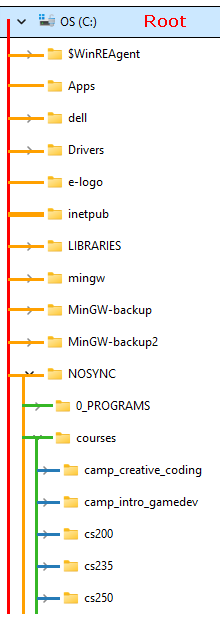
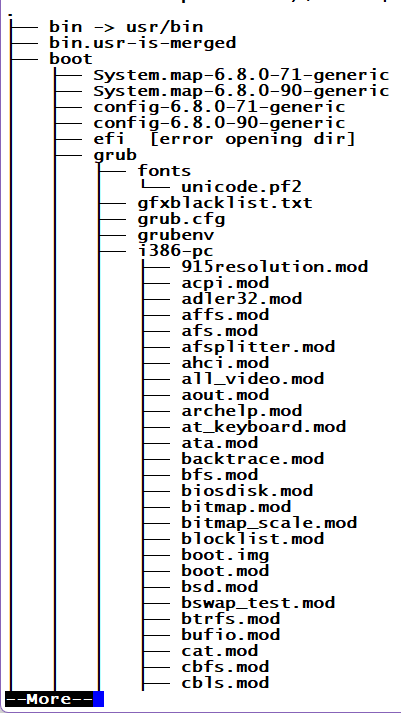
The filesystem on our devices are structured like a tree (though usually drawn like an up-side-down tree), where we have one root location (the base) and it expands into various folders and sub-folders.
Filesystem in Windows
 Filesystem in Linux
On Windows your primary hard-drive is usually put as the
C:\drive. (If your computer has multiple hard-drives, you might also haveD:\,E:\, etc. - CD drives also will get a letter drive as well!)On Linux and Mac, the root directory is written as just a forward slash
/, though you usually won't access the root directory because it's full of system files.When you open up the File Explorer in Windows it starts you at a "Home" directory, which usually has folders for "Pictures", "Documents", and more.
With Mac/Linux, usually you'll also start at a home folder. The path for this is usually at
/home/YOURNAME/, and this directory also usually has a "Photos", "Documents", and other similar folders. - Paths
As we organize our files on our system within folders and subfolders, our files will have a filepath that corresponds to their locations. The filepath is the instructions for how to get to your folder or file, starting from the root directory (
C:\or/) and through every folder on its way.For example, on Windows, many programs are stored in
C:\Program Files, such as Firefox (C:\Program Files\Mozilla Firefox), Zoom (C:\Program Files\Zoom\bin) and more.For Windows, the separator between folders is usually a backslash
\, though it will also accept forward-slashes/.On Mac and Linux, we use forward-slashes ONLY for the folder separator. Your home folder is at
/home/YOURNAME/, and getting elseware builds on top of that. Let's say you have a "homework.txt" file on your Desktop, the path would be/home/YOURNAME/Desktop/homework.txt.Knowing the path of your files is important so you can locate them later, or find them when you need to upload them to the web.
On Windows when you're in the File Explorer, the address bar at the top will show the path. If you click in that area, it will turn to text, and you can copy this text, or just see the full path.

Figure 2: A screenshot of the Windows File Explorer, at location
C:\SCHOOL\rsingh13-cs200\Week02-Basics\program1_recipeV1, which contains therecipe1.cppfile.You can paste the copied path into an "Open File…" dialog box or in another File Explorer window address bar, and after hitting ENTER it will take you to that path quickly.
- Additional Resources
- Files
5.1.3. 📚 Intro: The command line
- Navigating your system with the Terminal
- What is a terminal? (aka Shell aka Bash)
A Terminal is another way to navigate your computer, but via a Command-Line Interface. We're used to working with Graphical User Interfaces (GUI) in our day-to-day lives, but the Terminal is still available, even on mobile devices, to navigate the system, create, move, copy, and remove folders and files, and to run files.
The word "Terminal" is generally interchangable with "Shell" or "Bash" these days, though historically a "Terminal" was not the computer itself but a way to remotely connect to one. But… Our machines usually just call the command line the "Terminal". (Windows uses Powershell or Command Line, Mac and Linux tend to use Terminal).
Some developer software will require the use of the command line, and some developers tools have a CLI (Command-Line-Interface) AND a GUI (Graphical-User-Interface) option. There can be advantages to a CLI over a GUI, even though it might take a little more time to get used to. For instance, you can automate tasks much more easily from the command line vs. the GUI - when I need to send the same code to every student's repository folder, I can write a small script or command to copy/paste to every folder, then do git add/commit/push, instead of having to do everything slowly with the mouse.
- Using the terminal
- Opening the terminal
- Windows: Go to the Start Menu and type in Bash. Open up Git Bash. (There is also Powershell available, which is Microsoft's default terminal, but there are differences in commands it accepts.)
- Mac: Click teh Launchpad icon in your Dock and type in Terminal to find the application.
- Linux: Location depends on your distro, usually it is under "System Tools" from the start menu.
pwd- Present Working Directory
From the starting screen of your terminal, we'll start by entering in the command
pwdand hitting enter.pwdstands for "Present Working Directory", and will return a path. On Linux and Mac, this tends to be/home/YOURNAME/.
On Windows it will be something like
/c/Users/YOURNAME:
For Windows, if you wanted to find this path in your filesystem, just replace "c" with
C:. You can use the forward slashes or backslashes, but it will be "auto-corrected" toC:\Users\YOURNAMEin the file explorer.
ls- LiSt files/folders
The
ls(lowercase L and S) command can be used to view what files and folders are in the current directory.
cd- Change Directory
The
cdcommand can be used to navigate into or out of a folder. If you see a folder you want to navigate into, usecd FOLDERNAME. You can then uselsto view the files in this new directory:
If you want to go back (or, "up") to the parent folder, you can use
..as the path. The double period means the parent folder:
- Opening the terminal
- Additional Resources
- What is a terminal? (aka Shell aka Bash)
5.1.4. 📚 Intro: Memory, storage, and data representation
WIP
5.2. Week 2: main(), variables, input/output
In class:
- Tuesday
- Creating a project
- Building and running the project
- Uploading changes to GitLab via the web interface
- Thursday
- C++ programming
- Example code
- Lab
Assignments:
| Assignment | Book link | Canvas link |
|---|---|---|
| 📚 main() and C++ programs | Canvas quiz | |
| 📚 Variables and data types | Canvas quiz | |
| 📚 cout - Character output | Canvas quiz | |
| 📚 cin - Character input | Canvas quiz | |
| 📚 Program arguments | Canvas quiz | |
| 🧑🏫 Example code: main(), variables, cin, cout | ||
| 💾 Lab: Programs and variables | Canvas assignment |
5.2.1. 📚 Intro: main() and C++ programs
Overview:
- Terms to know: Source code, codeblock, main() function, compile/build, standard library, cout, iostream, stream operator, arguments
- Terminal commands:
- Compile a source file:
g++ FILE.cpp -o PROGNAME.exe - Run a compiled source file:
./PROGNAME.exe - Run a compiled source file (with arguments):
./PROGNAME.exe arg1 arg2
- Compile a source file:
- New code:
- Include a library:
#include <LIBRARY> - Display text:
cout << "Hello!" << endl;
- Include a library:
- Computers and binary, humans and C++
Our computer's CPU only understand commands given to it as binary codes - strings of 1's and 0's, like this: Early programmers had to write their software using this machine code, though over time programming languages evolved. When we write source code these days, we write in a human-made, somewhat human-readable text, with specific grammars and rules to it. These source code files are plaintext - they're just simple text that can be opened in a text editor. We will be using VS Code as the editor where we will write our C++ source code.
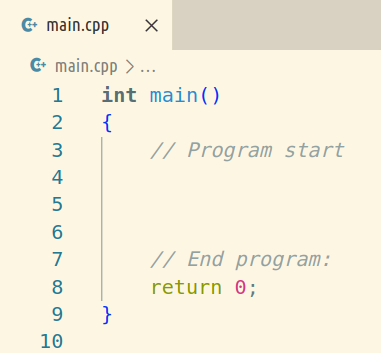
Files on a computer use an extention to identify what kind of file it is, such as a
.jpgfor jpeg format images,.mp3for audio files,.htmlfor website layouts. At minimum, a C++ program requires one file - a.cppsource file. Usually programs are bigger and contain multiple files, like .h header files as well as other .cpp source files. The file that contains the program starting point is usually namedmain.cpp, though this name is not required.Review 1. A C++ source file is plaintext, so it can be opened…
Review 2. The following file type(s) are valid C++ source code files:
- Contents of a starter C++ program
The bare-minimum C++ program looks like this:
int main()
{
  // Code goes here
  return 0;
}
Every C++ program begins at a
main()function.For now you can take this code for granted but you will understand it more as the class continues. But, some basic info:
- The
int main()is the function that starts our program. - The contents of the program must be between the opening curly
brace
{and the closing curly brace}. This region is known asmain()'s codeblock. We will see more codeblocks (with { }) later in the class. - The
return 0;is where the program ends. 0 is returned for 0 errors. - Code we add will go after the
{and before the return 0;.
Additionally, C++ is case sensitive, so capitalization matters. Make sure you write
main()in all lower case -Main()andMAIN()won't work!Review 3. All C++ programs must have a starting point, and it will always be…
Review 4. The space between
{and}is known as… - The
- Creating a program: Building source code into a program
Remember that your computer expects to read binary 1010101010, and does not understand English or other human languages. When we're ready to run our C++ program, we need to run it through a program called a compiler.
A compiler goes through your source code, generating binary code based on what you wrote. The end result is an executable file, also known as a binary file. This is the type of program where, if you double-click it on your computer, it will run.
The compiler program we are using in class is called
g++(orMinGW, which is a Windows port of g++). When we're ready to test out our code, we can open up a terminal in VS Code and enter the command:g++ main.cpp
We're telling the
g++compiler program to convert ourmain.cppsource code file into an executable. By default, it will either generatea.exe(on Windows) ora.out(on Linux/Mac), but we can always rename our program, or we can tell g++ what to name our program in the same step:g++ main.cpp -o MyProgram.exe
Once we're ready to run our program, we would then launch it from the terminal like this:
./MyProgram.exe
Though at the moment, this program does nothing except exit! :
Review 5. In order to specify a custom name for your program executable, you need to use which of these flags?
Review 6. What is the name of the compiler program we use to turn our source code into an executable file?
5.2.2. 📚 Intro: Variables and data types
Video - Variables:
Video - Named constants:
Overview:
- Terms to know: Variables, integers, floats, chars, booleans, strings, variable declaration, assignment, initialization, named constants, garbage data, arithmetic operators, compound operations, string concatenation, LHS, RHS, unsigned data types, literal, auto, unsigned, case sensitivity
- New code:
- Variable declaration:
TYPE VARNAME; - Variable declaration and initialization:
TYPE VARNAME = VALUE; - Variable assignment (after declaration):
VARNAME = VALUE; - Variable assignment with math expression:
VARNAME = NUM1 + NUM2; - Named constant declaration:
const TYPE NAME = VALUE; - string literals must be written in double quotes "", char literals must be written in single quotes ''.
- Variable declaration:
- Common errors:
- If you don't initialize a variable with a value, then it will contain garbage by default.
- Storing data in variables
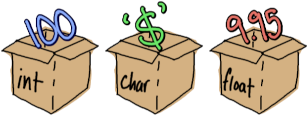
Variables are named locations where we can store information.
We use variables in programming as places to temporarily store data so that we can manipulate that data. We can have the user write to it via the keyboard, we can use files to write data to variables, we can do math operations or modify these variables, and we can print* them back out to the screen or a text file. (*Printing here meaning "display on the screen"; not to a printer.)
When we're writing programs in C++, we need to tell our program what the data type of each variable is, and give each variable a variable name (aka identifier). When a variable is declared, a space in RAM is allocated to that variable and it can store its data there. That data can be manipulated or overwritten later as needed in the program.
Some examples of things we might store as variables:
- A student's information:
string studentName, the name of a studentfloat studentGpa, the GPA of that studentint creditHoursCompleted, the total amount of credit hours the student has completedbool activeStudent, whether the student is an active student or not (e.g., graduated?)
- A store website's item listing:
string name, the name of the productfloat price, the price of the productint quantity, how much of this product is in stock
Review 1. When a variable is declared, where is that data stored?
- ○ CPU
- ○ Hard drive
- ○ Graphics card
- ○ RAM
Review 2. In order to use a variable in C++ we must specify…
- ○ what type of data will be stored in it.
- ○ how much space in RAM we require, in bytes.
Review 3. True or false: A variable's value can be overwritten.
- ○ True
- ○ False
- A student's information:
- Data types
In C++, when we want to create a variable we need to tell the compiler what the data type of the variable is. Data types specify what is stored in the variable (whole numbers? numbers with decimal values? text? true/false values?). Each data type takes up a different amount of space in memory.
Some of the common data types we'll use are:
Data type Values Size Example code char single symbols - letters, numbers, anything 1 byte char currency = '$';boolean trueorfalse1 byte bool savedGame = false;integer whole numbers 4 bytes int age = 100;float numbers w/ decimals 4 bytes float price = 9.95;double numbers w/ decimals 8 bytes double price = 1.95;string any text, numbers, symbols, any length 4 bytes string password = "123secure";- Floats and doubles both store numbers with fractional (decimal) parts, but a double takes up double the memory in RAM, allowing to store more accurate fractional amounts. A float has 6 to 9 digits of precision and a double has 15 to 18 digits of precision. (From https://www.learncpp.com/cpp-tutorial/floating-point-numbers/)
- Boolean data types store true and false values, but will also accept integer values when assigned. It will convert a value of 0 to false and any other number to true.
- String variables' values must be written within double quotes
"Hello!" - Character variables' values must be written within single quotes
'Z'
Additional information: Unsigned data types
Sometimes it doesn't make sense to store negative values in a variable - such as speed (which isn't directional, like velocity), the size of a list (can't have negative items), or measurement (can't have negative width). You can mark a variable as
unsignedto essentially double its range (by getting rid of the negative side of values). For instance, a normal int can store values from -2,147,483,648 to 2,147,483,647, but if you mark it as unsigned, then your range is 0 to 4,294,967,295.Review 4. Identify which data types would work best for each variable description
Types: float, int, string, char
Variables:
pricestemperatureletterGradeseatsAvailablehowManyRegisterednamesaddresses - Declaring variables and assigning values to variables
- Variable declaration
When we're declaring a variable, it needs to follow one of these formats:
Declaration forms
DATATYPE VARIABLENAME;DATATYPE VARIABLENAME = VALUE;DATATYPE VAR1, VAR2, VAR3;DATATYPE VAR1 = VALUE1, VAR2 = VALUE2;DATATYPE VARIABLENAME{VALUE};- Newer versions of C++
The data type goes first, then the variable name/identifier, and if you'd like, you can also assign a value during the same step (though this is not required). Once a variable has been declared, you don't need to declare it again. This means you don't need to re-specify its data type when you're using it. Just address the variable by its name, and that's all.
// Declaring variables and assigning values
int totalCandies{10};
int totalKids{5};
int candiesPerKid{totalCandies / totalKids};

// Reusing the same variables later on
totalCandies = 100;
totalKids = 10;
candiesPerKid = totalCandies / totalKids;
float price = 9.99;
float tax = 0.11;
// Text output to the screen. Can do math within!
cout << "Please pay " << (price + price * tax);
Additional information: Modern C++:
autoIn C++11 (from 2011) and later, you can use the keyword
autoas the "data type" in your variable declaration that includes an assignment statement. When you useauto, it uses the assigned value to automatically figure out the variable's data type, so you don't have to explicitly define it:auto price = 9.99; // it's a double! auto price2 = 2.95f; // it's a float! auto player = '@'; // it's a char! auto amount = 20; // it's an int!
- Variable assignment
Assignment forms
Stores the LITERAL value in VARIABLENAME:
VARIABLENAME = LITERAL;Copies the value from VARIABLENAME2 to VARIABLENAME1.:
VARIABLENAME1 = VARIABLENAME2;
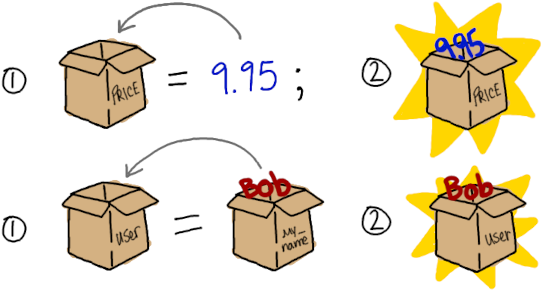
When assigning a value to a variable, the variable being assigned to always goes on the left-hand side ("LHS") of the equal sign =. The = sign is known here as the assignment operator.
The item on the right-hand side ("RHS") will be the value stored in the variable specified on the LHS. This can be a literal (a hard-coded value) or it can be a different variable of the same data type, whose value you want to copy over.
price = 9.99;       // 9.99 is a float literal
state = "Kansas";   // "Kansas" is a string literal
operation = '+';    // '+' is a char literal
// Declare and initialize our variables
string student1 = "Hikaru";
string student2 = "Umi";
string student3 = "Fuu";
string bestStudent;

// Assignment statement
bestStudent = student3;
- Variable copying
If you use two variables in an assignment statement, like this:
bestStudent = myName;
This will copy the value in
myNameand store that copy inbestStudent. - Variable initialization
When we declare a variable and give it a value in the same line of code, that is called initialization. The equal sign can be used in this regard:
string productName = "Candybar";
float productPrice = 3.25;
But with more modern C++, it's recommended that we use braced initialization:
string productName{ "Candybar" };
float productPrice{ 3.25 };
You might see both of these ways used to initialize variables in starter code.
- Additional information: Garbage!
If a variable is not initialized with some value, it will have some garbage value assigned to it - whatever was left over in the memory space where it was created. This data isn't useful to us, and usually shows up as random large numbers (12734827), so it's good to make sure to initialize your variables!
Review 5. How would we declare a variable to represent a person's temperature and give it a value of 98.6?
Review 6. How would we declare a variable to represent a student's name and assign it the value of Maryam?
Review 7. What data t ype will the compiler set this variable as?
- ○ bool
- ○ char
- ○ float
- ○ string
Review 8. A boolean variable has already been declared and it is named savedGame. How do you assign a value of true to the variable?
Review 9. Given the two variables declared…
string user1 = "Bob";
strin guser2 = "Ami";
And then this assignment statement is executed:
user1 = user2;What will the value of each variable be afterwrard?
user1is _.user2is _.
- Variable declaration
- Named constants
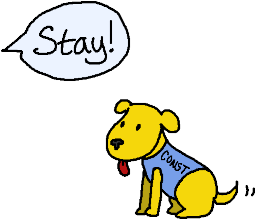
Whenever you find yourself using a literal value in your assignment statements, you may want to think about whether you should replace it with a named constant instead.
const CONSTNAME = LITERAL;
A named constant looks like a variable when you declare it, but it also has the keyword const - meaning that the value can't change after its declaration.
Let's say you wrote a program and hard-coded the tax rate:
// Somewhere in the code...
totalPrice = cartTotal + ( cartTotal * 0.0948 );

// Somewhere else in the code...
cout << 0.0948 << " sales tax" << endl;
Then the tax rate changes later on. You would have to go into your program and search for "0.0948" and update all those places! Instead, it would have been easier to assign the tax rate ONCE to a named constant and referred to that instead:
// Beginning of program somewhere...
const SALES_TAX = 0.0948;

// Somewhere in the code...
totalPrice = cartTotal + (cartTotal * SALES_TAX);

// Somewhere else in the code...
cout << SALES_TAX << " sales tax" << endl;
If you ever find yourself using the same literal multiple times in your program, then perhaps consider replacing it with a named constant.
Review 10. How would we declare a named constant to represent the maximum amount of students in a class and assign it a value of 30?
- Naming conventions
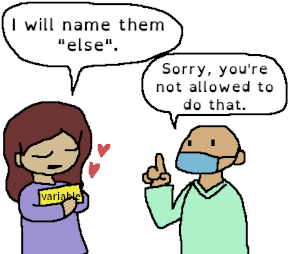
While you can generally name a variable whatever you'd like, you still need to adhere to the syntax rules of the C++ language. In particular:
- Names can only contain letters (upper- and lower-case), numbers, and underscores.
- Spaces are not allowed in a variable name!
- Names cannot start with a number.
- A name cannot be a keyword in C++, a name reserved for something
else in the language, such as
void,if,int, etc.
There are also naming conventions used so that variables (and later on functions and structs/classes) have a consistent naming scheme:
- Variables:
- One common style is
lowerFirstLetterThenUpperCasefor variable names - this is called Camel Case. - Another style you might see in C++ code is
all_lower_with_underscores. - You might see both of these styles in my starter code or examples, but I try to stick to one style for a program. You should also choose one and stay consistent in each program.
- One common style is
- Named constants:
- It is customary to give your named constants names in ALL CAPS,
using underscores (
_) to separate words. For example:TOTAL_STUDENTS,OP_TAX_RATE, etc.
- It is customary to give your named constants names in ALL CAPS,
using underscores (
Everything in C++ is case sensitive, which means if you name a variable
username, it will be a different variable from one nameduserName(or if you type "userName" when the variable is called "username," the compiler will complain at you because it doesn't know what you mean).Review 11. Identify which variable names are valid or invalid.
- ○ Valid / ○ Invalid
total Pizzas - ○ Valid / ○ Invalid
int - ○ Valid / ○ Invalid
farmName - ○ Valid / ○ Invalid
my_int
- Basic operations on variables
Now that you have variables available in your program to play with, what can you even do with them?
- Outputting variable values
Using the
cout(character-out) statement, you can display text to the screen with string literals:cout << "Hello, world!" << endl;But you can also display the values stored within variables, simply by using the variable's name:
cout << myUsername << endl;
You can also chain as many literals, variables, and commands together as long as they have the output stream operator
<<in-between.cout << "Student: " << name << endl << "GPA: " << gpa << endl << "Year: " << year << endl << endl;
- Inputting variable values
We can use the
cin(character-in) statement to get the user to enter something on the keyboard and store that data into a variable:float gpa; cin >> gpa;
cin >>can be used on strings, but it will not read anything after a space. Instead, we use thegetlinefunction to read whole lines of text intostringvariables:string oneLine; getline( cin, oneLine ); string oneWord; cin >> oneWord;
There will be more information on input and output in a later section.
- Math operations
With variables with numeric data types (ints, floats, doubles), we can do arithmetic with the +, -, *, and / operators.
Symbol Description +Addition -Subtraction *Multiplication /Division Make sure to put the result somewhere! When you do a math operation and you want to use the result elsewhere in the program, make sure you're storing the result in a variable via an assignment statement! If you just do this, nothing will happen:
totalCats + 1;You can use an assignment statement to store the result in a new variable:
newCatTotal = totalCats + 1;Or overwrite the variable you're working with:
totalCats = totalCats + 1;
- Compound operations
There are also shortcut operations you can use to quickly do some math and overwrite the original variable. This works with each of the arithmetic operations:
// Long way:
totalCats = totalCats + 5;

// Compound operation:
totalCats += 5;
Other shorthand:
Description Long version Short 1 Short 2 Increment x = x + 1; x += 1; x++; OR ++x; Increment x = x + 2; x += 2; Decrement x = x - 1; x -= 1; x–; OR –x; Decrement x = x - 2; x -= 2; Multiply x = x * 2; x *= 2; Divide x = x / 2; x /= 2; - String operations
Strings have some special operations you can do on them. You can also see a list of functions supported by strings here: C++ String Reference (We will cover more with strings in a later part).
Concatenating strings
You can use the
+symbol to combine strings together. When used in this context, the + sign is called the concatenation operator.string type = "pepperoni"; string food = "pizza"; // Creates the string "pepperoni pizza" string order = type + " " + food;
Letter-of-the-string
You can also use the subscript operator
[ ](more on this when we cover arrays) to access a letter at some position in the string. Note that in C++, the position starts at 0, not 1.string food = "pizza"; char letter1 = food[0]; // Stores 'p' char letter2 = food[1]; // Stores 'i' char letter3 = food[2]; // Stores 'z' char letter4 = food[3]; // Stores 'z' char letter5 = food[4]; // Stores 'a'
Review 12. Given the variables
x = 4andy = 2, after the statementz = x + y;The value of
zwill be: _Review 13. Given these variables and their values:
int a = 10;
int b = 20;
int c = 30;
int d = 40;
What is the result of the variable after each of the following operations?
awill be _ after:a++;
bwill be _ after:b--;
cwill be _ after:c *= 2;dwill be _ after:d /= 2;
Review 15. A float variable named ratio has already been declared. Which of the following assigns a float literal as a value for the variable?
- ○ ratio = Calculate( grade, total );
- ○ ratio = grade / total;
- ○ ratio = 0.5;
- ○ ratio = ratio + 1.0;
- Outputting variable values
5.2.3. 📚 Intro: cout - Character output
Overview:
- Terms to know: output stream operator, escape sequences, tab, endl, cout,
- New code:
- Write a string literal to the screen:
cout << "Hello!"; - Write a newline to the screen:
cout << endl; - Write a variable's value to the screen:
cout << VARNAME; - Chain together multiple items:
cout << "Price: " << VARNAME << endl;
- Write a string literal to the screen:
- The
iostreamlibrary
A library is a set of prewritten code that we can use in our programs. C++ has a set of libraries that come with it, and third parties can also create libraries. But anyway, in order to be able to display output to the screen we will need to include one of the built-in C++ libraries -
iostream.At the top of our source code file, we will have to add an
#includestatement to add this library to our program:#include <iostream>
This will allow us to use the
coutandendlcommands from thestd(STandarD) library:std::cout << "HI!" << std::endl;
But we can also simplify our code by adding in
using namespace std;beneath our library includes, so that we don't have to prefixstd::on all of our iostream commands:#include <iostream> using namespace std; int main() { cout << "HI!" << endl; return 0; }
Review 1. If our file begins with just this:
#include <iostream>
then our outputs will be written like…
○
cout << "Hello!";○
std::cout << "Hello!";Review 2. If our file begins with this:
#include <iostream>
using namespace std;
then our outputs will be written like…
○
cout << "Hello!";○
std::cout << "Hello!"; - Outputting Information with
cout
In order to display text to the screen with our program, we need to include a library. A library is a set of pre-written code that can be used across multiple programs. C++ contains a standard library of pre-written code we can use. To gain access to the cout (character-output) statement, we need to add this at the top of our C++ program file:
#include <iostream>
After that, we can use the cout command to display text like this:
std::cout << "Hello!";
The
std::prefix stands for "STandarD", as in the C++ standard library. This command will display "Hello!" to the screen when the program is built and run.You can also add empty lines to the program using the endl (end-line) command:
std::cout << std::endl;
And these commands can be chained together:
std::cout << "Hello!" << std::endl << "World!" << std::endl;
The
<<sign is known as the output stream operator.Review 7. A library is…
- Using namespace std
You can put
using namespace std;at the top of the C++ program to state that this code file will be using commands out of thestd(standard) library. With this, you can remove thestd::prefixes from iostream commands likecoutandendl. - Chaining outputs
The
coutcommand (pronounced as "c-out" for "character-out") is used to write information to the screen. This can include outputting a string literal:cout << "Hello, world!" << endl;or a variable's value:
cout << yourName << endl;
or stringing multiple things together:
cout << "Hello, " << yourName << "!" << endl;
In C++, we use the output stream operator
<<to string together multiple items for our output. - Newlines with endl
The
endlcommand stands for "end-line" and ensures there is a vertical space between thatcoutstatement and the next one. For example, if we write twocoutstatements without endl like this:cout << "Hello"; cout << "World";
Program output:
HelloWorld
If we want to separate them on two different lines, we can write:
cout << "Hello" << endl;
cout << "World";
Program output:
Hello
World
Remember that in C++, a statement ends with a semicolon ;, so you can split your
coutstatement across multiple lines, as long as you're chaining items together with<<and only adding a;on the last line:cout << "Name: " << name << "Age: " << age << "State: " << state << endl;
Review 8. Match the terms to the code…
1. Character output A. endl2. End line B. <<3. Output stream operator C. coutReview 3. A string literal is…
○ Any string variables being declared
○ Any text written inside of double quotes
○ Any << statements
○ The cout command
Review 4.
coutis pronounced "Kowt".○ true
○ false
Review 5. The output stream operator is:
○
cout○
endl○
<<Review 6. We want to display the message "ERROR: File not found!" to the screen. How do we do this?
○
cout << "ERROR: " File not found!;○
cout << ERROR: File not found!;○
cout << "ERROR: File not found!";○
cout << 'Error: File not found!';Review 7. A variable has been declared:
int year = 1999;.How do we display the variable's value to the screen?
○
cout << "year";○
cout << 'year';○
cout << year;
- Using namespace std
- Good user interfaces
One of the important parts of writing software is making sure users know how to navigate and use your program. While writing your programs, assume that the person running it knows nothing about this program. Make sure everything they need to know about the program is given to them as instructions, and make sure menus are easy to read.
- Drawing a line of characters across the screen
We can use the
stringlibrary to create a line of characters with some width, without having to type out all those characters ourselves. Its form looks like this:cout << string( AMOUNT, CHAR ) << endl;
An example of it being used is:
cout << "MAIN MENU" << endl << string( 20, '-' ) << endl;
Program output:
MAIN MENU
--------------------
- Escape Sequences
There are special characters, called escape sequences, that you can use in your
coutstatements:Character Description \nnewline (equivalent to endl)\ttab \"double quote cout << "\"hello\nworld\"" << endl;Program output:
"hello
world"
C++ source: Using the tab character in outputs
cout << "A\tB\tC" << endl;
cout << "1\t2\t3" << endl;
Program output:
A       B       C
1       2       3
C++ source: Displaying text with double quotes in it
cout << "He said \"Hi!\" to me!" << endl;Program output:
He said "Hi!" to me!
- Formatting currency
By default, the following code:
float price = 10.90;
cout << "Price: $" << price << endl;
Will give us output like this:
Price: $10.9
To get our program to always display two numbers to the right of the decimal place, we need to include the iomanip (input/output manipulation) library:
#include <iomanip>
And then add this command to our program somewhere:
cout << fixed << setprecision( 2 );
Then, our program's output will look like this:
Price: $10.90
- Tables and columns
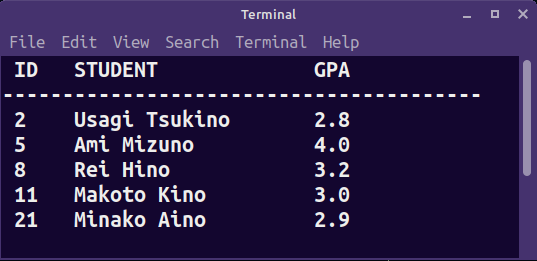
Figure 3: A simple table in a command line C++ program. There are three columns: ID, Student, and GPA, with the column headers shown on top.
If we want to make a table in our program, we need to use columns with fixed widths. We will need to #include <iomanip> again.
We can specify the width of a column for the following item being displayed with the setw command, like this:
cout << setw( 5 ) << "ID";
This will give the following column a width of 5. The text "ID" takes up 2 spaces, so then there are 3 empty spaces left over. cout statements afterwards will start at the end of this column.
For a table header, I usually write it like this:
cout << left
  << setw( 5 ) << "ID"
  << setw( 20 ) << "STUDENT"
  << setw( 6 ) << "GPA"
  << endl << string( 40, '-' ) << endl;
This sets the text alignment to left-aligned (default is right-aligned), then creates three columns: ID, Student, and GPA.
Then, further down in the table, I can use the same setw values for the data:
cout
  << setw( 5 ) << "2"
  << setw( 20 ) << "Usagi Tsukino"
  << setw( 6 ) << "2.8"
  << endl;
This will create a nice table that is easy for the user to read.
Review 8. Let's say we have a variable named
currentBalance, which stores a user's bank account balance. What would be a good user interface for displaying the balance to the user?○
cout << Balance: $ << currentBalance << endl;○
cout << currentBalance << endl;○
cout << "Balance: $" << currentBalance << endl;○
cout << "Balance: $" << endl;Review 9. Before getting input from the user, you should…
○ Display the current value of the variable.
○ Display a message using
coutto tell the user what kind of input the program is expecting.○ Not display any messages with
cout.Review 10. To draw a horizontal bar 80 characters wide, you would use…
○
cout << string( 80, '-' ) << endl;○
cout << string( '-', 80 ) << endl;○
cout << string( 80, "--" ) << endl;○
cout << string( "--", 80 ) << endl;Review 11. Given the program output:
Hello world!Goodbye world!Which line of code contains the tab character
\t?○ The line with "Hello world" contains the tab character.
○ The line with "Goodbye world" contains the tab character.
Review 12. Given the program output…
abcWhich cout statement would match this format?
○
cout << "a\tb\tc" << endl;○
cout << "a\nb\nc" << endl;○
cout << "a b c" << endl;Review 13. If we had the variable
pi = 3.14159and we wanted to display three digits after the decimal point, we would set…cout << fixed << setprecision( _ _ _ _ );Review 14. If we want to make the next column take up 10 spaces and display the value of the variable
price, we would write…:cout << setw( _ _ _ _ ) << price << endl;
- Tables and columns
- Drawing a line of characters across the screen
5.2.4. 📚 Intro: cin - Character input
Overview:
- Terms to know: input stream operator,
- New code:
- Get input (ints, floats, strings, etc.):
cin >> VARNAME; - Get string line input:
getline( cin, STRINGNAME ); - Flush the input buffer:
cin.ignore();
- Get input (ints, floats, strings, etc.):
- Common errors:
- If you're using
cin >> STRINGNAME;to get input for a string, it will only get ONE WORD and stop at the first space. If you want to allow spaces, usegetlineinstead. getlinecan only be used for strings, not ints/floats/etc.- If you're switching between
cin >> ...andgetline( cin, ... ), you need to putcin.ignore()after thecin >>and before thegetline.- If your program is skipping an input, it means you're missing
a
cin.ignore(). - If your program is getting input but truncating the first
letter of what you typed, you have too many
cin.ignore()calls.
- If your program is skipping an input, it means you're missing
a
- If you're using
- The "
getline" function is used for… - When do you need to have
cin.ignore();in your code?
- Using
cin >>for variables
When we want the user to enter a value for a variable using the keyboard, we use the
cincommand (pronounced as "c-in" or "character-in").Example: Reading input into one variable
cin >> VARIABLENAME;
You can also chain cin statements together to read multiple values for multiple variables:
Example: Inputting data into multiple variables at once (separated by spaces)
cin >> VARIABLENAME1 >> VARIABLENAME2 >> ETC;
- Strings and
cin >>
When using
cin >>with a string variable, keep in mind that it will only read until the first whitespace character, meaning it can't capture spaces or tabs. For example:Example: Getting one word (ends at spaces) with the input stream operator
string name;
cin >> name;
If you enter "Rachel Singh", name will contain "Rachel". To capture spaces, you need to use a different function.
Review 1.
coutis pronouned ○ kowt / ○ see-out / ○ countcinis pronounced ○ sin / ○ see-in / ○ kin
Review 2. Given an integer variable declared named totalCookies, how would you get input from the keyboard and store it in this variable?
- Strings and
- Using
getline(cin, var);for Strings
You can use the getline function to capture an entire line of text as a string. This is useful when you want to capture spaces and multiple words. For example:
Example: Getting a full line of text (including spaces) with the getline function
string name;
getline(cin, name);
Review 3. A string variable named currentCourse has been declared. How would we read keyboard input (including spaces) and store it in this variable?
cout << "Please enter course: ";
// Then what?
- Mixing
cin >> var;andgetline(cin, var);
If you mix
cin >> var;andgetline(cin, var);, you might encounter issues with the input buffer. To avoid this, usecin.ignore();beforegetline(cin, var);if you usedcin >> var;before it.int number; string text; cin >> number; cin.ignore(); getline( cin, text );
Review 3. Which of the following scenarios requires the cin.ignore() statement?
A.
cin >> var1;
cin.ignore();
cin >> var2;
B.
cin >> var1;
cin.ignore();
getline( cin, var2 );
C.
getline( cin, var2 );
cin.ignore();
cin >> var1;
D.
getline( cin, var1 );
cin.ignore();
getline( cin, var2 );
5.2.5. 📚 Intro: Program arguments
Overview:
- Terms to know:
- Argument
- args
- argc/arg count
- New code:
- The amount of arguments passed into the program:
argCount - The list of arguments:
args - Argument with the program name:
args[0] - Arguments after that:
args[1],args[2], etc. - Store argument in string variable:
string VAR = string( args[1] ); - Store argument in float variable:
float VAR = stof( args[1] ); - Store argument in int variable:
int VAR = stoi( args[1] );
- The amount of arguments passed into the program:
- What are program arguments?
Some command line programs take in arguments when you run them. For example:
ping yahoo.com. Thepingprogram takes in a URL as an argument, then the program will launch and attempt to send packets of information to the URL and see if there's a response.We can also write comamnd line programs with arguments. To do this, we need to add a couple of arguments to main:
int main( int argCount, char* args[] )
{
}
In this case, any text given after the program name will be stored in
args[1]and after (the program name is inargs[0].)char* args[]is an array of c-style strings, though we can convert them into other data types. Theint argCounttells us how many arguments were passed into the program. If the user doesn't pass in enough arguments, we could display an error message and what we expect the arguments to be.For the time being, don't worry about "int", "char*", or "[ ]", but we will learn about these later. The arguments item is essentially a list of input items passed to the program. argCount will also contain the amount of arguments passed in. So, if a program is run like this:
./program ONE two THREE
Then it would have 4 total arguments (the program name counts as one), with "ONE" being argument #1, "two" being argument #2, and "THREE" being argument #3.
Review 1. Program arguments…
Review 2. Let's say a program named factorial is run like this:
./factorial 5Identify each argument
Review 3. Let's say a program named add is run like this:
./add 2 3Identify each argument
- Converting arguments to different types
We can convert the arguments to different data types. The following code snippet shows examples:
int main( int argCount, char* args[] )
{
    if ( argCount < 5 )
    {
        cerr << "Not enough arguments!" << endl;
        return 1;
    }

    int myInteger = stoi( args[1] );
    float myFloat = stof( args[2] );
    string myString = string( args[3] );
    char myChar = args[4][0];
}
Generally in the starter code I'll handle checking for enough arguments and set up the input variables and cast the arguments to them, so you won't have to worry about this part of a program's setup.
Review 4. Identify the commands used.
5.2.6. 🧑🏫 Example code: main(), variables, cin, cout
5.2.7. 💾 Lab: Programs and variables
5.3. Week 3: Structs, branching, strings
5.3.1. 📚 Intro: Boolean logic
Overview:
- Terms to know: Boolean expression, and, or not, logic operators
Overview:
- 📽️ Overview video: Boolean logic
- Terms to know: logic operators, relational operators, true, false, boolean expressions, and, or, not, truth tables, DeMorgan's Law
- Introduction
Computers are all about binary - 1's and 0's, on and off, true and false. A large part of writing logic with our programs is all about asking "yes/no" questions. If "criteria" is true, then execute this code… if it's false, execute that code. In order to better understand how branching works in our programs, it's important to learn about boolean logic.
"Boolean" refers to something that is either true or false. This can be the values "true" and "false" itself, or it can be an expression that evaluates to true or false. For example:
- if (the user clicked "save") then…
- if (the account balance is less than 0) then…
- if (the "done" variable is set to true) then…
The statements within the parentheses are the boolean expressions, and then we can use those expressions in if statements and while loops to execute code only if that condition evaluates to true.
Review 1. Which of the following statements are boolean expressions?
- □ What color is the sky?
- □ The sky is blue.
- □ How many fingers am I holding up?
- □ MarioLives is less than 0.
- True/false questions in programming
Question Represented as C++ code Is x equal to y? x == y Is x not equal to y? x != y Is x greater than y? x > y Is x greater than or equal to y? x >= y Is x less than y? x < y Is x less than or equal to y? x <= y Is x true? x Is x false? !x x and y can be swapped out with different types of data. We can check if two strings of text are equal, or if two numbers are equal. With the bottom two examples, "is x?" and "is not x?" applies for if x is a boolean variable - a variable that is storing a value of either true or false.
if ( i_have_not_been_fed && it_is_6_am ) {
  MakeLotsOfNoise();
}
Review 2.
- What is the "is equal to" operator?
- What is the "less than or equal to" operator?
- What is the "greater than or equal to" operator?
- What is the "not equal to" operator?
- Compound operations with logic operators
We can also create compound boolean expressions from separate boolean expressions using logic operators. Logic operators are AND (
&&), OR (||), and NOT (!).- Is x == y and x == z?
- In C++ code:
x =y && x= z - True if both sub-expressions are true (x==y and x==z).
- False if one or both sub-expressions are false.
- In C++ code:
if ( wantsBeer && isAtLeast21 && likesBeer ) {
    GiveBeer();
}
- Is x == y or x == z?
- In C++ code:
x =y || x= z - True if at least one sub-expression is true.
- False if both sub-expressions are false.
- In C++ code:
if ( isBaby || isSenior || isVet )
{
    GiveDiscount();
}
- Is x false?
- In C++ code:
!x - True if the sub-expression is false.
- False is the sub-expression is true.
- In C++ code:
// Just checking documentSaved is true
if ( documentSaved ) {
    Quit();
}

// Checking if documentSaved is false
if ( !documentSaved ) {
    Save();
    Quit();
}
Review 3.
- What is the AND operator?
- What is the OR operator?
- What is the NOT operator?
- Is x == y and x == z?
- Boolean variables and relational operations
We can have boolean variables that store true or false, and we can then do tests on those values…
bool quit = false;

// ( pretend there's more code here )

if ( quit ) // If quit is true
{
    return 0; // exit
}
But we can also create boolean expressions by utilizing those relational operators to compare two values together.
float balance;
cout << "Enter your bank balance: ";
cin >> balance;

if ( balance < 0 ) // balance < 0 will return true or false
{
    cout << "OVERDRAWN!" << endl;
}
These relational operators can also work on strings, where
<and>will check alphabetical order (sort of).string student1, student2; cout << "Enter student 1 name: "; getline( cin, student1 ); cout << "Enter student 2 name: "; getline( cin, student2 ); if ( student1 < student2 ) { cout << "Student 1 goes first" << endl; } else { cout << "Student 2 goes first" << endl; }
Note that when using
<and>with strings or chars, it will compare them based on alphabetical order - if they're both the same case (both uppercase or both lowercase). The code 65 represents'A', but the code 97 represents'a', so items will be "sorted" based on these codes. - Truth tables
We can use truth tables to help us visualize the logic that we're working with, and to validate if our assumptions are true. Truth tables are for when we have an expression with more than one variable (usually) and want to see the result of using ANDs, ORs, and NOTs to combine them.
- Truth table for NOT:
On the top-left of the truth table we will have the boolean variables or expressions written out, and we will write down all its possible states. With just one variable
p, we will only have two states: when it's true, or when it's false.On the right-hand side (I put after the double lines) will be the result of the expression - in this case, "not-p" \(!p\). The not operation simply takes the value and flips it to the opposite: true \(\to\) false, and false \(\to\) true.
p!pT F F T - Truth table for AND:
For a truth table that deals with two variables,
pandq, the total amount of states will be 4:pis true andqis true.pis true andqis false.pis false andqis true.pis false andqis false.
pqp && qT T T T F F F T F F F F This is just a generic truth table. We can replace the values with boolean expressions in C++ to check our logic.
- Truth table for OR:
This also deals with 2 variables, \(p\) and \(q\), so 4 total states. If at least one of the two variables are true, then the entire expression is true. An expression with an "or" is only false when all sub-expressions are false.
pqp ‖ qT T T T F T F T T F F F - Example - AND:
We will only quit the program if the game is saved and the user wants to quit:
game_savedwant_to_quitgame_saved && want_to_quitT T T T F F F T F F F F The states are:
- T:
gameSavedis true andwantToQuitis true: Quit the game. - F:
gameSavedis true andwantToQuitis false: The user doesn't want to quit; don't quit. - F:
gameSavedis false andwantToQuitis true: The user wants to quit but we haven't saved yet; don't quit. - F:
gameSavedis false andwantToQuitis false: The user doesn't want to quit and the game hasn't been saved; don't quit.
- T:
- DeMorgan's Laws
Finally, we need to cover DeMorgan's Laws, which tell us what the opposite of an expression means.
For example, if we ask the program "is a \(>\) 20?" and the result is false, then what does this imply? If \(a > 20\) is false, then \(a \leq 20\) is true… notice that the opposite of "greater than" is "less than OR equal to"!
- Opposite of
a && b
aba && b!( a && b )!a ‖ !bT T T F F T F F T T F T F T T F F F T T If we're asking "is
atrue and isbtrue?" together, and the result is false, that means either:ais false andbis true, orais true andbis false, orais false andbis false.
These are the states where the result of
a && bis false in the truth table.In other words,
!( a && b )\(\equiv\)!a ‖ !bIf \(a\) is false, or \(b\) is false, or both are false, then the result of
a && bis false. - Opposite of
a ‖ b:
aba ‖ b!( a ‖ b )!a && !bT T T F F T F T F F F T T F F F F F T T If we're asking "is \(a\) true or \(b\) true?", if the result of that is false that means only one thing:
- Both
aandbwere false.
This is the only state where the result of
a || bis false.In other words,
!( a ‖ b )\(\equiv\)!a && !ba ‖ bis false only ifais false ANDbis false. - Both
- Opposite of
- Example - OR:
If the store has cakes OR ice cream, then suggest it to the user that wants dessert.
hasCakehasIcecreamhasCake‖hasIceCreamT T T T F T F T T F F F The states are:
- T:
hasCakeis true andhasIcecreamis true: The store has desserts; suggest it to the user. - T:
hasCakeis true andhasIcecreamis false: The store has cake but no ice cream; suggest it to the user. - T:
hasCakeis false andhasIcecreamis true: The store has no cake but it has ice cream; suggest it to the user. - F:
hasCakeis false andhasIcecreamis false: The store doesn't have cake and it doesn't have ice cream; don't suggest it to the user.
Review 2.
- ○
- T:
- Truth table for NOT:
- Summary
In order to be able to write if statements or while loops, you need to understand how these boolean expressions work. If you're not familiar with these concepts, they can lead to you writing logic errors in your programs, leading to behavior that you didn't want.
5.3.2. 📚 Intro: If statements
Overview:
- Terms to know: Condition
- New code: How to write if statements, if/else statements, if/else if statements
Branching is one of the core forms of controlling the flow of the program. We ask a question, and based on the result we perhaps do this code over here or maybe that code over there - the program results change based on variables and data accessible to it. We will mostly be using if / else if / else statements, though switch statements have their own use as well. Make sure to get a good understanding of how each type of branching mechanism "flows".
- Yes or no? - If/Else statements
The computer only understands "yes/no" questions - questions that either result in true or false. Based on these outcomes, we can choose to execute one set of code or another.
Form of an if/else statement:
// Do things 1

if ( CONDITION )
{
  // Do things 2-a
}
else
{
  // Do things 2-b
}

// Do things 3
The else block is executed when the if check fails. If the CONDITION is false, we can use DeMorgan's Laws to figure out what the program's state is during the else.
NOTE: The else statement NEVER has a CONDITION.
Example C++ source: Displaying "can't vote" if age is less than 18, or "can vote" otherwise
cout << "Enter your age: ";
cin >> age;

if ( age < 18 )
{
  result = "can't vote";
}
else
{
  result = "can vote";
}

cout << "Result: " << result << endl;
If the
ageis less than 18, it will set theresultvariable to "can't vote". If that boolean expression is false, that meansageis \(\geq\) 18, and then it will set theresultto "can vote". Finally, either way, it will display "Result: " with the value of theresultvariable.Review 1. Given the if statement:
if ( studentCount <= maxStudents )
{
  cout << "You can register for the course!" << endl;
}
else
{
  cout << "Course is full!" << endl;
}
When is "You can register for the course!" displayed and when is "Course is full!" displayed?
- Standalone If statement
For a basic if statement, we use the syntax:
// Do things 1

if ( CONDITION )
{
  // Do things 2-a
}

// Do things 3
The CONDITION will be some boolean expression. If the boolean expression result is true, then any code within this if statement's code block (what's between
{and}) will get executed. If the result of the expression is false, then the entire if statement's code block is skipped and the program continues.Example: C++ source: Displaying "(OVERDRAWN!)" only if the bank balance is less than 0
cout << "Bank balance: " << balance;

if ( balance < 0 )
{
  cout << " (OVERDRAWN!)";
}

cout << " in account #" << accountNumber << endl;
Program output: Output with
balance = -50Bank balance: -50 (OVERDRAWN!) in account #1234
Program output: Output with
balance = 100Bank balance: 100 in account #1234
- The special message "OVERDRAWN!" only gets displayed when the balance is less than 0.
- The following
coutthat gives the account number is displayed in all cases.
Review 2. Given the if statement:
cout << "Bank balance: $" << balance;
if ( balance < 0 )
{
  cout << " (OVERDRAWN)" << endl;
}
When would "Bank balance" be shown to the screen without (OVERDRAWN), and when would the bank balance and overdrawn text be shown?
- If/Else if/Else statements
In some cases, there will be multiple scenarios we want to search for, each with their own logic. We can add as many else if statements as we want - there must be a starting if statement, and each else if statement will have a condition as well.
We can also end with a final else statement as a catch-all: if none of the previous if / else if statements are true, then else gets executed instead. However, the else is not required.
Form of an if/else if/else statement
// Do things 1
if ( CONDITION1 )
{
  // Do things 2-a
}
else if ( CONDITION2 )
{
  // Do things 2-b
}
else if ( CONDITION3 )
{
  // Do things 2-c
}
else
{
  // Do things 2-d
}
// Do things 3
Example: Displays a letter grade based on range, 90 and above is an 'A', and so on…
cout << "Enter grade: ";
cin >> grade;

if      ( grade >= 90 ) { letterGrade = 'A'; }
else if ( grade >= 80 ) { letterGrade = 'B'; }
else if ( grade >= 70 ) { letterGrade = 'C'; }
else if ( grade >= 60 ) { letterGrade = 'D'; }
else                    { letterGrade = 'F'; }

cout << "Grade: " << letterGrade << endl;
- I'm first checking if the grade is 90 or above. If it is, then
I know the letter grade is
'A'. - However, if it's false, it will go on and check the next else if statement. At this point, I know that since grade >= 90 was FALSE
- that means: grade < 90 is TRUE.
- Since the next statement checks if grade >= 80
- if this one is TRUE, I know that: grade < 90 AND grade >= 80
Review 3. Given the if statement:
if ( grade >= 90 )
{
  cout << "Grade: A" << endl;
}
else if ( grade >= 80 )
{
  cout << "Grade: B" << endl;
}
else if ( grade >= 70 )
{
  cout << "Grade: C" << endl;
}
else
{
  cout << "You need to retake the course" << endl;
}
- When is "Grade: A" displayed?
- When is "Grade: B" displayed?
- When is "Grade: C" displayed?
- When is "You need to retake the course" displayed?
- I'm first checking if the grade is 90 or above. If it is, then
I know the letter grade is
- Nesting if statements
If statements, While loops, and For loops all have code blocks: They contain internal code, denoted by the opening and closing curly braces
{ }. Within any block of code you can continue adding code. You can add if statements in if statements in if statements, or loops in loops in loops.Nesting an if statement within another if statement basically gives you a boolean expression with an AND.
Example:
if ( wantsToVote )
{
  if ( age >= 18 )
  {
    AllowToVote();
  }
}
Equivalent logic:
if ( wantsToVote && age >= 18 )
{
  AllowToVote();
}
Whether you implement some logic with nested if statements, or with if / else if statements using AND operations is a matter of design preference- in some cases, one might be cleaner than the other, but not always.
If you have a statement like this:
if ( conditionA )
{
  if ( conditionB )
  {
    Operation1();
  }
  else
  {
    Operation2();
  }
}
It could be equivalently described like this:
if ( conditionA && conditionB )
{
  Operation1();
}
else if ( conditionA && !conditionB )
{
  Operation2();
}
Review 4. Given this code snippet:
if ( computerOn == true )
{
  if ( printerOn == true )
  {
    cout << "RESULT A" << endl;
  }
  else
  {
    cout << "RESULT B" << endl;
  }
}
else
{
  if ( printerOn == true )
  {
    cout << "RESULT C" << endl;
  }
  else
  {
    cout << "RESULT D" << endl;
  }
}
When is each result displayed?
- Logic operators with if statements
We can also combine multiple conditions together using our logic operators:
- AND:
&& - OR:
|| - NOT:
!
If we have an if statement with two conditions combined with an AND, then the if statement is only executed if all sub-conditions are true:
if ( CONDITION1 && CONDITION2 )
    DoThingOne(); /* All conditions were true */
else
    DoThingTwo(); /* One or more conditions were false */
If we have an if statement with two conditions combined with an OR, then the if statement is executed if at least one sub-condition is true:
if ( CONDITION1 || CONDITION2 )
    DoThingOne(); /* One or more conditions were true */
else
    DoThingTwo();/* All conditions were false */
Review 5. Given this code snippet:
if ( choice < 1 || choice > 5 )
{
  cout << "INVALID INPUT!" << endl;
}
else
{
  cout << "Valid input" << endl;
}
When would "INVALID INPUT!" be displayed, and when would "Valid input" be displayed?
Review 6. Given this code snippet:
if ( choice >= 1 && choice <= 5 )
{
  cout << "Valid input" << endl;
}
else
{
  cout << "INVALID INPUT!" << endl;
}
When would "Valid input" be displayed, and when would "INVALID INPUT!" be displayed?
- AND:
5.3.3. 📚 Intro: Switch statements
Overview:
- Terms to know: Switch statements, cases, default, scope, break, flow-through
- New code: How to write a switch statement
- Another way to branch
Switch statements are a special type of branching mechanism that only checks if the value of a variable is equal to one of several values. Switch statements can be useful when implementing a menu in a program, or something else where you only have a few, finite, discrete options.
In C++, switch statements only work with primitive data types, like integers and chars - not strings.
switch ( VARIABLE )
{
 case VALUE1:
   // Do thing
 break;

 case VALUE2:
   // Do thing
 break;

 default:
  // Default code
}
With a switch statement, each case is one equivalence expression. The
defaultcase is executed if none of the previous cases are.case VALUE1: // equivalent to: if ( VARIABLE == VALUE1 )
case VALUE2: // equivalent to: if ( VARIABLE == VALUE2 )
break: // required at the end of a case statement (unless...)
default: // equivalent to: else
The default case is not required, just like how the else clause is not required in an if statement.
- The
break;statement
The end of each case should have a
break;statement at the end. If thebreakis not there, then it will continue executing each subsequent case's code until it does hit a break.This behavior is "flow-through", and it can be used as a feature if it matches the logic you want to write.
- Scope: Variables inside cases
If you're declaring a variable within a case statement, you need to enclose your case with curly braces
{ }, otherwise you'll get compiler errors:switch ( operation ) { case 'A': { float result = num1 + num2; cout << "Result: " << result << endl; } break; }
- Calculator example
Perhaps you are implementing a calculator, and want to get an option from the user: (A)dd, (S)ubtract, (M)ultiply, or (D)ivide. You could store their choice in a
charvariable calledoperationand then use theswitchstatement to decide what kind of computation to do:switch ( operation ) { case 'A': // if ( operation == 'A' ) result = num1 + num2; break; case 'S': // else if ( operation == 'S' ) result = num1 - num2; break; case 'M': // else if ( operation == 'M' ) result = num1 * num2; break; case 'D': // else if ( operation == 'D' ) result = num1 / num2; break; } cout << "Result: " << result << endl;
- Example: Flow-through
Sometimes you want to check if your variable equals a value "x" or "y", and execute the same code for each. You can use flow-through in this case. If no
break;is given for a specificcase, then it will continue to execute code for the followingcaseuntil abreak;is found.char choice; cout << "Do you want to quit? (Y/N): "; cin >> choice; switch ( choice ) { case 'Y': case 'y': done = true; break; case 'N': case 'n': done = false; break; default: cout << "Unknown selection!" << endl; }
Review 1. Given the following code:
switch( option )
{
    case 'X':
        cout << "RESULT 1" << endl;
    break;

    case 'Y':
        cout << "RESULT 2" << endl;
    break;

    case 'Z':
        cout << "RESULT 3" << endl;
    break;

    default:
        cout << "RESULT 4" << endl;
}
And the variable option with the value Y, what will be the output?
Review 2. Given the following code (no breaks):
switch( option )
{
    case 'X':
        cout << "RESULT 1" << endl;

    case 'Y':
        cout << "RESULT 2" << endl;

    case 'Z':
        cout << "RESULT 3" << endl;

    default:
        cout << "RESULT 4" << endl;
}
And the variable option with the value Y, what will be the output?
5.3.4. 📚 Intro: Structs
Overview:
- Terms to know: File guards, objects, Object Oriented Programming, encapsulation, loose coupling, high cohesion, structs, members,
- New code:
Creating a file guard in a .h file:
#ifndef _LABEL
#define _LABEL
// code goes here
#endif
Declaring a struct:
struct NAME { int MEMBERVAR1; float MEMBERVAR2; string MEMBERVAR3; };- Declaring a variable whose data type is a struct:
STRUCTNAME STRUCTVAR; - Accessing members of the struct:
STRUCTVAR.MEMBERVAR1 = 123;cout << STRUCTVAR.MEMBERVAR2 << endl;
- Introduction to objects

Programming paradigms (pronounced "pair-uh-dimes") are ways we can classify different programming styles. Some programming languages support multiple paradigm styles and some are restricted to one style of coding. Over the decades different paradigms have been developed and evolved over time. Object Oriented Programming is one of the most common styles of programming these days, and is a big part of how C++, C#, and Java-based programs are designed.
- What are "Objects"?
Defining classes and structs in our programs are a way that we can create our own data types for our variables. When we define our own structures, we can create them with internal variables and functions available to them. The variables we create, whose data types come from a defined class or struct, is known as an object.
Design-wise, the idea is to take real-world objects and find a way to represent them in a computer program as an object that has attributes (variables) and functionality (functions).
- OOP design ideals
The concept of Object Oriented Programming is creating a design that is easy to maintain over time. In particular, there are some core design goals behind OOP, including:
- Encapsulation: Giving the user / other programmers an “interface” \ to
interact with the objects, hiding the inner-workings within the class.
- Certain functions are made public, which other programmers can use to interface with the object.
- The other programmers don't need to worry about the inner-workings of the object in order to use it.
- The developer of the class can modify how the internals work without breaking the public interface.
- Helps protect the data within the class from being accessed or modified by external things that shouldn't have access to it.
- Loose coupling: Ideally, different objects in a program shouldn't have their functionality tied to other objects too closely; we want to reduce inter-dependence between objects. When objects are more independent from each other, we say they are loosely coupled.
- High cohesion: When we design our objects, we shouldn't just throw everything and the kitchen sink into one object. To design an object with high cohesion means that everything inside the object belongs to that object - reduce the clutter.
Review 1. What does it mean for our objects' designs to be "High Cohesion"?
- Encapsulation: Giving the user / other programmers an “interface” \ to
interact with the objects, hiding the inner-workings within the class.
- What are "Objects"?
- Making our own data type with
struct
Structs are a way we can group related information together into one data type.
For example, let's say we were writing a program for a restaurant, and an item on the menu would have a name, a price, a calorie count, and a "is it vegetarian?" signifier. We could declare these all as separate variables:
string food1_name;
float food1_price;
int food1_calories;
bool food1_is_veggie;
But there isn't really anything in the program that says these variables are related, except that we as humans have given these variables similar prefixes in their names.
A better design would be to create a new datatype called MenuItem (or something similar), and the MenuItem will contain these four variables within it. We're basically making a variable data type that can contain multiple variables!
First we create the struct, which should go in its own .h file:
Example: MenuItem.h
struct MenuItem
{
  string name;
  float price;
  int calories;
  bool isVeggie;
};
And then we can declare variables of this type in our program:
Example: Within
int main()MenuItem food1; food1.name = "Bean Burrito"; food1.price = 1.99; food1.calories = 350; food1.isVeggie = true; MenuItem food2; food2.name = "Crunchy Taco"; food2.price = 1.99; food2.calories = 170; food2.isVeggie = false;
Review 2. Those separate variables with the same prefix to indicate a relationship are (○ beautiful / ○ ugly)
Review 3. If we were storing multiple food items and using this approach for each, what might be a downside to the design?
- ○ It's too much typing.
- ○ Our programs should have no more than 3 variables.
- ○ There is nothing that requires every food to have the same set of variables.
Review 4. So, Creating a struct to group like-things together and make a new data type. (○ cool! / ○ terrible!)
- Best practices: Multiple files in C++ programs
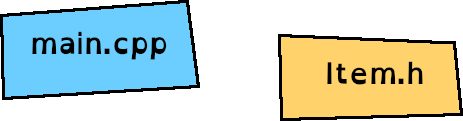
When creating a struct, we should create a new source code file in our project. Usually the name of the file will be the same name as the struct, with a .h at the end. This is a header file and declarations for structs (and functions and classes later) will go in these types of files.
Something you need to require in your .h files that isn't needed for your .cpp files are file guards. These prevent the compiler from reading the file more than once. If it reads it multiple times, it will think you're redeclaring things over and over again. Your .h files should always look like this:
Example: Struct .h file
#ifndef _MYFILE_H
#define _MYFILE_H

// put code here

#endif
Where the "
_MYFILE_H" should be changed to something unique in each file - usually, the name of your file.Review 5. In standard C++ code, it is better to move our struct declaration to a header (.h) file… (○ true / ○ false)
Review 6. File guards are needed in .h files because…
- ○ It makes sure the contents of the .h file don't bleed into your main() function.
- ○ It protects the file from invaders.
- ○ It prevents the compiler from reading the same file twice and thinking that there's duplicate code.
Review 7. A struct can be declared above
int main()and the program will still compile and run… (○ true / ○ false) - Creating our own structs
- Declaring a struct
A basic struct declaration is of the form…
#ifndef _MYFILE_H
#define _MYFILE_H

struct STRUCTNAME
{
  // member variables
  int MEMBER1;
  string MEMBER2;
  float MEMBER3;
};

#endif
Note that the closing curly-brace
}must end with a;otherwise the compiler will give you errors.You can name your struct anything you'd please but it has to abide by the C++ naming rules (no spaces, no keywords, can contain letters, numbers, and underscores).
Any variables we declare within the struct are known as member variables - they are members of that struct.
Any new variables you declare whose data type is this struct will have its own copy of each of these variables.
- Declaring object variables
A object is a type of variable whose data type is a struct (or class). To declare a variable whose data type is a struct, it looks like any normal variable declaration:
DATATYPE VARIABLE;
- Accessing member variables
Our struct object variables each have their own member variables, which we access via the dot operator
.. We can assign values to it, our read its value, similar to any normal variable.VARIABLE.MEMBER1 = 10; VARIABLE.MEMBER2 = "ASDF"; VARIABLE.MEMBER3 = 2.99; cout << VARIABLE.MEMBER1 << endl;
- Displaying member variables
When we have a struct declared and an object-variable created…
Book myBook;
… We won't be able to use
couton the object…cout << myBook << endl;
… (Unless we overload operators, but that's for a future class!) Instead, remember that you have to output each member variable in the way you wish, because C++ won't know how you want to display the contents of a struct!…
cout << "Title:  " << myBook.title << endl
     << "Author: " << myBook.author << endl;
Review 8. What would be an appropriate declaration of a struct meant to represent a vehicle, storing the vehicles's manufacturer and year within?
Review 9. Given a struct named
MenuItem, to declare a variable namedfood2of this type, we would write…Review 10. If a struct Teacher is declared and an object-variable is created:
Teacher cs200Teacher;Does the following command work?
cout << cs200Teacher << endl;- ○ No, C++ doesn't know how to cout a "Teacher" object we've created.
- ○ Yes, C++ will automatically recognize the Teacher struct's member variables and display them in order.
Review 11. If we declared a Course object like:
Course cs200;How would we assign "cs" to the course department and "200" to the course code?
- Declaring a struct
- Example: Fraction struct
First we would declare our Fraction struct within Fraction.h:
#ifndef _FRACTION_H
#define _FRACTION_H

struct Fraction
{
  int num;
  int denom;
};

#endif
Within
main(), we could then create Fraction variables and work with them:#include "Fraction.h" int main() { Fraction frac1, frac2, frac3; cout << "FIRST FRACTION" << endl; cout << "* Enter numerator: "; cin >> frac1.num; cout << "* Enter denominator: "; cin >> frac1.denom; cout << endl; cout << "SECOND FRACTION" << endl; cout << "* Enter numerator: "; cin >> frac2.num; cout << "* Enter denominator: "; cin >> frac2.denom; frac3.num = frac1.num * frac2.num; frac3.denom = frac1.denom * frac2.denom; cout << endl; cout << "PRODUCT: " << frac3.num << "/" << frac3.denom << endl; return 0; }
- Composition: Structs with other Structs as member objects
In addition to creating structs with normal variables, we can also create struct-object-variables as members of another struct.
Let's say we have a Teacher struct and a Course struct, for each Course we want to store the teacher of that course…
Teacher.h:
#ifndef _TEACHER_H
#define _TEACHER_H

#include <string>
using namespace std;

struct Teacher
{
  string name;
  string email;
};

#endif
Course.h:
#ifndef _COURSE_H
#define _COURSE_H

#include "Teacher.h"

#include <string>
using namespace std;

struct Course
{
  Teacher teacher;
  string department;
  int code;
  int hours;
};

#endif
5.3.5. 📚 Intro: String library
Overview:
- Terms to know: Strings, library, concatenation,
- Concepts:
- To use string library you need to have
#include <string> - A
stringis technically an array of characters. string::nposis used for the find function when a substring is NOT found within the first string.
- To use string library you need to have
- New code:
- Strings as arrays
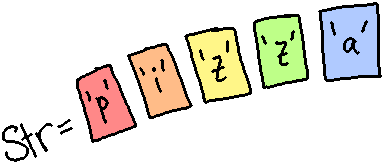
A string is a special data type that really is just an array of char variables. A string has a lot going on behind-the-scenes, and it also has a set of functions you can use to do some common operations on a string - finding text, getting a letter at some position, and more.
Note that everything with strings is case-sensitive. A computer considers the letter
'a'and'A'different, since they are represented by different number codes. Keep that in mind for each of the string's functions.Review 1. A
charis…- ○ Multiple letters, numbers, or symbols, stored in double quotes.
- ○ Multiple letters, numbers, or symbols, stored in single quotes.
- ○ A single letter, number, or symbol, stored in double quotes.
- ○ A single letter, numbe,r or symbol, stored in single quotes.
Review 2. To a C++ program, the letter
'a'and'A'are considered…- ○ Different characters
- ○ The same characters
- Using strings
When we declare a string like this:
string str = "pizza";
what we have behind-the-scenes is an array like this:
Value: 'p''i''z''z''a'Index: 0 1 2 3 4 Declaring a string actually gives us an array of
charvariables. We can access the string as a whole by using the string variable's name (str), or access onecharat a time by treatingstrlike an array. - Subscript operator - get one char with [ ]
We can access each letter of the string directly with the subscript operator, just like an array:
Example: Outputting each letter of a string
cout << str[0] << endl; // Outputs p
cout << str[1] << endl; // Outputs i
cout << str[2] << endl; // Outputs z
cout << str[3] << endl; // Outputs z
cout << str[4] << endl; // Outputs a
Because we can act on a string like an array, this means we can also use a variable to access an arbitrary index of a character in the array…
Example: Accessing one letter at some position
iint i; cout << "Get which letter? "; cin >> i; cout << str[i];
Or even iterate over the string with a for loop…
Example: Iterating and displaying each letter of a string
for ( int i = 0; i < str.size(); i++ )
{
    cout << i << " = " << str[i] << endl;
}
Additionally, strings have a set of functions that we can use to manipulate, search, and otherwise work with them.
Review 3. Given the variables
string name = "LUNA";
char letter;
The first letter of the
nameis at index 0. How do we store the first letter ofnamein thechar lettervariable?Review 4. Identify the index of each letter in LUNA:
Index Value 'L' 'U' 'N' 'A'
- Size of the string
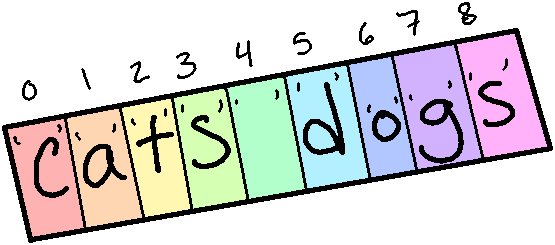
size_t size() const;The string's
size()function will return the size of the string - how many characters are stored in the string. Thesize_tdata type is just a type of integer - an unsigned integer, because sizes cannot be negative amounts.Documentation: https://www.cplusplus.com/reference/string/string/size/
Example: Outputting a string's length
Let's write a little program that asks the user to enter some text, and then outputs the length of the string:
string text;
cout << "Enter some text: ";
getline( cin, text );
cout << "That string is " << text.size()
    << " characters long!" << endl;
When the user enters a line of text, it will count all characters (including spaces) in the string, so the text
"cats dogs"would be 9 characters long.Program output:
Enter some text: cats dogs
That string is 9 characters long!
Example: Counting z's
If we wanted to use a for loop to iterate over all the letters of an array, we could! Perhaps we want to count the amount of z's that show up:
string text;
int zCount = 0;

cout << "Enter some text: ";
getline( cin, text );

// Iterate from i=0 to the size of the string (not-inclusive)
for ( unsigned int i = 0; i < text.size(); i++ )
{
    // If this letter is a lower-case z or upper-case Z
    if ( text[i] == 'z' || text[i] == 'Z' )
    {
        // Add one to z count
        zCount++;
    }
}

// Display the result
cout << "There were " << zCount
    << " z(s) in the string!" << endl;
Program output:
Enter some text: The wizard fought a zombie lizard
There were 3 z(s) in the string!
Review 5. Given the string:
string text = "a cat";
What will the output of this code be? (Remember what whitespace counts as a character.)
cout << text.size() << endl; - Concatenating strings with +

We can use the
+operator to add strings together as well. This is called concatenation.Let's say we have two strings we want to combine -
favoriteColorandpetName, we can use the concatenation operator+to build a new string,superSecurePassword.string favoriteColor = "purple"; string petName = "Luna"; string superSecurePassword = favoriteColor + petName; cout << superSecurePassword << endl; // = purpleLuna
We can also add onto strings by using the
+=operator. Let's say you're building a string over time in a program, and want to append parts separately.string pizzaToppings = ""; // Later on... pizzaToppings += "Buffalo sauce, "; // Later on... pizzaToppings += "Cheese, "; // Later on... pizzaToppings += "Pineapple"; // Later on... cout << pizzaToppings << endl;
At the end of the program, the value of
pizzaToppingswould be:"Buffalo sauce, Cheese, Pineapple"Review 6. Given the strings:
string str1 = "t";
string str2 = "e";
string str3 = "a";
What will the output of this code be?
cout << str3 + str1 + str2 << endl;
- Finding text with find()
size_t find (const string& str, size_t pos = 0 ) const;The find function can be used to look for a substring in a bigger string. If the substring is found, its position is returned. Otherwise, the value of
string::nposis found.When a starting
posis included, it only begins the search at that position. If left off, it defaults to 0 (the start of the string).Documentation: https://www.cplusplus.com/reference/string/string/find/
So when we want to search a string for some text, we can call it like
bigString.find( findMeString ), and that function call will return an unsigned integer: the location of thefindMeStringwithinbigString, or the value ofstring::nposwhen it is not found.string str = "this was written during the 2021 winter storm make it stop please."; string findMe = "winter"; size_t position = str.find( findMe ); cout << "The text \"" << findMe << "\" was found at position " << position << endl;
Program output:
The text "winter" was found at position 33
Review 7. Given the string:
string text = "The quick brown fox jumps over the lazy dog.";
where the letters have the following indices:
0    1    2    3    4    5    6    7    8    9    10   11   12   13
-------------------------------------------------------------------
T    h    e         q    u    i    c    k         b    r    o    w

14   15   16   17   18   19   20   21   22   23   24   25   26   27   28
------------------------------------------------------------------------
n         f    o    x         j    u    m    p    s         o    v    e

29   30   31   32   33   34   35   36   37   38   39   40   41   42   43
------------------------------------------------------------------------
r         t    h    e         l    a    z    y         d    o    g    .
What will the output of the following be?
cout << text.find( "fox" ) << endl;
- Finding substrings with substr()
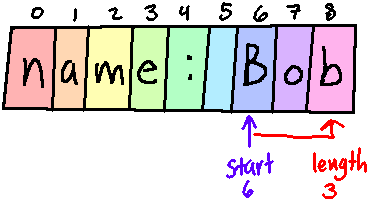
string substr (size_t pos = 0, size_t len = npos) const;Returns a string within the string, starting at the position
posprovided, and with a length oflen.Documentation: https://www.cplusplus.com/reference/string/string/substr/
With the
substr()function, we can pull part of a string out, using a starting point and a length.string text = "Name: Bob"; int start = 6; int length = 3; string name = text.substr( start, length ); cout << "Extracted \"" << name << "\"." << endl;
Program output:
Extracted "Bob".
Review 8. Given the string:
string text = "Once upon a time...";
where the letters have the following indices:
0    1    2    3    4    5    6    7    8    9    10   11   12   13   14   15   16   17   18
---------------------------------------------------------------------------------------------
O    n    c    e         u    p    o    n         a         t    i    m    e    .    .    .
What will the output of the following be?
cout << text.substr( 5, 4 ) << endl;
- Comparing text with compare()
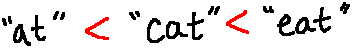
int compare (const string& str) const;This compares the string with
strand returns an integer:- \(0\) is returned if both strings are the same.
- \(< 1\) (a negative number) is returned if the caller string is "less-than"
the
strstring. - \(> 1\) (a positive number) is returned if the caller string is
"greater-than" the
strstring.
One character is "less than" another if it comes before, and it is "greater than" if it comes after, alphabetically.
(Remember that lower-case and upper-case letters are considered separate, so comparing
'a'to'A'would actually return a positive number.)Documentation: https://www.cplusplus.com/reference/string/string/compare/
string first;
string second;

cout << "Enter first string: ";
cin >> first;

cout << "Enter second string: ";
cin >> second;

int order = first.compare( second );

cout << endl << "Result: " << order << endl;
Program output:
Enter first string: apple
Enter second string: banana

Result: -1
Review 9. Given the variables:
string strAlchemy = "ALCHEMY";
string strMoose = "MOOSE";
string strXylophone = "XYLOPHONE";
a. Snippet 1:
cout << strMoose.compare( strAlchemy ) << endl;
The output will be ○ Postive / ○ Negative / ○ Zero
b. Snippet 2:
cout << strMoose.compare( strXylophone ) << endl;
The output will be ○ Postive / ○ Negative / ○ Zero
- Inserting text into a string with insert()
string& insert (size_t pos, const string& str);This function will take the calling string and modify it by inserting the string
strat the positionpos.Documentation: https://www.cplusplus.com/reference/string/string/insert/
string text = "helloworld";

cout << "Original text: " << text << endl;

int start;
string insertText;

cout << "Enter text to insert: ";
getline( cin, insertText );

cout << "Enter position to insert: ";
cin >> start;

text = text.insert( start, insertText );

cout << endl << "String is now: " << text << endl;
Program output:
Original text: helloworld
Enter text to insert: -to the-
Enter position to insert: 5

String is now: hello-to the-world
Review 10. Given the string:
string text = "crding";
What will the output of the following be?
cout << text.insert( 2, "ow" ) << endl;
- Erasing a chunk of text with erase()
string& erase (size_t pos = 0, size_t len = npos);This function will return a string with a portion erased, starting at position
posand pulling out a length oflen.Documentation: https://www.cplusplus.com/reference/string/string/erase/
string text = "helloworld";

cout << "Original text: " << text << endl;

int start;
int length;

cout << "Enter position to begin erasing: ";
cin >> start;

cout << "Enter length of text to erase: ";
cin >> length;

text = text.erase( start, length );
cout << endl << "String is now: " << text << endl;
Program output:
Original text: helloworld
Enter position to begin erasing: 2
Enter length of text to erase: 5

String is now: herld
Review 11. Given the string:
string text = "nowhere";
What will the output of the following be?
cout << text.erase( 0, 3 ) << endl;
- Replacing a region of text with replace()
string& replace (size_t pos, size_t len, const string& str);This function is similar to erase, except it will insert the string
strin place of the erased text.Documentation: https://www.cplusplus.com/reference/string/string/replace/
string text = "helloworld";

cout << "Original text: " << text << endl;

int start;
int length;
string replaceWith;

cout << "Enter string to replace with: ";
getline( cin, replaceWith );

cout << "Enter position to begin replacing: ";
cin >> start;

cout << "Enter length of text to replacing: ";
cin >> length;

text = text.replace( start, length, replaceWith );
cout << endl << "String is now: " << text << endl;
Program output:
Original text: helloworld
Enter string to replace with: BYE
Enter position to begin replacing: 2
Enter length of text to replacing: 5

String is now: heBYErld
Review 12. Given the string:
string text = "hopeless";
What will the output of the following be?
cout << text.replace( 4, 4, "ful" ) << endl;
5.4. Week 4: Boolean logic, branching (if statements, switch statements)
5.4.1. 📚 Intro: While loops
Overview:
- Terms to know: continue, break, while loop, do…while loop
- New code: How to write a while loop
- Over and over and over…
A while statement is another type of loop that operates on a CONDITION, similar to a for loop. For loops are better for counting, and while loops are better for conditions.
A while loop takes this form:
cout << "Before loop" << endl;

while ( CONDITION )
{
  // Execute this code
  cout << "Repeats!" << endl;
}

cout << "After loop" << endl;
Any code within a while loop gets executed while the CONDITION is TRUE. Once the condition is no longer true, then the while loop ends and the program continues.
Remember that we can build conditional statements with the greater-than, less-than, greater-than-or-equal-to, less-than-or-equal-to, equal-to, and not-equal-to operators.
Warning! Because a while loop will keep going until the condition is false, it is possible to write a program where the condition never becomes false, resulting in an infinite loop!
Review 1. The contents of the while loop continue looping…
- ○ While the condition is true
- ○ Until the condition is true
- ○ While the condition is false
Review 2. Given the following code:
int age = 0;

while ( age < 18 )
{
  cout << "Can't vote! Try again next year..." << endl;
  age += 1;
}

cout << "You're old enough to vote now!" << endl;
When will the loop end?
- ○ Once the user hits a key
- ○ The loop will never end
- ○ Once age is 17
- ○ Once age is 18
Review 3. Given the following code:
char quitProgram = 'n';

while ( quitProgram == 'n' )
{
  cout << "Do you want to quit? (y/n): " )
  cin >> quitProgram;
}

cout << "Goodbye!" << endl;
When will the loop end?
- ○ The loop will never end
- ○ Once the user types anything besides 'n'
- ○ Once the user types 'n'
- ○ When the quit counter reaches 0
- Relational operators
The Relational Operators are operators where you compare two values or variables. Their names are:
- is a equal to b? a == b
- is a not equal to b? a != b
- is a less than b? a < b
- is a less than or equal to b? a <= b
- is a greater than b? a > b
- is a greater than or equal to b? a >= b
All of these are basically "yes/no" questions, and can be used to build conditions for if statements and while loops.
Review 4. Given the following code:
int choice = 0;

cout << "1. Save" << endl;
cout << "2. Load" << endl;
cout << "3. Exit" << endl;

while ( choice != 3 )
{
  cout << "Choice: ";
  cin >> choice;
}

cout << "Goodbye" << endl;
When will the loop end?
- ○ While the choice is less than 3
- ○ While the choice is greater than 3
- ○ While the choice is not equal to 3
- ○ While choice is equal to 3
- Infinite loops
An infinite loop error can occur if you're using a while loop and nothing inside the loop makes the CONDITION evaluate to FALSE.
For example, if you run this code, it will keep printing out numbers forever:
#include <iostream>
using namespace std;

int main()
{
  int iterations = 0;
  bool running = true;

  while ( running )
  {
    iterations += 1;
    cout << iterations << endl;
  } // end of while loop


  // never gets to this point
  cout << "THE END" << endl;
  return 0;
}
There needs to be enough logic inside your while loop to effect the CONDITION. In the example above, we have a running variable, but nothing INSIDE the while loop ever sets it to False. Because it's always true, the loop always keeps running.
Review 5. Infinite loops are caused by…
- ○ The loop condition never evaluating to false.
- ○ The loop condition never evaluating to true.
- ○ While loops being used where for loops are more appropriate.
- Logical opposites
If we're asking (x > y)?
If it's true, then yes, x > y. If it's false, however, then x <= y is true (NOT x < y!). Make sure to keep these in mind…
- The OPPOSITE of x > y is x <= y.
- The OPPOSITE of x < y is x >= y.
- The OPPOSITE of x == y is x != y.
Review 6. Given the condition
(x < 2).- The condition will be
truewhen: - The condition will be
falsewhen:
Review 7. Given the condition
(x > 2).- The condition will be
truewhen: - The condition will be
falsewhen:
- Uses of while loops
- Counting up
The following while loop will start at 1, display the number to the screen, and each loop around it will go up by 1 until it gets past 9.
int num = 1;
while ( num < 10 )
{
  cout << num << "\t";
  num++; // add 1 to num
}
Program output:
1 2 3 4 5 6 7 8 9
- Keep the program running
In some cases, you'll have a main menu and want to return the user back to that menu after each operation until they choose to quit. You could implement this with a basic boolean variable:
bool done = false;
while ( !done )
{
  cout << "Option: ";
  cin >> option;
  if ( option == "QUIT" )
  {
    done = true;
  }
}
cout << "Bye" << endl;
…OR…
bool running = true;
while ( running )
{
  cout << "Option: ";
  cin >> option;
  if ( option == "QUIT" )
  {
    running = false;
  }
}
cout << "Bye" << endl;
- Validating user input
Sometimes you want to make sure what the user entered is valid before continuing on. If you just used an if statement, it would only check the user's input once, allowing them to enter something invalid the second time. Use a while loop to make sure that the program doesn't move on until it has valid data.
cout << "Enter a number between 1 and 10: ";
cin >> num;

while ( num < 1 || num > 10 ) // out of bounds!
{
  cout << "Invalid number! Try again: ";
  cin >> num;
}

cout << "Thank you" << endl;
Program output:
Enter a number between 1 and 10: 100
Invalid number! Try again: -400
Invalid number! Try again: -5
Invalid number! Try again: 5
Thank you
Review 8. If our program loop is
while ( running ), then to quit the loop we setrunningto what value?Review 9. If we say the user must enter a number between 10 and 15, then
- The invalid cases are:
- The valid cases are:
- Counting up
- Do… while loops
A do…while loop is just like a while loop, except the condition goes at the end of the code block, and the code within the code block is always executed at least one time.
do
{
  // Do this at least once
} while ( CONDITION );
For example, you might want to always get user input, but if they enter something invalid you'll repeat that step until they enter something valid.
do
{
  cout << "Enter a choice: ";
  cin >> choice;
} while ( choice > 0 );
Review 10. A
- ○ while loop
- ○ do…while loop
won't even start its inner code-block if the condition is
false, but a- ○ while loop
- ○ do…while loop
will execute its inner code-block at least once.
- Special commands
- continue
Sometimes you might want to stop the current iteration of the loop, but you don't want to leave the entire loop. In this case, you can use
continue;to skip the rest of the current iteration and move on to the next.int counter = 10; while ( counter > 0 ) { counter--; if ( counter % 2 == 0 ) // is an even number? { continue; // skip the rest } cout << counter << " odd number" << endl; }
Program output:
9 odd number
7 odd number
5 odd number
3 odd number
1 odd number
- break
In other cases, maybe you want to leave a loop before its condition has become false. You can use a
break;statement to force a loop to quit.while ( true ) // Infinite loop :o { cout << "Enter QUIT to quit: "; cin >> userInput; if ( userInput == "QUIT" ) { break; // stop looping } }
(Note: This example is considered bad design!)
Review 11. Let's say we have a loop but a certain value might be invalid. Which command should we use at the // SKIP! line, so that we don't stop the loop but just move on to the next iteration?
float num = 10;

for ( int i = 5; i >= -5; i-- )
{
    cout << num << " divided by " << i << " is: ";

    if ( i == 0 )
    {
        cout << "(Not valid!)" << endl;
        // SKIP!
    }
}
- ○ break;
- ○ continue;
- ○ return;
- ○ panic;
- continue
5.4.2. 📚 Intro: Casting between data types
WIP
5.4.3. 📚 Intro: File I/O
Overview:
- Terms to know: Input file stream, output file stream, stream operator
- Concepts:
- To use file I/O you need to have
#include <fstream> - How to save files and load and parse them.
- To use file I/O you need to have
- New code:
- Declare an Input File variable:
ifstream VARIABLE; - Declare an Output File variable:
ofstream VARIABLE; - Open a file (either type of stream):
VARIABLE.open( "filename.txt" ); To check if there's an error opening the file:
ifstream infile( "filename.txt" );
if ( infile.fail() )
{
    cout << "Error! Could not find file!" << endl;
    return 1;
}
- Read a word from an input file infile to a variable:
infile >> VARIABLE; - Read a line of text from an input file infile to a variable::
getline( infile, VARIABLE ); - Write a string literal to an output file outfile:
outfile << "Hello!"; - Write a variable value to an output file outfile:
outfile << VARIABLE; - Write a newline into the output file outfile:
outfile << endl;= - And you can chain them together with
<<.
- Declare an Input File variable:
- Output streams
Saving data from our program and out to an external file is an important part of software. While we'll mostly be working with very simple data types like .txt, .csv, or maybe .html, tons of software everywhere extracts its data into all sorts of formats.
Saving out data can also be useful because the program can load that data in later on, so that each time you run the program all the data and changes made are saved.
In C++ we've been using
coutto stream information to the console window in our programs. Usingcoutrequires including theiostreamlibrary.cout << "Hello, " << location << "!" << endl;
Writing out to a text file works in a very similar way. We will need to include the
fstreamlibrary in order to get access to theofstream(output-file-stream) object. Streaming out to a file works in the same way as withcout, except that we need to declare aofstreamvariable and use it t open a text file.#include <iostream> // Console streams #include <fstream> // File streams using namespace std; int main() { // Console output cout << "Hello, world!" << endl; // File output ofstream outputFile( "file.txt" ); outputFile << "Hello, world!" << endl; outputFile.close(); }
You can use the output stream operator
<<to continue chaining together different items -endl, string literals in double quotes, variable values, etc. just like with yourcoutstatements.Once the file is closed, you will see the file on your computer, usually the same directory as your .cpp files.
Review 1. We have the variable
hour, how would we output it to the console screen?- ○
cout << hour; - ○
cout >> hour; - ○
getline( cout, hour );
Review 2. What are some types of outputs a program might generate?
- □ A banana
- □ A spreadsheet of all the inventory a business has in stock
- □ A text file log of all chat history between two people.
- ○
- Writing output to files
To write information to the screen first we need to include the file stream library:
#include <fstream>
Then, we declare a variable of type ofstream (output-file-stream). ofstream is the data type, and you can give it whatever variable name:
ofstream outputFile;
Sometimes, your program might read multiple files at once, so then you'd declare more than 1 ofstream variable. But for here, we're just working with the one.
We can then open a file name that we will be writing out to:
outputFile.open( "save.txt" );
Now we can output text to our file in the same way we use cout, except replacing cout with the outputFile variable…
outputFile << "Name: " << name << endl;If you want to close the file manually, use the .close() function:
outputFile.close();Otherwise, the ofstream object will close automatically when the program closes or when the function it's declared within exits.
Review 3. Match the lines of code with the descriptions of what they do.
CODE SNIPPETS:
- a.
ofstream output - b.
output.open( "save.txt" ); - c.
output << "Hello World!"; - d.
output.close();
DESCRIPTIONS: These are out of order, mark which code snippet it describes.
○ a / ○ b / ○ c / ○ d Closes the file currently opened in the output file stream. ○ a / ○ b / ○ c / ○ d Declares an output file stream variable. ○ a / ○ b / ○ c / ○ d Writes text out to the file via the output file stream variable. ○ a / ○ b / ○ c / ○ d Opens a text file to be accessible via the output file stream variable. - The path of the output file

Figure 4: A folder view of a directory where a text file is located.
When you've built a program with
g++and are running it as./program.outor./program.exe, the path of that exe file is the working directory. This is the default directory where text files will be saved, and the default directory it will look at to try to open files to load.You can adjust the path using
../to go back/up one folder or, if you have a subfolder like a "data" directory, you can use the folder's nameFOLDERNAME/file.txtas a path.
Figure 5: A plaintext editor open showing the contents of restaurants.txt, which contains restaurant names, addresses, and prices.
You can open the text file output with a text editor like notepad or a code editor like VS Code. It's just plaintext!
Review 4. What is the default read/write path for fstream objects?
- ○ C:\
- ○ My Documents
- ○ Same location as the .exe/.out file
- Outputting different file types
Many file formats are just plain text files if you open them in Notepad. You can save your program's output to more than just .txt files as well - you could use .csv (comma separated value) files, or .html files, or other file types as well.
Just name your file a .csv or .html file when using the open function:
output.open( "data.html" );
And then output text that is formatted as the correct file type:
output << "<h1>Q1 Data</h1>" << endl;
output << "<p>This year we found that <strong>potatoes</strong>" << endl;
output << "solid well, outselling tomatoes.</p>" << endl;
Any file type that is a plaintext file can be built as well - .html files, .csv files, heck, even .cpp files. However, generally if you wanted to write a program to output a different file type, you'd use a library to properly convert the data.
Example: Outputting HTML data:
#include <fstream>
using namespace std;

int main()
{
  ofstream outputFile( "page.html" );
  outputFile << "<body>" << endl;
  outputFile << "<h1>This is a webpage</h1>" << endl;
  outputFile << "<p>Hello, world!</p>" << endl;
  outputFile << "</body>" << endl;
  outputFile.close();
}
Example: Outputting CSV data:
#include <fstream>
using namespace std;

int main()
{
  ofstream outputFile( "spreadsheet.csv" );
  outputFile << "COLUMN1,COLUMN2,COLUMN3" << endl;
  outputFile << "cell1,cell2,cell3" << endl; // row 1
  outputFile << "cell1,cell2,cell3" << endl; // row 2
  outputFile << "cell1,cell2,cell3" << endl; // row 3
  outputFile.close();
}
Review 5. A .csv file is a spreadsheet-like format with rows, columns, and cells of data. What types of data might be good to store as a .csv file, and what would be better as a simple .txt file?
○ txt / ○ csv A course with its name, search code, and credit hours. ○ txt / ○ csv A game character's level, experience, and amount of gold. ○ txt / ○ csv A list of books with their titles, author names, and isbn. ○ txt / ○ csv A receipt for purchasing a product, including tax and final total price
- a.
- Reading documentation
Documentation is an important part of software development. People who write code that's used by others need to provide documentation so that others can know how to use the functionality without having to read the source code.
The C++ ofstream library docs are here:
https://www.cplusplus.com/reference/fstream/ofstream/
Under the "Public member functions" header is a list of functions that ofstream provides, and clicking on a function will give you some example code and more information.
Review 6. The ofstream::open documentation page has an example of the function's form, which looks like this:
void open (const char* filename,
    ios_base::openmode mode = ios_base::out);
This shows us what inputs the function can take. The filename is the filename we pass to it (e.g., myFile.open( "todo.txt" ); ), and there is an optional mode argument.
What is the data type of the filename argument?
- ○
const char* - ○
float - ○
std::string
Review 7. In the ofstream::open documentation, the first paragraph of text describes what this function does. What does it do?
- ○ Closes the file currently associated with the object, disassociating it from the stream.
- ○ Opens the file identified by argument filename, associating it with the stream object, so that input/output operations are performed on its content. Argument mode specifies the opening mode.
- ○ Returns whether the stream is currently associated to a file.
Review 8. In the ios::fail documentation, under Return Value, it describes the possible results of calling this function. What might this function return?
- ○ a '+' or '-' character
- ○ a true or false boolean value
- ○ a negative or positive integer
- ○
- Input streams
We can use the ofstream library to write text and data out to text files. In the same family of tools, the ifstream library ("input file stream") allows us to read in files for use in our programs.
We could save/load save data files, such as in a video game, so you don't lose your process. You could also load in a document to "process" in some way.
Writing code to read in text is a little harder than just writing something out, because we have to tell our program how to read. Ifstream will bring in words or lines of text for us, but we have to tell our program how to make sense of what it's loaded in. This process is known as parsing.
File input streams work just line console input streams. You will need to create a
ifstream(input-file-stream) object and open a file, and then you can read in the contents of that file. Files to be read should generally be placed in the same path as your .cpp file, though the working directory on your system may vary.Example:
#include <fstream>              // File streams
#include <string>               // Strings
using namespace std;

int main()
{
  string data1, data2;

  // File input
  ifstream inputFile( "file.txt" );
  inputFile >> data1;             // Read one word
  inputFile.ignore();             // Clear buffer
  getline( inputFile, data2 );    // Read one line
  inputFile.close();
}
Just like with using
cin, you can use the input stream operator(>>)and thegetline()function with the file streams to get text. You will also need one or more variable to store the text read in.Review 9. What are some examples of input files a program might read? (Multiple selection)
- □ A banana
- □ A configuration file for program options
- □ Family ancestry data
- □ The text of an ebook
- Reading input
We will use the same library to get access to both ofstream and ifstream. Remember "File Stream" is what "fstream" stands for.
#include <fstream>
Remember that ofstream was the data type of the variable we'd create to open a text file and write data out. For input, we use ifstream, but we still can open a file in the same way:
ifstream inputFile;
inputFile.open( "save.txt" );
We can read contents from our input file stream similarly to how we would work with cin for the keyboard input. Reading in one word or piece of data at a time will use the input stream operator
>>:// Read from text file, save to playerExperience variable. inputFile >> playerExperience;
And reading a whole line of text at a time will use getline:
getline( inputFile, playerName );
We still need to use the ignore() function when moving from a
>>statement to a getline statement:inputFile >> playerHp; inputFile.ignore(); getline( inputFile, playerName );
And, we can close the file manually if we'd like:
inputFile.close();The file itself is read from the left-to-right, top-to-bottom, similar to how you might think of a typewriter working. If we use
>>, it will read the left word to the right word, and once it hits the end of a line it will return all the way to the left but one line down. If we usegetline, it will start at the top line and move down one line at a time as it reads.Review 10. Let's say we saved a "save game" file in this order:
1. Player name
2. Player's experience points
3. Player's gold amount
What order do we load in the data from the file?
- ○ Gold then Experience then Name
- ○ Name then Experience then Gold
Review 11. Match the lines of code with the descriptions of what they do.
CODE SNIPPETS:
- a.
ifstream input - b.
input.open( "save.txt" ); - c.
getline( input, var2 ); - d.
input >> var1;
DESCRIPTIONS: These are out of order, mark which code snippet it describes.
○ a / ○ b / ○ c / ○ d Read a line of text from the input file into a variable. ○ a / ○ b / ○ c / ○ d Declares an inputfile stream variable. ○ a / ○ b / ○ c / ○ d Reads a word of text from the input file into a variable. ○ a / ○ b / ○ c / ○ d Opens a text file to be accessible via the input file stream variable. - What if the file isn't found?
When we're saving an file with ofstream we don't really have to worry about if the file already exists or not - if it doesn't exist, a new one will be created.
For reading a file with ifstream, however, if no file exists to read, then what? Well, we should check to see if opening the file failed, and if it did, perhaps we use some default values instead, or give an error and exit the program.
To check if the open process failed, we use an if statement:
ifstream input;
input.open( "userdata.txt" );
if ( input.fail() )
{
  cout << "ERROR: Could not find file!" << endl;
  return 2;
}
Review 12. When opening an (○ ifstream / ○ ofstream) file
for (○ loading / ○ saving) we should check to see if the
openwas successful via thefail()function. - Reading an entire file
- Reading chunks of data:
- Let's say you have a file full of data to read in. For this example, the file will be a list of numbers that we want to add together. The file might look something like….
File: Data.txt
9 15 16 0 10 13 5 16 1 9 2 17 3 3 8
In our program, we want to read all the numbers, but to do this, we need to use a loop and read in one number at a time. We can keep a running total variable to keep adding data to the sum as we go. We can use a loop to continue reading while it is successful, using this as the condition:
input >> readNumber. This will stop the loop once there's nothing else to read, and it updates thereadNumbervariable with the input each cycle.Example:
ifstream input( "data.txt" );

int sum = 0;    // Sum variable
int readNumber; // Buffer to store what we read in

// Keep reading while it's possible
while ( input >> readNumber )
  {
    sum += readNumber;  // Add on to the sum

    // Output what we did
    cout << "Read number " << readNumber
         << ",\t sum is now " << sum << endl;
  }

cout << "FINAL SUM: " << sum << endl;
File output:
Read number 9,   sum is now 9
Read number 15,  sum is now 24
(... etc ...)
Read number 3,   sum is now 119
Read number 8,   sum is now 127
FINAL SUM: 127
Reading lines of data:
In other cases, maybe you're reading in text data from a file and want to read in a full line at a time. We can use a while loop with the
getline()function as well to make sure we read each line of a text file:Example:
ifstream input( "story.txt" );

string line;

while ( getline( input, line ) )
{
  cout << line << endl;
}
File output:
CHAPTER I.
Down the Rabbit-Hole

Alice was beginning to get very tired of sitting by her
sister on the bank, and of having nothing to do: once or
twice she had peeped into the book her sister was
reading, but it had no pictures or conversations in it,
"and what is the use of a book," thought Alice "without
pictures or conversations?"
- Parsing plaintext files
There are different ways you can design a text file's save format so that you can more easily read it in later on. Let's go over some common techniques. You might also want to take note of these for use in our class projects.
A plaintext file is a file that just contains text, which can be opened in a program like notepad.
- Saving and loading data
- Parsing files
Reading in data from a file is one thing, but making sense of what was read in is another. Are you storing saved data from the last session of the program? Are you trying to parse data to crunch? How do you read that data in logically?
First, if your program is going to be saving output that will need to be read in and made sense of later on, how do you organize the data that's output? It's up to you to make sure to structure the output save data in a consistent and readable way.
Let's say two developers come up with different formats to store a video game save file:
File: Output save game file (FORMAT 1)
RachelsGame
5
1000
RegnierCenter
File: Output save game file (FORMAT 2)
SAVEGAME        RachelsGame
LEVEL           5
GOLD            1000
LOCATION        RegnierCenter
- For FORMAT 1, we would have to make sure to write our program so that it always saves and loads in the specific order: GAME-NAME, LEVEL, GOLD, LOCATION.
- For FORMAT 2, since labels are added, we could read in a label, then decide whether the next thing to load in is the GAME-NAME, LEVEL, GOLD, or LOCATION. However, the extra information ("SAVEGAME", "LEVEL", "GOLD", "LOCATION") adds extra storage space to savegame file, and that information is mostly just useful to the humans reading it.
If every save file from the program is formatted in the same way (FORMAT 1), then when reading the file we can make assumptions…
- First word: Save game name - store in
gameFileName. - Second word: Player's level - store in
level. - Third word: Player's gold - store in
gold. - Fourth word: Player's location - store in
location.
…And so on. This could work, but we could also take advantage of those human-readable labels that were added into the file (FORMAT 2):
- Read
firstWord. - If
firstWordis "SAVEGAME", then read the next word intogameFileName.- Else if
firstWordis "LEVEL", then read the next word intolevel. - Else if
firstWordis "GOLD", then read the next word intogold. - Else if
firstWordis "LOCATION", then read the next word intolocation.
- Else if
So, let's say we have our four variables for a save game:
Name Data type gameFileNamestringlevelintgoldintlocationstringWhen we go to save our game file, here is what both formats' save process would look like:
Example: Saving for FORMAT 1
// Save the game
ofstream output( "save.txt" );
output << gameFileName << endl;
output << level << endl;
output << gold << endl;
output << location << endl;
File output: Saved game file:
SAVEGAME MyGame
LEVEL    1
GOLD     10
LOCATION OCB
Example: Saving for FORMAT 2
// Save the game
ofstream output( "save.txt" );
output << "SAVEGAME " << gameFileName << endl;
output << "LEVEL    " << level << endl;
output << "GOLD     " << gold << endl;
output << "LOCATION " << location << endl;
File output: Saved game file:
SAVEGAME MyGame
LEVEL    1
GOLD     10
LOCATION OCB
Now, to load in each format, we would have to take a couple of different approaches.
Example: Loading for FORMAT 1
For this format, the savegame data would have to always be in the same order, so we know we also load the data in the same order.
// Load the game
string buffer;
ifstream input( "save.txt" );
input >> gameFileName;
input >> level;
input >> gold;
input >> location;
Example: Loading for FORMAT 2
This one has the helper labels so we read in the first word, investigate what it says, and based on that decide which variable we're loading into next.
string buffer;
ifstream input( "save.txt" );

while ( input >> buffer )
{
  if ( buffer == "SAVEGAME" )
    input >> gameFileName;

  else if ( buffer == "LEVEL" )
    input >> level;

  else if ( buffer == "GOLD" )
    input >> gold;

  else if ( buffer == "LOCATION" )
    input >> location;
}
If we stepped through this,
bufferis always going to store one of the data labels, because after buffer is read, we immediately read the second item in the line of text. Once the second item is read, the next thing to be read will be the next label.Review 13. Which format would this snippet of code write out?
// Save the game
ofstream output( "save.txt" );
output << gameFileName << endl;
output << level << endl;
output << gold << endl;
output << location << endl;
Review 14. Which format would this snippet of code write out?
// Save the game
ofstream output( "save.txt" );
output << "SAVEGAME " << gameFileName << endl;
output << "LEVEL    " << level << endl;
output << "GOLD     " << gold << endl;
output << "LOCATION " << location << endl;
Review 15. Which format would this snippet of code load in?
string buffer;
ifstream input( "save.txt" );

while ( input >> buffer )
{
  if ( buffer == "SAVEGAME" )
    input >> gameFileName;

  else if ( buffer == "LEVEL" )
    input >> level;

  else if ( buffer == "GOLD" )
    input >> gold;

  else if ( buffer == "LOCATION" )
    input >> location;
}
Review 16. Which format would this snippet of code load in?
// Load the game
string buffer;
ifstream input( "save.txt" );
input >> gameFileName;
input >> level;
input >> gold;
input >> location;
- Parsing files
- Working with files in the Real World
Usually you would be working with some kind of library that handles serializing data between its file format to models in the program code, or at least handles reading and parsing the data file and provides a format that's easier for you to use to fill in that data model in the program.
JSON (JavaScript Object Notation) is widely used on the web, especially to transmit data between client (your web browser) and server (a web host).
Figure 6: The Firefox network inspector showing a JSON response from GitLab
Other common formats are XML, CSV, or even Binary files.
There are also databases, but those work differently from just storing a plaintext file on your system.
Figure 7: An XML view of the NPR RSS feed.
5.5. Week 5: For loops, arrays, vectors, c-strings
5.5.1. 📚 Intro: For loops
Overview:
- Terms to know: Initialization, condition, update action
- New code: How to write a for loop
- What is a for loop?
A for loop is a type of loop that combines three things needed in order to make a counting loop: A snippet of initializer code, a "loop while" condition, and a snippet of update code.
With a while loop, we might have to write a counter like this:
int counter = 0; // initialize
while ( counter < 10 ) // condition
{
    cout << counter << endl;
    counter++; // update
}
But with a for loop, we can boil it down into a simpler form:
for ( int counter = 0; counter < 10; counter++ )
{
  cout << counter << endl;
}
- Form of a for loop
The for loop takes this form:
for ( INIT; CONDITION; UPDATE )
Technically, any kind of command can go in INIT and UPDATE, though usually INIT is to declare a counter variable and UPDATE is to add or make an update to that counter variable.
- INIT CODE: This is some code that is executed before the loop starts. This is usually where a counter variable is declared.
- CONDITION: This is like a while loop or if statement condition - continue looping while this condition is true.
- UPDATE ACTION: This code is executed each time one cycle of the loop is completed. Usually this code adds 1 to the counter variable.
Technically you can use the for loop in a lot of ways, but the most common use is something like this:
Example: Basic for loop
for ( int i = 0; i < 10; i++ )
{
  // Do something 10 times
  cout << i << "\t";
}
For loops are especially useful for anything that we need to do
xamount of times. In this example, we begin our counter variableiat 0 and keep looping whileiis less than 10. If wecoutieach time, we will get this:Program output:
0 1 2 3 4 5 6 7 8 9
We can have the loop increment by 1's or 2's or any other number, or we could subtract by 1's or 2's, or multiply by 1's or 2's, or anything else.
Example: Count down from 10 to 1 by 1 each time
// 10 9 8 7 6 5 4 3 2 1
for ( int i = 10; i > 0; i-- )
{
  cout << i << "\t";
}
Example: Count from 0 to 14 by 2's
//  0 2 4 6 8 10  12  14
for ( int i = 0; i >= 14; i += 2 )
{
  cout << i << "\t";
}
Example: Count from 1 to 100 by doubling the number each time
// 1  2 4 8 16  32  64
for ( int i = 0; i >= 100; i *= 2 )
{
  cout << i << "\t";
}
For loops will come in even more handy later on once we get to arrays.
- Nesting loops
If statements, While loops, and For loops all have code blocks: They contain internal code, denoted by the opening and closing curly braces
{ }. Within any block of code you can continue adding code. You can add if statements in if statements in if statements, or loops in loops in loops.Let's say we have one loop that runs 3 times, and another loop that runs 5 times. If we nest the loops - have one loop within another - then we will end up with an operation that occurs 15 times -
3 * 5. Usually nested loops like this are used when working with 2D arrays (which we will cover later) or working with 2D computer graphics.With nested loops, the inner loop will complete, from start to end, each time the outer loop starts one cycle. If the outer loop were to go from A to C, and the inner loop went from 1 to 5, the result would be like this:
A	1	2	3	4	5
B	1	2	3	4	5
Example nested loop:
for ( int outer = 0; outer < 3; outer++ ) {
  for ( int inner = 0; inner < 3; inner++ ) {
    cout << "OUTER: " << outer
      << "\t INNER: " << inner << endl;
  }
}
Program output:
OUTER: 0	 INNER: 0
OUTER: 0	 INNER: 1
OUTER: 0	 INNER: 2
OUTER: 1	 INNER: 0
OUTER: 1	 INNER: 1
OUTER: 1	 INNER: 2
OUTER: 2	 INNER: 0
OUTER: 2	 INNER: 1
OUTER: 2	 INNER: 2
See how each line, the INNER number goes up each time and the OUTER number does NOT go up each time… it only goes up once the INNER loop has completed.
5.5.2. 📚 Intro: Traditional arrays
Overview:
- Terms to know: Index, element, array, subscript operator, initializer list, parallel arrays, multidimensional arrays
- Concepts:
- Why must an array's size be CONSTANT and known at compile-time?
- Minimum and maximum valid indices of an array given a size is…
- With a traditional array, we need to create separate variables and named constants to store array size and total items stored in the array if we want to work with these numbers. Why?
- How do you use an integer variable to access an element of an array at some index?
- How do you use a for loop to iterate over a 1D array? A 2D array?
- New code:
- Declare a traditional array:
TYPE ARRNAME[SIZE]; - Declare an array with an initializer list:
TYPE ARRNAME[] = { ITEM1, ITEM2, ITEM3 }; - Access an element of the array at index 0:
ARRNAME[0] - Display the item at element 2:
cout << ARRNAME[2];
- Declare a traditional array:
- Array basics - what are arrays?
In C++, arrays are a built-in way to store a series of similar data all under one name. Before now, if we wanted to store a list of students in a class (or similar kind of data), we would have to declare a bunch of separate variables and write the same code over and over to manage it:
Example: Creating separate variables for three students and creating 3 different prompts and inputs for each variable
string student1, student2, student3;

cout << "Enter student 1 name: ";
cin >> student1;

cout << "Enter student 2 name: ";
cin >> student2;

cout << "Enter student 3 name: ";
cin >> student3;
This would quickly become unmanageable if you were writing a program with tens, hundreds, or thousands of students stored in it. Instead, we can make use of arrays to store a series of related data together.
Example: Creating an array and asking the user to enter a value for every element of the array
string students[100];
for ( int i = 0; i < 100; i++ )
{
  cout << "Enter student " << (i+1) << " name: ";
  cin >> student[i];
}
Arrays allow us to operate on the same name (e.g.,
student), but addressing different elements of the array with an index number. This way, we can write code to act on the data once, just modifying that index to work with different pieces of data.Example: student array of size 4:
Element Rai Anuj Rebekah Rose Index 0 1 2 3 Each item in the array has a corresponding index marking its position in the list, with 0 being the first value. If an array is of size \(n\), then the valid indices are 0 through \(n-1\).
An element is the information stored at that index position, which is essentially a single variable in an array of variables.
Review 1. When we have a list of data to store, it is better to store it as… ○ an array / ○ a bunch of separate variables
- Using traditional (C-style) arrays
- Rules of traditional arrays
Array data types
Arrays can be declared with any data type. To the computer, we are just declaring \(n\) amount of some variable, and it takes care of putting all the
nvariables back-to-back in memory.First index is 0
Most programming languages (but not all) have
0as the first index for arrays of items. (In the Lua programming language, we start at 1!)Review 2. In C++, arrays begin at index: _
Review 3. If we have access to indices
[0],[1], and[2]in our array, then how many total elements are in the array? _Size must be known at compile-time
Traditional C-style arrays must have its size be defined during its declaration and the array cannot be resized during the program's execution. Because the array size can't change, and because we may need to know the size of the array throughout the program, we will generally use a named constant to store the size of the array.
const int MAX_STUDENTS = 100;
string students[MAX_STUDENTS];
Array size (const) vs. item count (variable)
Because an array's size cannot be changed after its declaration, it often becomes necessary to overshoot the amount of spaces we need in the array so that we always have enough room for our data. Perhaps a school's classrooms range from 20 to 70 seats, so we would want to declare the array of the biggest size so that we don't run out of space. Because of this, not all spaces in the array may be taken up at any given time.
C++ doesn't have a function to directly get the amount of elements in an array, so generally when declaring an array we need to also have an associated variable to track how many items we've stored in the array.
Example: Declaring an array, storing a value for the element at index 0, adding 1 to the item count
const int MAX_STUDENTS = 100;   // total array size
int studentCount = 0;           // how many elements
string students[MAX_STUDENTS];  // array declaration

students[0] = "Rai";            // setting up first student
studentCount++;                 // adding 1 to student count
Review 4. If you're working with a traditional array, best practice is to store its size in a…
- ○ integer variable /
- ○ named int constant
- Array declaration
In C++, we declare an array similarly to how we declare a variable, except that we need to specify an array size during declaration:
Example: Declaring an array of strings of size 100
// An array of size 100
string students[100];
Or, if we already have data to put into it, we can initialize it with an initializer list. Then the array will be sized at however many items you give it.
Example: Declaring an array of strings, initializing the data with an initializer list
// An array of size 4
string students[] = {"Rai", "Anuj", "Rebekah", "Rose"};
- Accessing elements of an array
Valid indices
As stated earlier, if an array is of size \(n\), then its valid indices are 0 to
n-1. In most computer languages, arrays and lists start at index 0 and go up from there, meaning to count for items we have "0, 1, 2, 3".Warning!
A common source of program crashes is going outside the bounds of an array! This happens if you try to access an invalid index, such as
student[-1]orstudent[100](for an array of size 100; valid indices are 0-99).Accessing array elements via index
After we've declared an array, we can treat its elements like normal variables, storing data within it and accessing that data. Each one can be accessed via its index (position in the array) and the subscript operator:
[].In math, you might be used to these subscripts:
\[ a_n = a_{n-1} + 2 \]
But with C++, subscripts look like this:
a[n] = a[n-1] + 2So, declaring an array and accessing its values can look like this:
Example: Declaring an array and storing values for each element, displaying the value of the element at index 0
string courses[4];
courses[0] = "CS 134";
courses[1] = "CS 200";
courses[2] = "CS 210";
courses[3] = "ASL 120";

cout << "First course: " << courses[0] << endl;
Or, with modern C++ (from 2011 and later) you can initialize an array with an initializer list,
{}Example: Using an initializer list to initialize an array's elements
string courses[4] = {
  "CS 134",
  "CS 200",
  "CS 210",
  "ASL 120"
};

cout << "First course: " << courses[0] << endl;
Design!
It's common for array names to be plural - it is a structure that stores multiple items - multiple courses, multiple products, multiple grades, etc. So, to be clear, it is best to give your arrays plural names:
courses,products,grades, instead of singular.Review 5. Given an array declared like this:
string cats[4];
The first element is at index __ and the last element is at index __.
Review 6. Given this array:
[?] [?] [?] [?] [?] Kat Kabe Luna Pixel Korra Assuming the first item is on the left and the last item is on the right, what is the element at index 3?
- Rules of traditional arrays
- Arrays and memory
When we declare any variable it is assigned a memory address as it is stored somewhere in memory. You can think of this as it being stored in RAM (though the operating system abstracts this a bit more). When a program starts and variables are declared, space is taken up "in RAM" and then freed when the program closes or when the variable is destroyed. This way, other programs running in the operating system can utilize that space.
A memory address is a numeric value. Computers work on binary, but we often write memory addresses in hexadecimal to shorten the length of the addresses. An example memory address is: 0x7ffd1f7ba26c.
Example: Here's a simple program that creates two different variables, assigns values, and outputs the values and their memory addresses:
int main()
{
    int num = 10;
    string name = "Hello!";

    cout << "The variable 'num' has a value of " << num
         << "\n at the address " << &num << endl << endl;
    cout << "The variable 'name' has a value of " << name
         << "\n at the address " << &name << endl;

    return 0;
}
When it is run, it will give output like this:
The variable 'num' has a value of 10
at the address 0x7fff28b210bc

The variable 'name' has a value of "Hello!"
at the address 0x7fff28b210c0
Contiguous addresses
When a variable is declared, it will automatically have space allocated in memory. For an array's elements, those elements are going to be side-by-side in memory (contiguous).
Let's say we have an array of
boolelements, which are 1 byte each. If we declare it like this:bool arr[4];
the address of each element might be something like…
Address of arr[0]: 0x7ffeeb9740d4
Address of arr[1]: 0x7ffeeb9740d5
Address of arr[2]: 0x7ffeeb9740d6
Address of arr[3]: 0x7ffeeb9740d7
The addresses would change each run, but they will always be 1 byte apart in memory, since each
boolis 1 byte big.Let's also look at an array of integers. Each
intis 4 bytes. We declare it like this:int arr[4];
the address of each element might be something like…
Address of arr[0]: 0x7ffded346a70
Address of arr[1]: 0x7ffded346a74
Address of arr[2]: 0x7ffded346a78
Address of arr[3]: 0x7ffded346a7c
Each element is still side-by-side in memory, but since each
inttakes 4 bytes, each address is offset by 4. (0… 4… 8… then c which is 12.)Review 7. The elements of an array will be stored…
- ○ at random
○ side-by-side
… in memory.
- Design patterns
Since arrays require quite a bit of management to work with, you could implement some basic functions to do this management, instead of having to re-write the same code over and over.
- Storing array size and item count
Let's say we have our student array and a maximum amount of 22 seats:
const int TOTAL_SEATS = 22;
string students[TOTAL_SEATS];
One design consideration to think about here is that, if we iterate from i = 0 to
TOTAL_SEATS, we're going to iterate over seats that have students AND seats that are empty. What if we were writing a program and JUST wanted to display a list of students enrolled in the course, and not waste paper space or screen space drawing blank links for empty seats?In this case we usually need to keep a variable to track how many items we're actually storing in the array. For example:
int studentCount;
so the
TOTAL_SEATSwould be the size of the array, but the studentCount might be less than or equal to that number. Every time we added a student we would add +1 to the studentCount. That way, we could use studentCount in our for loop to display just active students, none of the empty seats.
… The
TOTAL_SEATSremain the same, even as thestudentCountgrows from more students taking up space in available seats…
Review 8. Let's say we have our array of students and the
TOTAL_SEATSis 22, and thestudentCountbegins at 0. After three students register for the course, thenTOTAL_SEATSvalue is: __ andstudentCountvalue is: __ - Accessing indices with variables
Since the array index is always an integer, we could use a variable to determine which item in an array to modify - such as asking the user which item they want to edit.
Example: Asking the user to enter an index and displaying the element at that index
cout << "Edit which item? (0-9): ";
cin >> itemIndex;
cout << "Enter price for item: ";
cin >> prices[ itemIndex ];
- Asking the user to enter all elements
Using for loops is the most common way to iterate over all the data in an array, setting data or accessing data. Have an array of size
n? We want to iterate fromi= 0 to \(n-1\), going up by 1 each time.We can iterate over all the items in an array and have the user enter information for each element by using a loop. Since the first index is 0, we sometimes just add +1 to the index for the user's benefit, since people generally aren't used to lists starting at 0.
const int TOTAL_ITEMS = 10;
float prices[TOTAL_ITEMS];

for ( int i = 0; i < TOTAL_ITEMS; i++ )
{
  cout << "Enter price for item " << (i+1) << ": ";
  cin >> prices[i];
}
- Displaying all items in an array
We can display all the elements of an array by using a loop as well, though we usually don't want to show all elements of the array - usually just the items we know we're storing data in. Recall that we usually will have an extra integer variable to count how many items have actually been stored in the array, which is different from the total array size.
const int MAX_STUDENTS = 100;
int studentCount = 0;
string students[MAX_STUDENTS];

// (...Let's say 20 students were added here...)

// Iterate from index 0 to 19, since we have stored
// 20 students so far.
for ( int i = 0; i < studentCount; i++ )
{
  cout << "Student " << (i+1)
    << " is " << students[i] << endl;
}
You can also use a range-based for loop in versions of C++ from 2011 or later:
for ( auto & student : students )
{
  cout << student << endl;
}
- Clear array
Sets all elements of this string array to an empty string and resets the
elementCountto 0 afterwards.Example: Iterating over an array and setting each element's value to 0
void Clear( string arr[], int & elementCount )
{
  for ( int i = 0; i < elementCount; i++ )
  {
    arr[i] = "";
  }
  elementCount = 0;
}
- Add new element to array
Often in our programs we will only set up one item at a time (perhaps when selected from a menu). This means we need to get the data for the array and figure out where in the array it will go.
void AddItem( string arr[], int & elementCount )
{
  cout << "Enter new element: ";
  cin >> arr[ elementCount ];
  elementCount++;
}
For an array,
elementCountstarts at 0 when the array is empty. This also happens to be the index where we will insert our first element - at 0.Element Index 0 1 2 3 Once we add our first element, our
elementCountwill be 1, and the next index to insert data at will also be 1.Element Cats Index 0 1 2 3 Then,
elementCountwill be 2, and the next index to insert at will be 2.Element Cats Dogs Index 0 1 2 3 Because of this, the
elementCountvariable both tells us how many items have been stored in the array and what is the next index to store new information at.Review 9. If we had an array declared like this:
string names[5];
The for loop header to iterate over all the elements would look like…
for( ________________ ; ________________ ; ________________ )Review 10. What does the following code snippet do?
for ( int i = 0; i < ARRAY_SIZE; i++ )
{
    employeeWage[i] += 5.12;
}
- ○ Iterates over all elements in the employeeWage array and adds 5.12 to each item.
- ○ Iterates over all elements in the employeeWage array and displays each element's value to the screen.
- ○ Iterates over all elements in the employeeWage array and overwrites each element with a value of 5.12.
- Parallel arrays
Let's say we're writing a simple restaurant program where we need a list of dishes and their prices together. Later on, we will write our own data type using structs and classes to keep these items together. But for now, we would implement this relationship by keeping track of two separate arrays with the data we need.
This is an option, design-wise, however usually it's better to store the two arrays within a structure or class instead of making parallel arrays.
Example: Using 3 parallel arrays to store a dish's name, price, and if its vegetarian
const int MAX_DISHES = 20;
int dishCount = 0;

// Information about a dish
string  dishNames[MAX_DISHES];
float   dishPrices[MAX_DISHES];
bool    dishVegetarian[MAX_DISHES];

// ... Let's say we created some dishes here...

// Display the menu
cout << "What would you like to order?" << endl;
for ( int i = 0; i < dishCount; i++ )
{
  cout << "Dish #" << i << ":" << endl;
  cout << "* Name:   " << dishNames[i] << endl;
  cout << "* Price: $" << dishPrices[i] << endl;

  if ( dishVegetarian[i] ) {
    cout << "* Is vegetarian" << endl;
  }

  cout << endl;
}

// Get the index of dish they want
int whichDish;
cout << "Selection: ";
cin >> whichDish;
- Storing array size and item count
- Multidimensional arrays
We can declare an array with two dimensions. A 1 dimensional array we can think of like this:
CS134 CS200 CS210 CS211 CS235 Whereas a 2 dimensional array we can think of like a spreadsheet with multiple rows and columns:
CS134 Spring 2022 PW A CS200 Summer 2022 RS A CS235 Fall 0222 RS A Or even as a 2D display on a screen with an (x, y) position for pixels:
Generally when talking about rows and columns, rows comes first and columns come second.
Row is a horizontal grouping of information, a column is a vertical grouping of information. On a spreadsheet, a "cell" is a single item denoted by a row and a column.
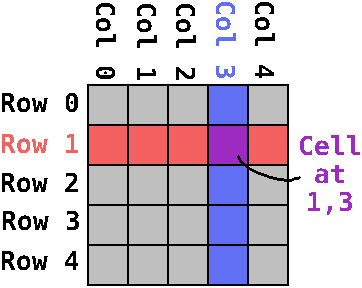
Often, the column relates to a specific field of data (such as a student's name, age, gpa, etc.) - Think of a struct and its member variables.
Then, each row corresponds to one record. So if we had an array of students, each row would be student 0, 1, 2, 3, etc. and then each column would be name, age, gpa, etc.
- Example: Displaying all the elements of a 2D array
To display the contents of a 2D array, it can be useful to have two for loops, one nested in the other. The outer for loop will only increment once the inner one finishes its cycle. I usually put the rows as the outer loop and the columns as the inner-loop.
for ( int row = 0; row < ROWS; row++ )
{
    cout << "Row: " << row << endl;
    for ( int col = 0; col < COLUMNS; col++ )
    {
        cout << "\t Col: " << col
             << ": " << arr[row][col]
             << endl;
    }
}
- Example: Declaring a 2D and a 3D array
string spreadsheet[32][32]; // rows and columns
int vertices[4][4][4];    // x, y, z
Let's say we wanted to turn a day planner into a program. Perhaps we originally stored the day plan like this:
Day Time Task Monday 8:00 Work meeting with Bob Monday 13:00 Project review Tuesday 10:00 Customer meeting Tuesday 12:00 Crying in car Wednesday 14:00 Sprint Retrospective We can convert this into a 2D array of strings (the "task"), with one dimension being for "day of the week" and the other dimension being for "hour of the day"…
- Example: Declaring a 2D array of strings
int DAYS_OF_WEEK = 7;
int HOURS_IN_DAY = 24;
string todo[ DAYS_OF_WEEK ][ HOURS_IN_DAY ];
We could ask the user what day they want to set a task for, and if they type "Sunday" that could translate to 0, and "Saturday" could translate to 6 (or however you want to organize your week)…
Sunday Monday Tuesday Wednesday Thursday Friday Saturday 0 1 2 3 4 5 6 We could ask them next for what hour the task is at, and that can map to the second index: "0" for midnight, "8" for 8 am, "13" for 1 pm, and so on to 23.
With this information, we can get the user's todo task and store it at the appropriate indices:
- Example: Asking the user to enter a day and hour and using those as indices
int day, hour;

cout << "Enter the day:" << endl;
cout << "0. Sunday    \n"
     << "1. Monday    \n"
     << "2. Tuesday   \n"
     << "3. Wednesday \n"
     << "4. Thursday  \n"
     << "5. Friday    \n"
     << "6. Saturday  \n";

cout << "Day: ";
cin >> day;

cout << "Enter the hour (0 to 23): ";
cin >> hour;

cout << "Enter your task: ";
cin >> todo[ day ][ hour ];
With the user's week planned out, you could then display it back to the user by using a nested for loop: One loop for the day, one loop for the hour.
- Example: Nested for loop to display all elements of the 2D array
cout << "YOUR SCHEDULE" << endl;

for ( int day = 0; day < DAYS_OF_WEEK; day++ )
{
  for ( int hour = 0; hour < HOURS_IN_DAY; hour++ )
  {
    cout << day << ", "
         << hour << ": "
         << todo[ day ][ hour ] << endl;
  }
}
Though you'd probably want to do some extra formatting; such as determining that if the day is 0, then write "Sunday" instead of the number "0".
Review 11. Even with a 2-dimensional array each element is still the same data type. You declare a 2d array similarly to a 1d array, but with an extra size:
const int ROWS = 10;
const int COLUMNS = 3;
string spreadsheet[ROWS][COLUMNS];
Given 10 rows and 3 columns, how many elements would this be?
Review 12. To display the contents of a 2D array, it can be useful to have two for loops, one nested in the other. The outer for loop will only increment once the inner one finishes its cycle.
Given the following 2D array declaration:
const int ROWS = 3;
const int COLUMNS = 4;
string pixelColors[ROWS][COLUMNS];
How would you create for loops that will display the element data like this?
Row: 0
   Col: 0: #00ffff
   Col: 1: #ff00ff
   Col: 2: #000000
   Col: 3: #00ff00
Row: 1
   Col: 0: #000000
   Col: 1: #00ffff
   Col: 2: #ff0000
   Col: 3: #0000ff
Row: 2
   Col: 0: #000000
   Col: 1: #ffff00
   Col: 2: #ff0000
   Col: 3: #00ff00
- Example: Displaying all the elements of a 2D array
- Common errors
What happens if we have an array declared like this:
float prices[5];
But we try to access an index that it outside its range, like…
cout << prices[-1];
cout << prices[100];
If this occurs, this is an out of bounds error, and will cause the program to crash! So now we have a very reliable way to crash our programs now. :)
Review 13. Given the array declaration:
int myArr[10];
Are any of the following out of bounds?
myArr[0]is ○ OK / ○ Out-of-boundsmyArr[5]is ○ OK / ○ Out-of-boundsmyArr[10]is ○ OK / ○ Out-of-boundsmyArr[11]is ○ OK / ○ Out-of-bounds
5.5.3. 📚 Intro: STL Array and STL Vector
Overview:
- Terms to know: array, vector
- Concepts:
- To use std::array library you need to have
#include <array> - To use std::vector library you need to have
#include <vector> - std::array is still a fixed length.
- std::vectors will resize as needed.
- To use std::array library you need to have
- New code:
- Declare an std::array:
array<TYPE, SIZE> ARRNAME; - Declare an std::vector:
vector<TYPE> VECNAME; - Get the size (of either):
ARRNAME.size() - Add a new item to a vector:
VECNAME.push_back( VALUE );
- Declare an std::array:
- std::array
C++ provides various handy functionality in it's standard library (abbreviated, unfortunately, as "std"). This includes a smarter array, as well as another structure we'll look at in a moment. The documentation for the std::array (aka array object) is available here:
https://www.cplusplus.com/reference/array/array/
Just like our standard array, we still need to know its size at compile time, but it keeps track of its own size so we don't need to declare a named constant like const int
ARRAY_SIZE = 10;If we put
#include <array>at the top of our file, we can use anarrayobject instead of a traditional array to store data. They are basically interchangable, ecxept thearrayobject gives us access to the.size()function, making our job slightly easier. However, thearraystill can't be resized.Creating an STL array:
// Provide the <DATATYPE, SIZE>.
// Just like the traditional array, size must be constant here.
array<string, 5> products;
Setting elements of the array:
products[0] = "Pencil";
products[1] = "Eraser";
products[2] = "Pencil case";
products[3] = "Pencil sharpener";
products[4] = "Ruler";
Iterating over the array:
for ( unsigned int i = 0; i < products.size(); i++ )
{
    cout << i << ". "; // Display index
    cout << products[i] << endl; // Display element at that index
}
Review 1. The std::array documentation describes the array as…
- ○ associative containers that store elements formed by a combination of a key value and a mapped value.
- ○ fixed-size sequence containers.
- ○ sequence containers representing arrays that can change in size.
- ○ sequence containers that allow constant time insert and erase operations anywhere within the sequence, and iteration in both directions.
#+BEGINREVIEW Review 2. On the std::array documentation page, click on the link to the size function (under "Member functions", then under "Capacity").
What does the
sizefunction do?- ○ Returns a bool value indicating whether the array container is empty, i.e. whether its size is 0.
- ○ Returns the number of elements in the array container.
- ○ Returns a reference to the element at position n in the array container.
Review 3. On the std::array documentation page, click on the link to the operator[] function (under "Member functions", then under "Element access").
What does this function do?
- ○ Returns a bool value indicating whether the array container is empty, i.e. whether its size is 0.
- ○ Returns the number of elements in the array container.
- ○ Returns a reference to the element at position n in the array container.
Review 4. On the std::array documentation page, look through the function sub-pages and find some example code. Use that to figure out the following:
How do you declare a std::array of strings of size 5 named students? #+ENDREVIEW
Review 5. Once you've declared a std::array, you can access its elements the same way as a traditional array. The main benefit is using the .size() function.
How could we write a for loop that iterates over all elements of an std::array displaying each item?
(Note that the examples use "unsigned int" because technically size cannot be negative, so unsigned restricts it to 0 and positive numbers.) #+ENDREVIEW
- std::vector
The C++ Standard Template Library contains a special structure called a vector. A vector is a class (something we'll learn about later) and it is implemented on top of a dynamic array (which we will learn about later with pointers). Basically, it's a resizable array and it has functionality to make managing data a bit more manageable. Its documentation is here:
https://cplusplus.com/reference/vector/vector/
Generally, in Computer Science curriculum, we teach you how to build data structures (structures that store data) like vectors, lists, and other items because it's important to know how they work (thus why we're covering arrays), but for your own projects and in the real world, you would probably use a vector over an array.
Declaring a vector:
Vectors are a type of templated object, meaning it can store any data type - you just have to specify what kind of type the vector stores. The format of a vector declaration looks like this:
// Declaring vectors
vector<string> students;
vector<float>  prices;
Adding data:
You can add data to a vector by using its
push_backfunction, passing the data to add as the argument:vector<string> students; students.push_back( "Rai" );
Getting the size of the vector:
The
sizefunction will return the amount of elements currently stored in the vector.cout << "There are " << students.size() << " students" << endl;
Clearing the vector:
You can erase all the data in a vector with the
clearfunction:students.clear();Accessing elements by index:
Accessing an element at some index looks just like it does with an array:
cout << "Student: " << students[0] << endl;
Iterating over a vector:
You can use a for loop to iterate over all the elements of a vector, similar to an array:
cout << "Students:" << endl;

for ( int i = 0; i < students.size(); i++ )
{
    cout << i << "\t" << students[i] << endl;
}
You can also use C++11 style range-based for loop if you don't need the index. It allows you to iterate over all the elements of
students, using an alias ofstudentfor each element.for ( auto & student : students ) { cout << student << endl; }
Review 6. The std::vector documentation describes the vector as…
- ○ associative containers that store elements formed by a combination of a key value and a mapped value.
- ○ fixed-size sequence containers.
- ○ sequence containers representing arrays that can change in size.
- ○ sequence containers that allow constant time insert and erase operations anywhere within the sequence, and iteration in both directions.
Review 7. According to the std::vector documentation, a vector is an implementation of what?
- ○ An associative array
- ○ A dynamic array
- ○ A fixed-length array
- ○ A linked list
Review 8. According to the std::vector documentation, how is a vector of strings declared, with the name of students?
- ○
string students[vector]; - ○
string<vector> students; - ○
vector<string> students; - ○
vector<string, 10> students;
Review 9. According to the std::vector documentation, how is a new element added to a vector, assuming the vector hasn't been pre-set to a size? Let's use students as the example vector again.
- ○
students[0] = "Alexandria"; - ○
students.pop_back( "Seongmin" ); - ○
students.push_back( "Paola" );
Review 10. Since the
std::arrayandstd::vectorboth have anoperator[]function, this means…○ For both structures we can access elements like this:
cout << structureName[i];○ For both structures we can access elements like this:
cout << structureName.operator[](i);○ For both structures we can access elements like this:
cout << structureName.i;
Review 11. We can write a for loop to iterate over all the elements in a vector just like with the array. How do you write a for loop to iterate over all elements of a vector and display each element's index and value?
5.5.4. 📚 Intro: C-strings
WIP
5.6. Week 6: Memory, pointers, and dynamic arrays
5.6.1. 📚 Intro: Pointers and memory
Video - Memory basics:
Video - Pointers:
Overview:
- Terms to know: Address, pointer, dereference, address-of-operator, dereference-operator, nullptr.
- Concepts:
- Set pointers to
nullptrwhen not in use for safety.
- Set pointers to
- New code:
- Get the address of a variable:
&VARIABLE - Declare a pointer variable:
TYPE* PTRVAR; - Declare and initialize a pointer variable:
TYPE* PTRVAR = nullptr; - Assign an address to a pointer variable:
PTRVAR = &VARIABLE; - Display the address that the pointer is pointing to:
cout << PTRVAR; - Display the value of the item at that address by dereferencing:
cout << *PTRVAR; - Overwriting the value stored at the address by dereferencing:
cin >> *PTRVAR;*PTRVAR = VALUE;
- Get the address of a variable:
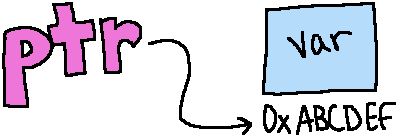
- Bits and Bytes
When we declare a variable, what we're actually doing is telling the computer to set aside some memory (in RAM) to hold some information. Depending on what data type we declare, a different amount of memory will need to be reserved for that variable.
Data type Size boolean 1 byte character 1 byte integer 4 bytes float 4 bytes double 8 bytes A bit is the smallest unit, storing just 0 or 1.
A byte is a set of 8 bits. With a byte, we can store numbers from 0 to 255, for an unsigned number (only 0 and positive numbers, no negatives).
The minimum possible value for 1 byte is 0.
(Decimal value = \(128 \cdot 0 + 64 \cdot 0 + 32 \cdot 0 + 8 \cdot 0 + 4 \cdot 0 + 2 \cdot 0 + 1 \cdot 0\))
place 128 64 32 16 8 4 2 1 value 0 0 0 0 0 0 0 0 The maximum possible value for 1 byte is 255.
(Decimal value = \(128 \cdot 1 + 64 \cdot 1 + 32 \cdot 1 + 8 \cdot 1 + 4 \cdot 1 + 2 \cdot 1 + 1 \cdot 1\))
place 128 64 32 16 8 4 2 1 value 1 1 1 1 1 1 1 1 Some data types, like a
booland achar, use only 1 byte. But others, likeintandfloat, use more. Since an integer uses 4 bytes, that means it has \(8 \cdot 4\) = 32 bits available to store data. \(2^{32} = 4,294,967,296\), so floats and integers can store this many different values. (Note that this doesn't mean that an integer goes from 0 to 4,294,967,296, because we have to account for negative values.)- Memory addresses
Whenever a variable is declared, we need space to store what its value is. We have already looked at how many bytes a data type takes up, but where is the variable's data stored? – In working memory. You can think of this as the RAM, though the Operating System interacts with the RAM and gives us a "virtual memory space" to work with. But, to keep it simple, we will think of this as the RAM.
Each block of space in memory has a memory address, one after another…
Bit address 0 1 2 3 4 5 6 7 Though to the computer, it represents these addresses in binary (base 2) or hexadecimal (base 16):
Address 0x00 0x01 0x02 0x03 0x04 0x05 0x06 0x07 Hexadecimal goes from 0 to 16, but values from 10 and up are represented with letters. This is so each "number" in the value only takes 1 character (10 is two characters: 1 and 0). So, a quick reference for hexadecimal is like this:
Base 16 (Hex) A B C D E F Base 10 10 11 12 13 14 15 Base 2 (Binary) 1010 1011 1100 1101 1110 1111 Review 1. Memory addresses are usually written as…
- ○ Decimal (base-10)
- ○ Hexadecimal (base-16)
- ○ Octal (base-8)
- Example: Variable in memory
Let's say we're investigating some blocks of memory.
If we declare a
char, which gets 1 byte, it will take up any available memory where 8 bits are available side-by-side. Some blocks in memory might already be taken, so whatever is available will be used:Address Variables (BEFORE) Address Variables (AFTER) 0x0 (used) 0x0 (used) 0x1 (used) 0x1 (used) 0x2 0x2 char1 0x3 0x3 char1 0x4 0x4 char1 0x5 0x5 char1 0x6 0x6 char1 0x7 0x7 char1 0x8 0x8 char1 0x9 0x9 char1 0xA(10) (used) 0xA(10) (used) 0xB(11) (used) 0xB(11) (used) 0xC(12) 0xC(12) 0xD(13) 0xD(13) 0xE(14) (used) 0xE(14) (used) 0xF(15) (used) 0xF(15) (used) In this case, declaring our variable,
char char1 = 'A';
its data will be placed with its first bit at address
0x2.We can use the address-of operator
&to see what any variable's address in memory is.cout << "Value: " << char1 << "\t"; cout << "Address: " << &char1 << endl;
Getting the address-of a variable will return the address of its first bit, so the output here would be:
Program output:
Value: A Address: 0x2
(Again, keep in mind that the representation of addresses here is simplified.)
Review 2. How do you access the address of a variable?
- ○
&variable_name - ○
*variable_name - ○
!variable_name
- ○
- Example: Variable value in memory
We can see where the variable is stored at in memory, but let's look at how it's value will be stored as well.
Given the declaration:
char char1 = 'A';
The value of
'A'is stored in 1 byte. Technically, our computer stores the letter "uppercase A" as the number code65. This can be converted into binary: (65)10 =0100 0001. This is the data that would be stored in that memory address.Address Variables Value 0x0 (used) 0x1 (used) 0x2 char1 0 0x3 char1 1 0x4 char1 0 0x5 char1 0 0x6 char1 0 0x7 char1 0 0x8 char1 0 0x9 char1 1 0xA(10) (used) 0xB(11) (used) 0xC(12) 0xD(13) 0xE(14) (used) 0xF(15) (used) This is just a basic representation, again. One thing you'll learn more about in future Computer Science courses is endian-ness, such as whether a number has its most-significant bit on the left side or the right side. We're not worrying about that here. :)
- Memory addresses
- Pointer variables
Pointer variables are another type of variable, but instead of storing a value like
"ABC",'X',10.35, or4, it stores a memory address instead.- Pointer declaration
When we declare a normal variable, we have to specify its data type. With a pointer variable, we specify the data type of the data it's pointing to, plus the
*character (after the data type) to show that this is a pointer variable.Declaration forms
DATATYPE* PTRNAME;DATATYPE * PTRNAME;DATATYPE *PTRNAME;DATATYPE* PTRNAME = nullptr;DATATYPE* PTRNAME{nullptr};
The pointer variable declaration takes the same form as a normal variable's declaration except we have to put the asterisk
*after the data type. The asterisk can be attached to the data type , the name, or free-standing, it doesn't really matter, but I prefer keeping it with the data type. - Pointer assignment
Once we have a pointer, we can point it to the address of any variable with a matching data type. To do this, we have to use the address-of operator to access the variable's address - this is what gets stored as the pointer's value.
Assignment forms
Assigning an address during declaration:
int* ptr = &somevariable;Assigning an address after declaration:
ptr = &somevariable;
After assigning an address to a pointer, if we
coutthe pointer it will display the memory address of the pointed-to variable - just like if we had usedcoutto display the address-of that variable.- Example: A variable and a pointer
// Declare normal variable int someVariable = 100; // Declare pointer variable, // point to someVariable's address int* ptr = &someVariable; // Both show someVariable's address cout << &someVariable; cout << ptr << endl;
Review 3. How do you declare a pointer variable?
Review 4. How do you assign the address of a variable to a pointer?
- Dereferencing pointers to get values
Once the pointer is pointing to the address of a variable, we can access that pointed-to variable's value by dereferencing our pointer. This gives us the ability to read the value stored at that memory address, or overwrite the value stored at that memory address. We dereference the pointer by prefixing the pointer's name with a
*- again, another symbol being reused but in a different context.Dereference forms
Displaying pointed-to value:
cout << *ptr;Overwriting pointed-to value:
*ptr = 200;Overwriting pointed-to value with user input:
cin >> *ptr;
- Example: A variable and a pointer
// Declare normal variable int someVariable = 100; // Declare pointer variable, // point to someVariable's address int* ptr = &someVariable; // Both show someVariable's address cout << &someVariable; cout << ptr << endl; // Both show someVariable's value cout << someVariable << endl; cout << *ptr << endl; // Update the variable's value via the poitner *ptr = 50;
Review 5. How do you dereference a pointer to display the value of the address that it is pointing to?
Review 6. How do you dereference a pointer to store a new value in the pointed-to memory block?
- Pointer declaration
- Safety with pointers!
Remember how variables in C++ store garbage in them initially? The same is true with pointers - it will store a garbage memory address. This can cause problems if we try to work with a pointer while it's storing garbage.
To play it safe, any pointer that is not currently in use should be initialized to
nullptr(orNULLif you're going back to plain old C language :).Review 7. When a pointer is not currently in use, it should be set to…
- ○
dont_use - ○
nullptr - ○
INVALID - ○
cant_touch_this
- ○
5.6.2. 📚 Intro: Dynamic arrays
Overview
- 📽️ Overview video: Dynamic arrays
- Concepts:
- Why are traditional arrays fixed-length and dynamic arrays can be "resized"?
- What are the steps of allocating and deallocating memory via a pointer?
- What are the steps for "resizing" the dynamic array?
- Does a dynamic array's size need to be known at compile time?
- New code:
- Declaring a dynamic array:
TYPE* ARRNAME = new TYPE[SIZE]; - Freeing memory from a dynamic array:
delete [] ARRNAME;
- Declaring a dynamic array:
- Program memory
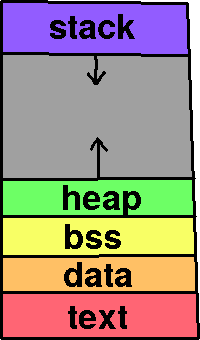
Programs have a memory space where different types of data is stored.
- Text is program instructions.
- Data is where global and static variables are stored.
- Heap space is where dynamically allocated variables/arrays are stored.
- Stack space is where local variables, parameter variables, are stored.
There is a limit to stack space. When you have something like a logic error in a recursive function and it keeps allocating space for variables eventually you'll get a Stack Overflow, running out of stack space.
Dynamically allocated variables and arrays are stored on the Heap.
Review 1. Fill in the blanks:
- a. __ space is limited, but memory is allocated and freed automatically.
- b. __ space is where we manually allocate and free our dynamic memory.
- Dynamic array
We can use Dynamic Arrays to allocate space for an array at run-time, without having to know or hard-code the array size in our code. To do this, we need to allocate memory on the heap via a pointer.
In C++ we use the new and delete keywords to allocate and deallocate memory. Because we have to manually manage this memory, it's important to remember to delete anything that has been allocated via new.
- Creating a dynamic array
We don't have to know the size of the array at compile-time, so we can do things
int size; cout << "Enter size: "; cin >> size; string* products = new string[size];
like ask the user to enter a size, or otherwise base its size off a variable.
- Setting elements of the array
We can access elements of the dynamic array with the subscript operator, as before. However, we won't know the size of the array unless we use the
sizevariable, so it'd be better to use a for loop to assign values instead of this example:products[0] = "Pencil"; products[1] = "Eraser"; products[2] = "Pencil case"; products[3] = "Pencil sharpener"; products[4] = "Ruler";
- Iterating over the array
Accessing elements of the array and iterating over the array is done the same way as with a traditional array.
for ( unsigned int i = 0; i < size; i++ ) { cout << i << ". "; // Display index cout << products[i] << endl; // Display element at that index }
- Freeing the memory when done
Before your pointer loses scope we need to make sure to free the space that we allocated:
delete [] products;
- "Resizing" the array
When memory is allocated for an array we must know the entire size at once because all of the array's elements are contiguous in memory. Because of this, we don't technically "resize" a dynamic array, instead we allocate more space elseware and copy the data over to the new array. Here are the steps:
Allocate space for a new, bigger array
string* newArray = new string[ size + 10 ];
Copy the data from the old array to the new array
for ( unsigned int i = 0; i < size; i++ ) { newArray[i] = products[i]; }
Free the space at the old address
delete [] products;
Update the main array pointer to the new address
products = newArray; // Point to same address
Update your size variable
size = size + 10;
Review 2. Given this code:
int newSize = size + 10; float * prices = new float[ newSize ]; // ... [code] ... delete [] prices;
What will the size of the dynamic array be if the original size was 5?
Review 3. If you create a dynamic array with a pointer like this:
string* myPtr = new string[50];
Before
myPtrgoes out of scope you must always make sure to use…○
free [] myPtr;/ ○delete [] myPtr;/free myPtr;/ ○delete myPtr;Review 4. Resizing a dynamic array isn't really resizing, it's…
- ○ Allocating more space at a new location, copying the data over, freeing the old location, and pointing the array-pointer to the new locaion.
- ○ Moving all the data into a traditional C-style array.
- ○ Using a
vector<>instead. - ○ Freeing the array-pointer, allocating more space at a new location, and asking the user to re-enter all the values.
- Creating a dynamic array
- Arrays in the Real World
Knowing how a Dynamic Array works is an important part of understanding how software works and by knowing more about memory management you'll gain insight into how to write efficient code. This will return moreso in a Data Structures course.
At work and for your own projects just use
std::vectoror whatever built-in array/list type available for your language of choice. It's been written, it takes care of resizing and memory management, and you can implement what you need with something that's already robust and proven.
5.7. Week 7: Functions, recursion, and testing
5.7.1. 📚 Intro: Functions
Video - Function basics:
https://youtube.com/shorts/D52AjpFLilM
Video - Scope, pass-by-value, pass-by-reference, etc.:
https://youtube.com/shorts/MLzWpeZXMm4
Video - Array parameters, const reference, function overloading:
Overview:
- Terms to know: Function declaration, function definition, function call, function header/signature, variable scope, parameters, arguments, pass-by-value, pass-by-reference
- Concepts:
- What does pass-by-value mean?
- What does pass-by-reference mean?
- How are array parameters passed?
- What is function overloading?
- How do you use default parameters?
- New code:
- Function header:
RETURNTYPE FUNCNAME( PARAM1TYPE PARAM1NAME, ... ) - Function declaration is the header with a semicolon at the end.
- Function definition is the function header plus a body within
curly braces
{ } - Function call:
TYPE VAR = FUNCNAME( VALUE1, VALUE2, ...);
- Function header:
- Common errors:
- Don't specify data types for arguments in a function call.
- Function calls must have () even if there are no arguments.
- Don't forget
As programs become more sophisticated and offer more features, the size of the
program increases. At some point, it becomes too complicated to keep your
entire program just within main(). (You could certainly do it, but
maintaining it would be a nightmare!)
One of the tools we use to build modular, easier-to-read code is functions. By using functions, we can delegate tasks out to other portions of the program, passing inputs as data to the function, and receiving some kind of output as a result.
As a basic example, let's say we need to calculate square footage of a room in
multiple places in a program. By making a
float GetArea( float width, float length ) function. Then, we only have to
implement the formula once and can use the function in every part of the
program. Then, we wouldn't be copy-and-pasting the same formula over and over
again in the code - which also means less likelihood of errors, and easier to
update later as needed.
- What is a function?
Functions are a handy way for us to split out some code from our main() function, giving that code a name (the function name) to identify it. When we do this, we make very modular programs where it is easier to maintain because everything is broken up into distinct, discrete steps. In math, a function looks like this:
f(x) = 2x+1
Where f is the function name, x is the input, and whatever is computed on the right-hand-side of the equal sign is the return output.
It's the same in programming: Our functions can have inputs (parameters), process some data, and return some outputs. And, because they're defined elseware in the program, we can call them as many times as we want.
- Program flow and functions
Whenever a function is called, the program flow is redirected into that function, running from top-to-bottom as normal (with branching and loops changing that flow). Once the function has completed, it can return some data, which is received by the call location.
From a design standpoint, this means we can break out different parts of programs into their own sections. Each function has a name, which should be used to label what the purpose of its code is.
- Program flow usually goes top-to-bottom, but the flow can be
temporarily moved elseware via a…
- ○ Function call
- ○ Pointer dereference
- ○ Variable input
- Program flow and functions
- Uses of functions
- Functions for formulas
In algebra, you've seen functions like this:
\[ f(x) = 2x + 3 \]
If you were like me in algebra, you might have thought to yourself, "That's the same as \(y = 2x + 3\), why did we replace \(y\) with \(f(x)\)?" The reason is that we want to write a function in terms of its input, \(x\), and its output \(f(x)\). The equation \(2x + 3\) is the function body, which specifies how we get some output given some input.
We can use functions in programming like with math as well - defining formulas that we might need a lot - but there's more to functions than just making computations.
Let's say we want to make our "GetArea" function in math. We would need two inputs: Width and Length, and the output would end up being the area, so maybe we would name the function \(A\). It might look like this:
\[ A( w, l ) = w \cdot l \]
In C++, it would look like this:
Example:
float Area( float width, float length ) { return width * length; }
(Luckily we don't have to restrict ourselves to single-letter variable and function names in C++ :)
Review 2. Let's say we want to write a function that calculates the area of a rectangle based on the width and length of it. What would the function's input(s) and output(s) be?
- Functions to validate
Functions can also be handy in validating data and user input, putting the validation in one place instead of having to re-implement the same checks over and over. Let's say we want to keep some variable percentage in our program between 0% and 100% - no negative values, nothing over 100%. We could implement a function that takes the percentage as an input, and either returns the same percentage, or 0%, or 100% as output…
Function definition:
int BoundPercent( int originalPercent ) { if ( originalPercent < 0 ) { return 0; } else if ( originalPercent > 100 ) { return 100; } else { return originalPercent; } }
Then, anywhere in the program, we could use this function to make sure our percentages are in the right range…
Within main()…
hungerPercent = BoundPercent( hungerPercent ); healthPercent = BoundPercent( healthPercent ); happinessPercent = BoundPercent( happinessPercent );

- Functions to get input
Getting user input is a common part of writing software, and we will usually need to validate what the user is entering prior to doing any operations on it. Let's say your program is full of numbered menus and you want to validate the user's menu choices easily. You can use a function with a while loop in it:
int GetUserInput( int min, int max ) { int choice; cout << "Choice: "; cin >> choice; while ( choice < min || choice > max ) { cout << "Invalid choice, try again: "; cin >> choice; } return choice; }
You write this function once and then you can reuse it in your entire program for all menus…
cout << "1. Deposit money" << endl << "2. Withdraw money" << endl << "3. View balance" << endl; choice = GetUserInput( 1, 3 ); // 1, 2, or 3 if ( choice == 1 ) { cout << "1. Checking account" << endl << "2. Savings account" << endl; choice = GetUserInput( 1, 2 ); // 1 or 2 }
Review 3. Let's say we want to write a function that handles a cin statement to get the user's input. We want to make sure the user's selection is between two numbers, min and max. Once we've validated the user's choice, we return that valid choice back to the main program. What would be the input(s) and what would be the output(s)?
- Functions to output
Functions aren't required to return data. Sometimes, you just want a function that is responsible for formatting output or displaying a menu. In this case, a function's return type can be
void.void DisplayStudentInfo( string name, float gpa ) { cout << "Name: " << name << "GPA: " << gpa << endl; }
You also aren't required to pass input to functions. In this case, the parameter list between ( ) remains empty, but the () is always required for functions:
void DisplayMainMenu() { cout << "1. Deposit" << endl; cout << "2. Withdraw" << endl; cout << "3. View Balance" << endl; cout << "4. Log Out" << endl; }
- Other uses
These are just some examples of why you might use functions in your programs. Anything you write in
main()can go inside of a different function as well - it's just another tool for designing clean, maintanable, and readable code.
- Functions for formulas
- Anatomy of a function

- The function signature
A function signature in C++ is required as part of both the function declaration and the definition. The signature is how you tell functions apart - what makes them unique… their signature.
The function signature takes this form:
RETURN_TYPE FUNCTION_NAME( PARAM1TYPE PARAM1NAME, PARAM2TYPE PARAM2NAME, ... )
So for instance, a GetArea function signature could look like this:
float GetArea( float width, float length )
Review 4. What is included in a function signature? Specify the proper order.
Review 5. Build the function signature given the following requirements:
- Function is named "GetRectArea".
- Function returns a float.
- Function takes in a float for the width and a float for the length.
- Creating a function
When we want to create a function we need to write a function declaration and a function definition.
The function declaration is the function signature and a ; at the end. Declarations should go in header (.h) files.
int Func( int a, int b );
The definition includes the function signature but also a code block - denoted by opening and closing curly braces { }. Within this code block is where we define what the function does.
int Func( int a, int b ) { return a * b + 1; }- Declaration in the header (.h) file
When we create a header file, it should end with .h, though sometimes ends with .hpp (depending on the programmer's style.)
The header must contain file guards:
#ifndef _MY_FILE_H #define _MY_FILE_H // put code in here #endif
You can use any label to replace
"_MY_FILE_H", but it should be unique for each file. The file guard prevents the compiler from reading the same code multiple times, and essentially thinking that you've written a bunch of duplicate code.Within the header file we put our function declarations:
#ifndef _MY_FILE_H #define _MY_FILE_H #include <string> using namespace std; string GetState( int zipcode ); char GetCurrencyType( string country ); float Quadratic1( float a, float b, float c ); float Quadratic2( float a, float b, float c ); #endif
If any of our function signatures have special data types like string we need to make sure to also include the appropriate library in the file as well.
- Definition in the source (.cpp) file
Function definitions should go in source files (.cpp files). Usually, there should be one source file for main(), and a separate source file for function definitions, based on some grouping.
If you were splitting out reusable functions for doing math, you could create something like "Math.h" and "Math.cpp" to store those functions' declarations and definitions.
The .cpp files don't need file guards, but you do need to include the corresponding header file that contains the functions' declarations. In Math.cpp you'd need:
#include "Math.h"
As a program grows, you might have many different sets of files, so it's good to group things by similar functionality. Within the .cpp file, you define the functions.
#include "Functions.h" #include <string> using namespace std; string GetState( int zipcode ) { if ( zipcode == 64063 ) { return "Lee's Summit"; } else if ( zipcode == 64138 ) { return "Raytown"; } else { return "UNKNOWN"; } } // ...etc...
Review 6. Identify which code snippet is the function declaration and which is the function definition.
a. ○ Declaration / ○ Definition
int Sum( int a, int b ) { return a + b; }
b. ○ Declaration / ○ Definition
int Sum( int a, int b );
Review 7. File guards are needed for _ file(s).
- Declaration in the header (.h) file
- #include
When we have our functions declared in a file separate from where we have our
main(), in order for our main file to "see" the new function, we have to include the file. Any other files in our program will also need to include the header if it is using functions within that file.#include "MYFILE.h"
Note: DO NOT use include for cpp files! This will cause build errors!
- Calling functions
The third piece is the function call, when we are actually putting it into use in our code. The function call occurs from outside of the function, such as within main() (or, one function can call another function!)
The function call is of this form:
FunctionName( arg1, arg2, arg3 );
Or, if the function returns data, we need to make sure to put the result somewhere. The data type of the variable you use to store the result should match the function's return type:
float result = Sum( 2, 4 );
We can pass hard-coded literals in as the input, or we can pass in existing variables as the inputs.
float num1 = 3; float num2 = 5; float result = Sum( num1, num2 ); // Two variables float result2 = Sum( 1, 3 ); // Two int literals float result3 = Sum( num1, 3 ); // A variable and a literal
Review 8. Given the following function declaration:
float PricePlusTax( float price, float tax );
And assuming within
main()we have variablesmyPrice,myTax, andpriceAfterTax, how would we call the PricePlusTax function and store its result? - Arguments vs. parameters
Another key piece of terminology is parameters versus arguments.
When we're declaring or defining a function and we have input variables in the signature, like this:
float Sum( float a, float b );
Those two input variables a and b are known as parameters. When we're creating the function, we define the input parameters.
When we're calling the function and passing in data - whether as a literal or a variable's data, like this:
float result = Sum( 1, 2 ); float result = Sum( myNum1, myNum2 );
The data being passed as input are called arguments.
- Pass-by-value
When we create a parameter in our function and declare it as a normal variable, that parameter is pass-by-value. This means that a copy of the argument is made, and any changes to the parameter within the function will only exist within that function… back out at the caller, the original argument will not have any changes.
void PassByValue( int num ) { cout << "Before assignment: " << num << endl; num = 10; cout << "After assignment: " << num << endl; } int main() { int number = 100; cout << "Before function: " << number << endl; PassByValue( number ); cout << "After function: " << number << endl; return 0; }
Within
main(), thenumbervariable will always be 100. In the function,numwill start off with 100, but then be changed to 10. This change isn't preserved back out inmain(). - Pass-by-reference
We can also pass our arguments by-reference. To do this, in our function signature we mark the parameter's type with an ampersand, this marks it as "pass-by-reference":
void PassByReference( int& num ) { cout << "Before assignment: " << num << endl; num = 10; cout << "After assignment: " << num << endl; }
The function call from
main()will look the same, but now any changes made tonumwithin the function will be applied tonumberback out inmain(). - Passing arrays
When traditional arrays are passed to functions, they are automatically passed as a pointer. Any change made to the array within the function will be reflected back out at the caller level.
void Setup( string names[], int size ) { for ( int i = 0; i < size; i++ ) { cout << "Enter name " << i << ": "; getline( cin, names[i] ); } } int main() { string names[3]; Setup( names, 3 ); }
- Passing pointers
We can also mark a parameter as a pointer-variable. This gives the parameter access to the address of the argument, so we can also change the original argument's value.
void PassPointer( int* ptrNum ) { cout << "Before assignment: " << *ptrNum << endl; *ptrNum = 10; cout << "After assignment: " << *ptrNum << endl; } int main() { int number = 100; cout << "Before function: " << number << endl; PassPointer( &number ); // Pass the address cout << "After function: " << number << endl; return 0; }
- Summary: Ways to pass data to/from functions
The following table illustrates different ways we can define our parameters, and what the goal is. "RT" means "Return Type", "T" is the "Type" of the parameter.
Function Read Return Info 1. RT func( T X )yes no Pass-by-value X2. RT func( const T& X )yes no Const pass-by-reference X3. RT func( T& X )yes yes Pass-by-reference XXis pass-by-value, which is fine for primitive data types like ints, floats, chars, and bools.Xis passed by const-reference becauseXis a mose sophisticated data type like a string or other class-based object. (Longer time to copy if passed by value.)- The function can read from
Xbut also overwrite its value and the change will be reflected back to the argument being passed to the function call.
Review 9. Given these code snippets:
float Sum( float a, float b, float c ) { return a + b + c; } int main() { float myint1, myint2, myint3; cout << "Enter three numbers separated by a space: "; cin >> myint1 >> myint2 >> myint3; float result = Sum( myint1, myint2, myint3 ); cout << "Result: " << result << endl; return 0; }
Identify which variables are arguments and which are parameters.
Review 10. Does the name of the input argument variables need to match the name of the corresponding parameter? Or will a function call work even if the argument variable doesn't have the same name as its corresponding parameter?
- ○ The parameter and argument names must match.
- ○ The parameter and argument names do not need to match.
Review 11. When something is passed-by-value to a function…
- ○ The changes made in the function are also applied to the original argument from the caller; we have direct access to it.
- ○ The changes made in the function are only present in the function; the caller retains the original version of the argument.
- When something is passed-by-reference to a function…
- ○ The changes made in the function are also applied to the original argument from the caller; we have direct access to it.
- ○ The changes made in the function are only present in the function; the caller retains the original version of the argument.
- Pass-by-value
- Scope
Variables have different life times. Where they exist in the program is known as its scope. A variable lives within the code block { } it is declared within, and does not exist outside of it.
For example, this variable
totalCatswill exist all throughout main():int main() { int totalCats = 10; // ... }
And the variable quotient only exists within this if statement:
int main() { float num = 3, denom = 4; if ( denom != 0 ) { float quotient = num / denom; } // ... return 0; }
Variables can be used within code blocks that are inside their own code block and beneath where the variable is declared. Here, a can be used anywhere in main(), including in the if statement. b, however, can only be used within main() anywhere after its declaration. c can only be used inside the if statement it was declared within:
int main() { int a = 1; if ( a < 0 ) { int c = -a; } int b = 2; cout << b << endl; // ... return 0; }
Just like how a variable declared at the top of main() will exist throughout main(), the same is true for functions. If we declare a variable at the top, we can use it throughout the entire function - and, we can use the function's parameters anywhere within the function.
But variables don't exist between functions. Something declared in one function cannot be used in another function. Variable names can, however, be reused in different scopes.
Review 14. Given this code snippet:
float SandPerGuest( float sand, float guest ) { return sand/guest; } int main() { float totalSandwiches = 10; float totalGuests = 5; if ( totalGuests != 0 ) { float sandwichesPerGuest = SandPerGuest( totalSandwiches, totalGuests ); cout << "Sandwiches per guest: " << sandwichesPerGuest << endl; } return 0; }
Where can the
totalSandwichesvariable be used?Where can the
sandwichesPerGuestvariable be used?Where can the
sandvariable be used?Review 15. How are Sum's a and b variables related to Diff's a and b variables?
float Sum( float a, float b ) { return a + b; } float Diff( float a, float b ) { return a - b; }
- ○ Any changes to a and b in one function will be reflected in the other function.
- ○ Sum can affect Diff's variables but not vice versa.
- ○ They are not related at all; they are completely distinct variables that happen to have the same name.
- The function signature
- Functions and structs
Structs can also be passed to functions and returned from functions. Let's say we have a product struct:
struct Product { string name; float price; int inStock; };
And we want some helper functions. Here are some example declarations:
void Load1( Product& prod, string filename ); Product Load2( string filename ); void Display( Product prod );
The first Load function takes a Product item as a pass-by-reference parameter, loads data from a text file, and updates that product parameter:
void Load1( Product& prod, string filename ) { ifstream input( filename ); getline( input, prod.name ); input >> prod.price; input >> prod.inStock; }
In main(), we create a Product and then pass it in to that function:
Product product1; Load1( product1, "product1.txt" );
We pass this struct as "pass-by-reference" (denoted by the ampersand next to the parameter data type:
Product&) so that any changes we make to the object within the function will also be preserved outside of the function. If we didn't do this, the function would only have a copy of the object and not be making changes to the original item.The second load function doesn't take in a Product parameter but instead has a Product as its return type. It still loads data from a file but a Product is created within the function itself, and then returned with the return keyword:
Product Load2( string filename ) { Product newProd; ifstream input( filename ); getline( input, newProd.name ); input >> newProd.price; input >> newProd.inStock; return newProd; }
This time when we call the function, we need to call the function and assign its return value to our Product in main():
Product product2; product2 = Load2( "product2.txt" );
The Display function takes in a pass-by-value Product and will display its contents to the screen in a clean way:
void Display( Product prod ) { cout << setw( 10 ) << prod.name << setw( 1 ) << "$" << setw( 9 ) << prod.price << setw( 10 ) << prod.inStock << endl; }
The function can be called with any Product variables we've created:
Display( product1 ); Display( product2 );
With a function that is only meant to display contents to the screen, any reasonable person would assume that the "display" function isn't going to also alter the data. In this case, we can pass the Product item either as pass-by-value (make a copy) with
Product prod, or we could pass it by const-reference, which would be the most efficient:const Product& prod.- The first Load function takes a Product item as a
pass-by-reference parameter, loads data from a text file, and updates that product parameter:
void Load1( Product& prod, string filename ) { ifstream input( filename ); getline( input, prod.name ); input >> prod.price; input >> prod.inStock; }
In main(), we create a Product and then pass it in to that function:
Product product1; Load1( product1, "product1.txt" );
Why is the Product parameter being passed-by-reference?
- ○ If the Product is pass-by-value then anything loaded inside the function won't be reflected back in main().
- ○ It could be pass-by-value, this was just an aesthetic choice.
- The Display function takes in a pass-by-value Product and
will display its contents to the screen in a clean way:
void Display( Product prod ) { cout << setw( 10 ) << prod.name << setw( 1 ) << "$" << setw( 9 ) << prod.price << setw( 10 ) << prod.inStock << endl; }
The function can be called with any Product variables we've created:
Display( product1 ); Display( product2 );
Why is the Product parameter pass-by-value here and not pass-by-reference?
- ○ The Display function isn't supposed to make any changes to the Product, so it can just be pass-by-value where it works with a copy of the data.
- ○ The Display function will not allow pass-by-reference as the keyword Display is meant for only pass-by-value data.
- Functions and arrays
Arrays can be passed into functions as well, and this can be useful for initializing array content, displaying array contents, or other operations.
We can pass both traditional arrays and std::array objects to functions, and the parameter will look like a normal array declaration:
void Function1( int arr[4], int size ); void Function2( array<int, 4> arr ); void Function3( array<int, 4>& arr );
When we call these functions and want to pass the array data, we just use the array name - no other information:
int testArray1[4] = { 1, 1, 1, 1 }; Function1( testArray1, 4 ); array<int, 4> testArray2 = { 2, 2, 2, 2 }; Function2( testArray2 ); array<int, 4> testArray3 = { 3, 3, 3, 3 }; Function3( testArray3 );
FUNCTION TEST 1: In the example code for test 1, we create a traditional array and pass it into Function1:
int testArray1[4] = { 1, 1, 1, 1 }; Function1( testArray1, 4 );
Function1 iterates through all the elements of the array and replaces each item:
void Function1( int arr[4], int size ) { for ( int i = 0; i < size; i++ ) { arr[i] = i; } }
FUNCTION TEST 2: In the example code for test 2, we create a traditional array and pass it into Function2:
array<int, 4> testArray2 = { 2, 2, 2, 2 }; Function2( testArray2 );
Function2 iterates through all the elements of the array and replaces each item:
void Function2( array<int, 4> arr ) { for ( size_t i = 0; i < arr.size(); i++ ) { arr[i] = i; } }
FUNCTION TEST 3: In the example code for test 3, we create a traditional array and pass it into Function3:
array<int, 4> testArray3 = { 3, 3, 3, 3 }; Function3( testArray3 );
Function3 receives the array as pass-by-reference and iterates through all the elements of the array and replaces each item:
void Function3( array<int, 4>& arr ) { for ( size_t i = 0; i < arr.size(); i++ ) { arr[i] = i; } }
- Common function errors
When you're declaring/defining a function you specify data types - the return type and the parameters' data types. When you're calling a function, you do not include data types!
Works sqft = GetArea( room_width, room_length );Doesn't work sqft = GetArea( float room_width, float room_length );Functions must have parentheses
()! If you're missing the parentheses, your program isn't going to call the function!Works DisplayMenu();Doesn't work DisplayMenu;If a function contains a
returnstatement, then you must store the returned data in a variable! If you don't assign the return anywhere, it will be lost!Works sqft = GetArea( room_width, room_length );Doesn't work GetArea( room_width, room_length ); - Advanced function usage
- Default parameters
When declaring a function, you can also set default parameters. These are the default values assigned to the parameters if the user doesn't pass anything in. The default parameters are only specified in a function declaration - NOT the definition!
In this example, it could be a function that displays ingredients for a recipe, and by default the batch is set to 1.0 (one batch).
void OutputIngredients( float eggs, float sugar, float flour, float batch = 1.0 );
The function could be called without passing in a batch:
cout << "Ingredients:" << endl; OutputIngredients( 1, 2.0, 3.5 );
Or they could pass a batch amount explicitly:
cout << "Ingredients:" << endl; OutputIngredients( 1, 2.0, 3.5, 0.5 ); // half batch
You can have multiple default parameters specified in your function declaration - but all variables with default values must go after any variables without default values.
- Function Overloading
In C++, you can also write multiple functions that have the same name, but a different parameter list. This is known as function overloading.
Let's say you want to be able to sum numbers, and you make a version for floats and a version for integers:
int Sum( int a, int b ) { return a + b; } float Sum( float a, float b ) { return a + b; }
You can write as many versions of the function as you like, so long as the function headers are uniquely identifiable to the compiler, which means:
- The functions have a different amount of parameters, or
- The data types of the parameters are different, or
- The parameters are in a different order (when mixing data types).
These will become much more useful once we cover classes and objects.
- Default parameters
5.7.2. 📚 Intro: Testing
- How do we test?
How do you know that your program actually works? Especially as it gets more complex?
Software development skills mean more than just writing code. It also includes knowing how to test your code, to prove that it is working as intended.
For the most basic tests, we investigate a portion of code and ask, "Given some inputs, what are the expected outputs?" and "If I run the program with these inputs, what are the actual outputs?", and finally, "Does my actual output match my expected output?"
Review 1. Given some input and expected output defined, a test would pass if…
- ○ The actual output is different from the expected output.
- ○ The actual output matches the expected output.
- ○ The program doesn't crash
Review 2. Let's say I've written a program that takes in two numbers as inputs and returns the sum as the output.
- a. For our FIRST test case, let's say the inputs are 2 and 3. What would the expected output be?
- b. For our SECOND test case, let's say the inputs are -2 and 5. What would the expected output be?
- Writing tests first?
Notice that you don't actually need to know what is in the function before you write tests for it. Knowing what the program is supposed to do, you can figure out a set of inputs and outputs that it ought to have.
Often, it is very useful to write your test cases prior to actually writing any code. This helps you solidify what exactly he program is supposed to do. Plus, if you write your test cases afterwards, it is a bit like reading your own essay - your brain will skip over errors because it knows what you meant, and doesn't actually read the actual words (or code).
Review 3. Let's say you need to write a program that will update a person's account balance after they deposit some money.
- a. What might be the input(s)? What might be the output?
- ○ INPUT / ○ OUTPUT: The current bank balance
- ○ INPUT / ○ OUTPUT: The bank balance after the deposit
- ○ INPUT / ○ OUTPUT: The amount to deposit
- b. When writing test cases, if we have a current bank balance and
a deposit amount, then…
- ○ We won't know what the new bank balance will be until we write the program.
- ○ We can calculate what the new balance would be by hand.
- ○ It is impossible to know anything; software is a dark and mysterious magic.
- c. Given an initial balance of $100 and a deposit of $120, what would be the expected output after running this program?
- d. Given an initial balance of $30 and a deposit of -$60, what would be the expected output after running the program?
- a. What might be the input(s)? What might be the output?
- Multiple test cases
It isn't good enough to write one single test case. Often, you will want to have enough test cases to check for as many possibilities as possible - though we can't write an infinite amount. So sometimes, it's best to just write tests for reasonable outcomes, including potential errors.
When we eventually write code to do our testing for us, we can have the program keep an "ear out" for an error happening - and, sometimes we want that error to occur. Such as if the user enters a negative deposit amount, we would want the program to notice and send an error code or error message. We could also write our tests to make sure the error occurs, rather than allowing the user to deposit (or withdraw) a "negative" amount of money!
Review 4. Our program needed a function that adds two numbers together and returns the result. Your coworker wrote one test case:
Test 1. Inputs: 2 and 2. Expected output: 4
Then they wrote this code:
#include <iostream> using namespace std; int main( int argumentCount, char* argumentList[] ) { cout << "The result is 4." << endl; return 0; }
- a. Your coworker says "well it passes the test!" - Do you trust
your coworker?
- ○ Yes, absolutely. Clearly they know what they're doing.
- ○ No, their code doesn't have enough test coverage.
- b. How could we actually make sure the function works properly?
- ○ By having at least one more test with different inputs, and a different output.
- ○ By writing another test with the same expected output of 4.
- a. Your coworker says "well it passes the test!" - Do you trust
your coworker?
- Example 1
Let's say your coworker Maryam is writing code for a new feature and you're writing the tests. You both have the requirements, so you can both work at the same time.
Review 5. The program takes in a list of grades (4.0 being 'A', 3.0 being 'B', 2.0 being 'C', 1.0 being 'D', and 0.0 being 'F') and calculates a grade point average. (Averages are calculated as the sum of all the grades divided by the amount of grades.)
- a. For the first test case the inputs are: 4.0, 2.0, 3.5, 3.5. What would be the expected output?
- b. For the second test case the inputs are: 2.4, 2.8, 3.2. What would be the expected output?
- c. For the third test case, the inputs are: 3.0, 3.0, 3.0, 3.0. What would be the expected output?
- Example 2
Now your coworker André is working on another part of the program, and you're writing the tests.
Review 6. The program takes in the price of a given textbook title, and an amount of that textbook to purchase, and returns the total cost of purchasing those textbooks.
- a. For the first test case we want to order 5 copies of a book that costs $75.60. What is the expected output?
- b. For the second test case we want to order 2 copies of a book that costs $49.82. What is the expected output?
- Reminder
Takeaways:
- A single test case consists of inputs and their expected output(s).
- Running the program with the test's inputs will give us the actual output(s).
- A test will pass if the actual output matches the expected output.
- A test will fail if the actual output does not match the expected output.
- Having multiple test cases help you verify that your code works properly.
Review 7. For now, we are writing our test cases on paper (or on the computer) and will be doing manual tests. Later on, we can write functions in our program to run those tests for us automatically.
- ○ Yay!
- ○ Wait, no, I WANT to manually test all the code I write. Clearly that's the most fun.
5.7.3. 📚 Intro: Recursion
Overview:
- Terms to know: Recursive case, terminating case
- Concepts: Iterative approach vs. recursive approach
- Examples of recursion in math
Recursion is a manner of solving a problem by breaking it down into smaller pieces - and those smaller pieces are solved in the same way as the big-picture version.
- Example: Summation
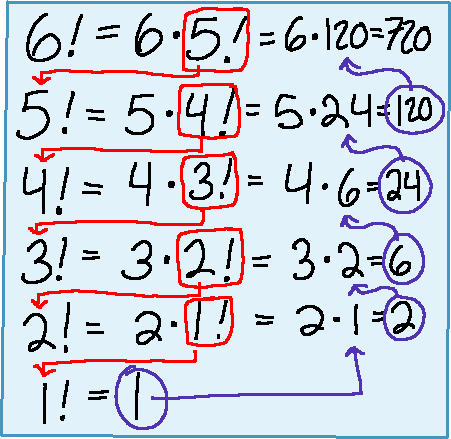
A summation can be broken down into smaller chunks but using the same structure as the original.
Let's say we have \[ \sum_{i=1}^{6} { i } = 1 + 2 + 3 + 4 + 5 + 6 \]
The summation can be redefined recursively:
\[ \sum_{i=1}^{6} { i } = 6 + \sum_{i=1}^{5} { i } \]
The summation from \(i = 1\) to \(6\) is equivalent to whatever the sum is at \(i=6\), plus the sum from \(i = 1\) to \(5\).
We can continue this way until we get to a case that we know (e.g., \(\sum_{i=1}^{1} { i }\)).
- \(\sum_{i=1}^{6} { i } = 6 + \sum_{i=1}^{5} { i }\)
- \(\sum_{i=1}^{5} { i } = 5 + \sum_{i=1}^{4} { i }\)
- \(\sum_{i=1}^{4} { i } = 4 + \sum_{i=1}^{3} { i }\)
- \(\sum_{i=1}^{3} { i } = 3 + \sum_{i=1}^{2} { i }\)
- \(\sum_{i=1}^{2} { i } = 2 + \sum_{i=1}^{1} { i }\)
- We know that \(\sum_{i=1}^{1} { i } = 1\), then we move back up to sub out this value.
Recursive problem A. \[\sum^{6}_{i=1} { i } = 6 + \sum_{i=1}^{5} { i }\] But what is \[\sum_{i=1}^{5} { i }\] ? B. \[\sum_{i=1}^{5} { i } = 5 + \sum_{i=1}^{4} { i }\] But what is \[\sum_{i=1}^{4} { i }\] ? C. \[\sum_{i=1}^{4} { i } = 4 + \sum_{i=1}^{3} { i }\] But what is \[\sum_{i=1}^{3} { i }\] ? D. \[\sum_{i=1}^{3} { i } = 3 + \sum_{i=1}^{2} { i }\] But what is \[\sum_{i=1}^{2} { i }\] ? E. \[\sum_{i=1}^{2} { i } = 2 + \sum_{i=1}^{1} { i }\] But what is \[\sum_{i=1}^{1} { i }\] ? F. \[\sum_{i=1}^{1} { i } = 1\] Now we start substituting this value back for each step…
Finding the solution G. \[\sum_{i=1}^{2} { i } =\] \[2 + \sum_{i=1}^{1} { i } =\] \[2 + 1 = 3\] H. \[\sum_{i=1}^{3} { i } =\] \[3 + \sum_{i=1}^{2} { i } =\] \[3 + 3 = 6\] I. \[\sum_{i=1}^{4} { i } =\] \[4 + \sum_{i=1}^{3} { i } =\] \[4 + 6 = 10\] J. \[\sum_{i=1}^{5} { i } =\] \[5 + \sum_{i=1}^{4} { i } =\] \[5 + 10 = 15\] K. DONE! \[\sum_{i=1}^{6} { i } =\] \[6 + \sum_{i=1}^{5} { i } =\] \[6 + 15 = 21\] - Example: Factorials
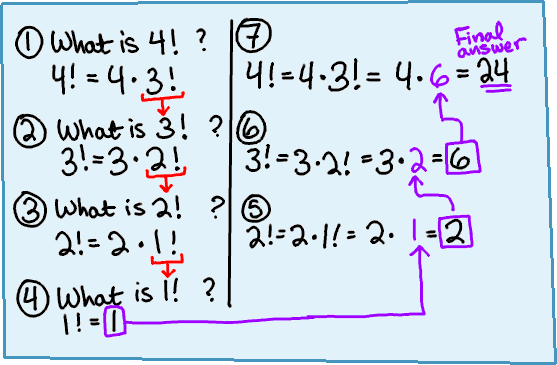
With a factorial of \(n\), written \(n!\) the formula to solve this is:
\[ n! = n \cdot (n-1) \cdot ... \cdot 3 \cdot 2 \cdot 1 \]
So,
- \(2!\) is \(2 \cdot 1\),
- \(3!\) is \(3 \cdot 2 \cdot 1\),
- \(4!\) is \(4 \cdot 3 \cdot 2 \cdot 1\), and so on.
Additionally, we can break down each of these equations: \(3!\) is equivalent to \(3 \cdot 2!\) \(4!\) is equivalent to \(4 \cdot 3!\) … \(n!\) is equivalent to \(n \cdot (n-1)!\)
Thinking of breaking down the problem here in this way is looking at it recursively.
Review 1. What is the result of 6! ?
Review 2. What is the result of n! ?
Review 3. What is the result of (n-1)! ?
- Example: Summation
- Recursion basics
In programming, we usually approach problems iteratively, using a for-loop or a while-loop:
int Sum( int n ) { int result = 0; for ( int i = 1; i <= n; i++ ) { result += i; } return result; }
Which solves this summation:
\[ \sum_{i=1}^n {i} \]
But some types of problems lend themselves better to a recursive solution. To be fair, though, many problems are better solved iteratively. So how do we know which method is better?
When defining a problem recursively in programming, we need two things:
- A terminating case: A case that ends our recursing. Often, this is some known data, something hard-coded. For example with our summation, the terminating case would be that \[ \sum_{i=1}^1 {i} = 1 \] or for a factorial, \(1! = 1\) and \(0! = 1\).
- A recursive case: A recursive case is what happens
otherwise - if we're not to a solution yet (via the terminating case),
we call the same function again, but with updated arguments. For example:
Factorial( 4 ) = 4 * Factorial( 3 )Factorial( 3 ) = 3 * Factorial( 2 )Factorial( 2 ) = 2 * Factorial( 1 )Factorial( 1 ) = 1
We can solve these basic math operations both iteratively and recursively:
Factorial - Iterative solution
int FactorialI( int n ) { int result = 1; for ( int i = 1; i <= n; i++ ) { result *= i; } return result; }
Factorial - Recursive solution
int FactorialR( int n ) { if ( n == 1 || n == 0 ) { return 1; } return n * FactorialR( n-1 ); }
Review 4. What will be returned for
FactorialR( 3 )?return ___ * Factorial( ___ );
Review 5. What will be returned for
FactorialR( 4 )?return ___ * Factorial( ___ );
Review 6. What will be returned for
FactorialR( n )?return ___ * Factorial( ___ );
- Breaking down problems into recursive solutions

One of the most challenging parts of recursion, at least for me, is trying to break away from thinking of something in terms of "looping" and figuring out how to think of it "recursively". It's not as natural-feeling, so don't worry if it's confusing at first.
Let's tackle some basic design problems to practice.
- Example: Summation
Try to convert the Summation function to be recursive. Think about what the terminating case would be and the recursive case. Use the Factorial function for reference.
Summation - Iterative solution
int SumI( int n ) { int result = 0; for ( int i = 1; i <= n; i++ ) { result += i; } return result; }
Review 7. When does the loop terminate?
Summation - Recursive starter
int SumR( int n ) { // Terminating case? // Recursive case? }
Review 8. If we call
Sum( 2 )we are expecting the result to be…If we call
Sum( 3 )we are expecting the result to be…Review 9. If we call
Sum( n )we are expecting the result to be…Summation - Recursive solution
int SumR( int n ) { if ( n == 1 ) { return 1; } // Terminating case return n + SumR( n-1 ); // Recursive case }
- Example: Draw a line
Now let's make a function that will draw a line of symbols, with a parameter being the length. Iteratively, it could look like this:
DrawLine - Iterative solution
void DrawLineI( int amount ) { for ( int i = 0; i < amount; i++ ) { cout << "-"; } }
How would we repeat this behavior recursively? How do we have a "count up" sort of functionality? What would be the terminating case?
We're going to think of it a little differently: The recursive function will only output one "-" before it recurses. Each time it recurses, it draws one more dash…
DrawLine - Recursive work in progress
void DrawLine_Recursive( int amount ) { cout << "-"; // Recursive case DrawLineR( amount ); }
However, we don't have a terminating case… it will continue looping, but it won't go forever like a bad while loop. We will eventually run out of stack space and the program will encounter a stack overflow and end.
So what would the terminating case be? How do we adjust the
amounteach time? Sinceamountis the one parameter we have, let's have the recursion stop once it is 0. Each time we recurse, we can pass inamount-1to the next call…DrawLine - Recursive solution
void DrawLine_Recursive( int amount ) { cout << "-"; // Terminating case if ( amount == 0 ) { return; } // Recursive case DrawLineR( amount - 1 ); }
- Example: Counting up
How can we write a function that takes a
startandendinteger, and outputs each number between them (including the start and end)?Iteratively, it could look like this:
CountUp - Iterative solution
void CountUpI( int start, int end ) { for ( int i = start; i <= end; i++ ) { cout << i << "\t"; } }
CountUp - Recursive starter
Try to fill in this function to build a recursive solution:
void CountUpR( int start, int end ) { }
CountUp - Recursive solution
void CountUpR( int start, int end ) { cout << start << "\t"; // Terminating case if ( start == end ) { return; } // recursive case CountUp_Recursive( start+1, end ); }
- Example: Summation
- A case for recursion
Although there are a lot of problems we could convert from an iterative solution to a recursive solution, there are some types of problems that really are better suited to recursion.
- Example: Searching a File System
On a harddrive, we generally have files and folders. Folders can contain files, but they will also contain subfolders as well. And subfolders can each contain their own subfolders.
When you don't know the exact layout of the filesystem, how would you even begin to iteratively search for a specific file?
Instead, it is good to think of it recursively. For example, say we're searching for a folder where you store your Recursion homework. We will begin searching at the top-most folder of the computer. The algorithm would then run like…
Let's say we have a recursive function,
Find( FOLDERNAME, currentFolder ).For this functionality, terminating cases would be:
- Have we found the item? Return it.
- Are we out of places to search? Return nothing.
And the recursive case would be:
- Has a subfolder? Call Find() on that folder.
So looking at an example set of folders and files like this:
C: |-- games/ | |--DOOM.exe |-- school/ | |-- cs210/ | |-- cs235/ | |-- recursion.txt |-- work/ |-- TPSreports/So steps to locate the "Recursion" folder would look like this:
Find( "recursion.txt", "C:" ) Does "C:" have the recursion.txt file? NO... Does it have subfolders? YES... OK, Recurse. | | Find( "recursion.txt", "C:\games" ) | Does "C:\games" have the recursion.txt file? NO... | Does it have subfolders? YES... OK, Recurse. | | | | Find( "recursion.txt", "C:\games\DOOM.exe" ) | | Does "C:\games\DOOM.exe" match "recursion.txt"? NO... | | Does it have subfolders? NO... Return. | | | Does "C:\games" have any more subfolders? NO... Return. | Does "C:" have any more subfolders? YES... OK, Recurse. | | Find( "recursion.txt", "C:\school" ) | Does "C:\school" have the recursion.txt file? NO... | Does it have subfolders? YES... OK, Recurse. | | | | Find( "recursion.txt", "C:\school\cs210" ) | | Does "C:\school\cs210" have the recursion.txt file? | | NO... Does it have subfolders? NO... Return. | | | Does "C:\school" have any more subfolders? YES... OK, Recurse. | | | | Find( "recursion.txt", "C:\school\cs235" ) | | Does "C:\school\cs235" have the recursion.txt file? *YES*... | | OK, return this path. | | | "C:\school\cs235" path was returned, continue returning it. | "C:\school\cs235" path was returned, continue returning it.
And the result for finding the recursion folder is
"C:\school\cs235". - Example: Solving a maze
Solving a maze can be approached from a recursive standpoint much easier than an iterative one.
Terminating cases:
- If we get to the end of the maze, SUCCESS.
- If we hit a dead-end, GO BACK (return).
Recursive case: Explore each available direction, except the direction you came from.
- Try to go NORTH
- Try to go EAST
- Try to go SOUTH
- Try to go WEST
Example step-through, going from A to B (
@) is current location.######## Path so far: ### ## # Recursive case: Can't go NORTH, can go EAST... A @ ## Z ### # ######## ######## Path so far: E ### ## # Recursive case: Can't go NORTH, can go EAST... A @ ## Z ### # ######## ######## Path so far: E E ### ## # Recursive case: Can't go NORTH, can go EAST... A @ ## Z ### # ######## ######## Path so far: E E E ### ## # Recursive case: Can go NORTH... A @## Z ### # ######## ######## Path so far: E E E N ###@## # Recursive case: Can't go NORTH, can't go EAST, A ## Z can't go WEST... ### # Return to previous location... ######## ######## Path so far: E E E ### ## # Recursive case: Already went NORTH. A @## Z Can't go EAST... Can go SOUTH... ### # ######## ######## Path so far: E E E S ### ## # Recursive case: Can go EAST... A ## Z ###@ # ######## ######## Path so far: E E E S E ### ## # Recursive case: Can go EAST... A ## Z ### @ # ######## ######## Path so far: E E E S E E ### ## # Recursive case: Can go EAST... A ## Z ### @ # ######## ######## Path so far: E E E S E E E ### ## # Recursive case: Can go NORTH... A ## Z ### @# ######## ######## Path so far: E E E S E E E N ### ## # Recursive case: Can go NORTH... A ##@ Z ### # ######## ######## Path so far: E E E S E E E N N ### ##@# Recursive case: Can't go NORTH, can't go EAST, A ## Z can't go WEST. ### # Return to previous location... ######## ######## Path so far: E E E S E E E N ### ## # Recursive case: Can go EAST... A ##@ Z ### # ######## ######## Path so far: E E E S E E E N E ### ## # Made it to the end! A ## @Z Return "EEESEEENE" as the solution! ### # ########
- Example: Searching a File System
5.8. Week 8: Debugging, searching, and sorting
5.8.1. 📚 Intro: General debugging
Being able to read and interpret error messages is really important in programming. Especially when just starting off, you will be making a lot of syntax errors until you learn the language better.
Make sure you're reading the error messages that the compiler gives you. Usually it will give you a line number you can check, as well as a message to try to explain why the compiler doesn't understand. The messages can be a bit cryptic sometimes, but you can usually do a search and find forum posts explaining how to fix the error.
Make sure to take your own notes while going through the concept introduction! That way you can refer back to this information more easily!
- Debugging strategies
I have been programming for over two decades. Beyond learning programming syntax, part of software development is also learning how to approach challenges and how to analyze problems.
Early on, it's important to minimize bugs in your code so you don't have too many things to fix at once. Here are some important strategies I highly recommend you use to minimize coding headaches.
Review 1. Write only a few lines of code and build after those few lines. This way, if you made any syntax errors, you'll be able to see the errors right away and have a smaller amount of code to look through to try to fix. If you write a ton of code all at once instead…
- ○ You might get a ton of errors, making it overwhelming to try to get things working again!!
- ○ It will be just fine because it's highly unlikely that you'll make mistakes. C++ is a famously non-finnicky language.
Review 2. Oh no! You wrote your entire program all at once without trying to build along the way. Now when you try to build, there's a TON OF ERRORS! What's the best way of fixing it all?
- ○ Do a little "please stop being broken" dance.
- ○ Comment out large chunks of code until things build again. Then, slowly uncomment out small chunks of code and then building to check for errors, fixing the few errors that pop up at a time. Do this until you've uncommented out the entire program.
- ○ Create a new project and start over from the beginning. Hopefully this time you won't make the same mistakes!
Review 3. When your program builds but something is going wrong in the program how should you go about diagnosing the problem to try to find where it stems from?
- □ Ask yourself "What am I expecting it to do that it is NOT doing?"
- □ Erase the entire program and start over.
- □ Step through the program manually, writing down the variable values as they change.
- □ Shake your fist at your computer angrily.
- Error message #1 (name = Rachel;)
Review 4. While trying to build some code, the following error is generated:
error: use of undeclared identifier 'Rachel' name = Rachel;
- a. What does this error describe?
- ○ The compiler thinks the name variable should be in double-quotes because it is a string.
- ○ The compiler is expecting there to be a variable named Rachel that it can copy the value of into the name variable.
- ○ The compiler dislikes Rachel personally and will not allow them to write any C++ code.
- b. Can you tell what the programmer's original intention was
with this line of code?
- ○ To assign the name "Rachel" to the variable
name. - ○ To copy the value from the
Rachelvariable to thenamevariable.
- ○ To assign the name "Rachel" to the variable
- c. The programmer probably wanted Rachel to be a string
literal, a value to store into name. They probably didn't
intend to create a variable named Rachel. So how could this be
fixed?
○ Change the code to
name = "Rachel";○ Change the code to
string Rachel; name = Rachel;
- a. What does this error describe?
- Error message #2 (float price = $9.99;)
Review 5. While trying to build some code, the following error is generated:
main.cpp:7:13: error: expected ';' after expression float price = $9.99; ^ ; main.cpp:7:11: error: use of undeclared identifier '$9' float price = $9.99;These errors don't point to the actual issue with the code, but the compiler doesn't know how to read what has been written. Let's look at the errors and try to track down the issue…
- a. What is the first error saying, from the compiler's point of view?
- ○ The compiler doesn't see the ; at the end of the line.
- ○ The compiler is expecting a ; after the data type.
- b. What is the second error saying, from the compiler's point of view?
- ○ The $9 should be in double quotes.
- ○ No variable named $9 has been declared at the time of usage.
- ○ The $ should be in single quotes.
- c. The error messages pop up at the line that is causing a
problem, but the compiler literally cannot read what we
wrote, so it's giving us errors that it sees, but aren't
useful to us. Can you tell which part of the code is causing
an error?
- ○ Float values can't have
. - ○ Floats must be set with
cin - ○ Float values can't have
$
- ○ Float values can't have
- d. What is the proper way to assign a value of 9.99 to the
price variable?
- ○
price = "$9.99"; - ○
price = '$' + 9.99; - ○
price = 9.99;
- ○
- a. What is the first error saying, from the compiler's point of view?
- Error message #3 (adding a and b)
Review 6. While trying to build some code, the following error is generated:
main.cpp:14:3: error: use of undeclared identifier 'c' c = a + b; ^ main.cpp:15:25: error: use of undeclared identifier 'c' cout << "Result: " << c << endl;
And the program code looks like this:
#include <iostream> #include <string> using namespace std; int main() { int a, b; cout << "Enter a: "; cin >> a; cout << "Enter b: "; cin >> b; c = a + b; cout << "Result: " << c << endl; return 0; }
- a. What do the error messages mean?
- ○ The compiler is expecting "c" to store the sum of "a" and "b", but the data types don't match.
- ○ The compiler is expecting there to be a variable named "c" but the variable has not been declared.
- ○ The compiler doesn't allow variables named "c" because "C" is a programming language.
- b. Can you tell what is wrong with the program?
○
aandbare being input withcin, butcis not. We should addcin >> c;
○
cis being outputted with the result but it should be "c" instead. We should write:cout << "Result: c" << endl;○
aandbare declared as integers, butcis not declared anywhere. We should addint c;
- a. What do the error messages mean?
- Error message #4 (cin statement)
Review 7. While trying to build some code, the following error is generated:
error: reference to overloaded function could not be resolved; did you mean to call it? cin >> name >> endl;
And the program code is:
#include <iostream> #include <string> using namespace std; int main() { string name; cout << "Enter your name: "; cin >> name >> endl; return 0; }
Can you tell what is wrong with this line of code?
- ○ The
cinshould be acoutinstead. - ○
endlcannot be used withcinstatements. - ○ The stream operators should be
<<instead of>>.
- ○ The
- Logic errors and basic techniques
Here are some "oldie" ways to track down errors without an actual debugger:
coutat each step: If you're trying to figure out where a program is crashing, it can be handy to add a cout statement every few lines of code to track which step it crashed afterwards.coutvariable values: It can also be handy to display the value of variables as the program is running to make sure the variables are storing the data you're expecting.- adding error checks to your programs: You can add if statements to check for errors, such as making sure you don't divide by 0 before the division occurs.
Review 8. Given this code:
int main() { cout << "How many sandwiches? "; float totalSandwiches; cin >> totalSandwiches; cout << "How many guests? "; float totalGuests; cin >> totalGuests; if ( totalGuests == 0 ) { cout << "ERROR: Cannot divide by 0!" << endl; return 1; } float sandwichesPerPerson = totalSandwiches / totalGuests; cout << "Sandwiches per guest: " << sandwichesPerGuest << endl; return 0; }
What kind of diagnosis tool is this?
- ○
coutvariable values - ○ Error check
- ○
coutat each step
- Additional tips
Review 9. Identify what the following error messages generally imply
- a. Undeclared identifier
- ○ Compiler is expecting a variable to be declared, but it is not.
- ○ There is a semicolon missing at the end of a statement
- b. Expected ; at end of line
- ○ Compiler is expecting a variable to be declared, but it is not.
- ○ There is a semicolon missing at the end of a statement
Review 10. When you encounter a compile error you should…
- □ Look at the line number referenced in the error
- □ Scream
- □ Read the error message
- □ Search for the error message online if you can't tell why the error is occurring
Review 11. You should always tackle programming assignments by programming the entire thing before doing any building or testing.
○ True / ○ False
- a. Undeclared identifier
5.8.2. 📚 Intro: Debugging tools - lldb and gdb
- Introduction
There are special tools called debuggers that we can use to trace through our code, look at program flow, variable values, and more. A debugger is an invaluable tool in software development, so let's learn the super basics.
GDB stands for "GNU DeBugger", and it is a program to help you debug your programs. It allows you to step through the program as it runs, line-by-line, allows you to inspect values of variables throughout the program execution, and view which functions have been called.
On Mac computers, installing the XCode environment should automatically also set up the
lldb(L L D B, all lowercase) debugger.Many Integrated Development Environments contain debuggers that you can use more visually, but we are going to cover the absolute basics here.
Review 1. A debugger program lets you…
- □ Pause program execution at a specific line of code
- □ View variable values
- □ View a list of function calls leading to where the program is currently at
- □ Order a pizza
- Building a program with debugging symbols
To use your program in the debugger you need to make sure to build it with the
-gflag:g++ FILENAME.cpp -g -o PROG.exe
Review 2. To be able to use gdb/lldb we need to build our source code with which flag?
- ○ -W
- ○ -g
- ○ -o
- ○ -f
- Start the debugger with the built program executable
Run the debugger with the program executable second to load it into the debugger program. When the program is running you'll see a prompt where you can enter commands. The prompt begins with
(gdb)or(lldb).gdb (win/linux):
gdb PROG.exe
lldb (mac/linux):
lldb PROG.exe
Review 3. The running gdb/lldb programs have a prompt where you…
- ○ enter in commands
- ○ stare at it helplessly
- ○ cry
- Run the program
The
runcommand will run through the program as normal and display the program's output to the screen.runin gdb (win/linux):(gdb) run Starting program: .../practice1_debug_stepthru/simple.exe [Thread debugging using libthread_db enabled] Using host libthread_db library "/lib/x86_64-linux-gnu/libthread_db.so.1". 1 + 91 = 92 [Inferior 1 (process 26807) exited normally]
runin lldb (mac/linux):(lldb) run Process 26332 launched: '.../practice1_debug_stepthru/simple.exe' (x86_64) 0 + 39 = 39 Process 26332 exited with status = 0 (0x00000000) (lldb)
- Setting breakpoints
You can set breakpoints in your code. When the program is run, once the line of code with a breakpoint is hit, it will pause execution. You can then view variable values and step through the code line-by-line.
- Setting a breakpoint by function name:
breakpoint set -n mainin lldb (mac/linux):(lldb) breakpoint set -n main Breakpoint 1: where = simple.exe`main + 12 at simpleprogram.cpp:8:16, address = 0x0000000000001235
break mainin gdb (win/linux):(gdb) break main Breakpoint 1 at 0x555555555235: file simpleprogram.cpp, line 8.
- Setting a breakpoint by file/line number:
break crash.cpp:8in gdb (win/linux):(gdb) break crash.cpp:8 Breakpoint 1 at 0x555555556539: file crash.cpp, line 8.
breakpoint set --file crash.cpp --line 8in lldb (mac/linux):(lldb) breakpoint set --file crash.cpp --line 8 Breakpoint 1: where = crash.exe`DisplayValue(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >*) + 16 at crash.cpp:8:14, address = 0x0000555555556539
Review 4. How do you set the following breakpoints using gdb?
- A. A breakpoint at the start of the main function?
- B. A breakpoint in file "bob.cpp" at line 5?
- Setting a breakpoint by function name:
- Stepping through code
While paused in the program execution you can step line-by-line through the program to look at how it flows. The
nextcommand will step line by line, skipping over any function calls, while thestepcommand will step line by line, stepping into any function calls.Command What it does nextStep (over) to the next line stepStep (into) the next line (will enter function calls) finishLeave the current function to continue stepping from previous function continueContinue running the program as normal until the next breakpoint - Viewing variable values
While the program is paused you can view the value of any variables that are currently in-scope by using the
printfunction.printin gdb (win/linux):(gdb) print number1 $2 = 3
printin lldb (mac/linux):(lldb) print number1 (int) $1 = 1
- Viewing the backtrace
If the program crashes or if you're paused on a breakpoint you can use the
btcommand to view the list of functions that have been called up until the point you're at in the program. The "oldest" (first called) function is on the bottom, and the "newest" function is on the top.btin gdb (win/linux):(gdb) bt #0 0x00007ffff7ebc4c4 in std::basic_ostream<char, std::char_traits<char> >& std::operator<< <char, std::char_traits<char>, std::allocator<char> >(std::basic_ostream<char, std::char_traits<char> >&, std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> > const&) () from /lib/x86_64-linux-gnu/libstdc++.so.6 #1 0x000055555555654f in DisplayValue (ptr=0x0) at crash.cpp:8 #2 0x00005555555565c7 in DisplayAll (ptrs=std::vector of length 4, capacity 4 = {...}) at crash.cpp:16 #3 0x0000555555556790 in main () at crash.cpp:25btin lldb (mac/linux):(lldb) bt [...] * thread #1, name = 'crash.exe', stop reason = signal SIGSEGV: invalid address (fault address: 0x8) * frame #0: 0x00007ffff7ebc4c4 libstdc++.so.6`std::basic_ostream<char, std::char_traits<char> >& std::operator<<<char, std::char_traits<char>, std::allocator<char> >(std::basic_ostream<char, std::char_traits<char> >&, std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> > const&) + 4 frame #1: 0x000055555555654f crash.exe`DisplayValue(ptr=<parent failed to evaluate: parent is NULL>) at crash.cpp:8:14 frame #2: 0x00005555555565c7 crash.exe`DisplayAll(ptrs=size=1) at crash.cpp:16:21 frame #3: 0x0000555555556790 crash.exe`main at crash.cpp:25:15 frame #4: 0x00007ffff7b4dd90 libc.so.6`__libc_start_call_main(main=(crash.exe`main at crash.cpp:21:1), argc=1, argv=0x00007fffffffde38) at libc_start_call_main.h:58:16 frame #5: 0x00007ffff7b4de40 libc.so.6`__libc_start_main_impl(main=(crash.exe`main at crash.cpp:21:1), argc=1, argv=0x00007fffffffde38, init=0x00007ffff7ffd040, fini=<unavailable>, rtld_fini=<unavailable>, stack_end=0x00007fffffffde28) at libc-start.c:392:3 frame #6: 0x0000555555556465 crash.exe`_start + 37
Review 5. Which command does what?
step next finish continue print bt - a. Move to next line in code
- b. Step into a function's code
- c. Leave the current function and return to the previous
- d. Unpause and continue running the program until the next breakpoint
- e. View a list of functions called up until this point
- f. Display the value of a variable given
- Additional reading
5.8.3. 📚 Intro: Searching algorithms
Video - Linear Search:
Video - Binary Search:
- Linear search
When we're searching for items in an unsorted linear structure there's not much we can do to speed up the process. We can basically either start at the beginning and move forward, or start and the end and move backward, checking each item in the structure for what you're looking for.
template <typename T> int LinearSearch( const vector<T>& arr, T findme ) { int size = arr.size(); for ( int i = 0; i < size; i++ ) { if ( arr[i] == findme ) { return i; } } return -1; // not found }
- We begin at the first index 0 and iterate until we hit the last index.
Within the loop, if the element at index
imatches what we're looking for, we return this index. - If the loop completes and we haven't returned an index yet that means we've
searched the entire structure and have not found the item.
- In this case, it is not in the structure and we can throw an exception to \
be dealt with elseware or return something like -1 to symbolize "no valid
index". This search algorithm's growth rate is
O(n)– the more items in the structure, the time linearly increases to search through it. Not much we can do about that, which is why we have different types of data structures that sort data as it is inserted - more on those later on.
- In this case, it is not in the structure and we can throw an exception to \
be dealt with elseware or return something like -1 to symbolize "no valid
index". This search algorithm's growth rate is
- We begin at the first index 0 and iterate until we hit the last index.
Within the loop, if the element at index
- Binary search
OK, but what if the structure is sorted?
We're going to be learning about sorting algorithms, so what if we happen to have a structure that is sorted? How can we more intelligently look for some value in the structure?
Let's say we have a simple array like this:
Value: "aardvark" "bat" "cat" "dog" "elephant" "fox" Index: 0 1 2 3 4 5 And we want to see if "dog" is in the array. We could investigate what the first item is (Hm, starts with an "a") and the last item ("f"), and realize that "d" is about halfish way between both values. Maybe we should start in the middle and move left or right?
- Index 0 is "aardvark". Index 5 is "fox".
Middle value (0+5)/2 is 2.5 (or 2, for integer division).
What is at position 2? – "cat".
If
arr[2] < findme, move left (investigatearr[1]next) Or ifarr[2] > findme, move right (investigatearr[3]next). - "d" is greater than "c" so we'll move right… Index 3 gives us "dog" - we've found the item! Return 3.
In this case, we basically have two iterations of a loop to find "dog" and return its index. If we were searching linearly, we would have to go from 0 to 1 to 2 to 3, so four iterations.
This still isn't the most efficient way to search this array - just starting at the midpoint and moving left or moving right each time. However, we can build a better search that imitates that first step: Checking the mid-way point each time.
Here is the code:
template <typename T> int BinarySearch( vector<T> arr, T findme ) { int size = arr.size(); int left = 0; int right = size - 1; while ( left <= right ) { int mid = ( left + right ) / 2; if ( arr[mid] < findme ) { left = mid + 1; } else if ( arr[mid] > findme ) { right = mid - 1; } else if ( arr[mid] == findme ) { return mid; } } return -1; // not found }
With the binary search we look at the left-most index, right-most index, and mid-point. Each iteration of the loop, we look at our search value
findme– is its value greater than the middle or less than the middle?- Example: Binary search on a sorted array
Let's say we have this array, and we are searching for 'p':
Value: 'a' 'c' 'e' 'h' 'i' 'k' 'm' 'o' 'p' 'r' Index: 0 1 2 3 4 5 6 7 8 9 Step 1:
leftis at 0,rightis at 9,midis(0+9)/2 = 4(integer division).Value: 'a' 'c' 'e' 'h' 'i' 'k' 'm' 'o' 'p' 'r' Index: 0 1 2 3 4 5 6 7 8 9 left mid right Next we compare
ito'p'.'p'comes later in the alphabet (sop > i), so next we're going to change theleftvalue to look atmid+1and keeprightas it is.Step 2:
leftis at 5,rightis at 9,midis(5+9)/2 = 7).Value: 'a' 'c' 'e' 'h' 'i' 'k' 'm' 'o' 'p' 'r' Index: 0 1 2 3 4 5 6 7 8 9 left mid right Now we compare the item at
arr[mid]'o'to what we're searching for ('p').p > oso we adjust our left point again to our current midpoint.Step 3:
leftis at 7,rightis at 9,midis(7+9)/2 - 8.Value: 'a''c''e''h''i''k''m''o''p''r'Index: 0 1 2 3 4 5 6 7 8 9 left mid right Now we compare the item at
arr[mid]('p') to what we're searching for ('p'). The values match! So the result ismidas the index where we found our item.Each step through the process we cut out half the search area by investigating mid and deciding to ignore everything either before it (like our example) or after it. We do this every iteration, cutting out half the search region each time, effectively giving us an efficiency of \(O(log(n))\) - the inverse of an exponential increase.
- Index 0 is "aardvark". Index 5 is "fox".
Middle value (0+5)/2 is 2.5 (or 2, for integer division).
What is at position 2? – "cat".
If
5.8.4. 📚 Intro: Sorting algorithms
Video - Bubble Sort:
Video - Insertion Sort:
Video - Selection Sort:
There are various sorting algorithms that are used to put data in ascending or descending order. Some algorithms are slow and some are fast, though the faster ones tend to have more complex code and the slower ones have simpler code. We will be covering the slow, simple algorithms here.
While sorting, we look at two different items in the array and swap them if they're out of order. How we traverse the array is what makes the different algorithms.
You don't need to memorize these algorithms and I don't test on them. You will see them in future Computer Science courses, but these algorithms aren't secret, you can find pseudocode and implementations everywhere online. The main idea is to see how they work and become acquainted with them.
In the real world you won't be implementing sorting algorithms; you'll be using sorts that are already provided by the language or some third-party library.
- Sorting algorithm efficiency
Sorting algorithm efficiency (From https://www.bigocheatsheet.com/)
Algorithm Best time Average time Worst time Bubble Sort Ω(n) Θ(n2) O(n2) Insertion Sort Ω(n) Θ(n2) O(n2) Selection Sort Ω(n2) Θ(n2) O(n2) Merge Sort Ω(n log(n)) Θ(n log(n)) O(n log(n)) Quick Sort Ω(n log(n)) Θ(n log(n)) O(n2) - Bubble Sort
Video: Bubble Sort Visualization by Abhilas Biswas
vector<string> BubbleSort(vector<string> arr) { for ( size_t i = 0; i < arr.size() - 1; i++ ) { for ( size_t j = 0; j < arr.size() - i - 1; j++ ) { if ( arr[j] > arr[j+1] ) { Swap( arr[j], arr[j+1] ); } } } return arr; // Return the sorted version of the vector }
With Bubble sort the outer loop makes sure we go from the beginning to the end of the array (minus one). The inner loop, with variable
j, is the one that is actually used to check each elementjwith its right neighborj+1. Ifarr[j]is greater thanarr[j+1]then they're out of order and will be swapped. - Selection sort
Video: Selection Sort Visualization by Abhilas Biswas
vector<string> SelectionSort(vector<string> arr) { for ( size_t i = 0; i < arr.size() - 1; i++) { size_t minIndex = i; for ( size_t j = i + 1; j < arr.size(); j++ ) { if ( arr[j] < arr[minIndex] ) { minIndex = j; } } if ( minIndex != i ) { Swap( arr[i], arr[minIndex] ); } } return arr; // Return the sorted version of the vector }
With Selection Sort our outer loop
igoes from the beginning to the end (minus one). At the start of this outer loop, we assume the smallest item we've found is that first item at positioni. We keep a variableminIndexto keep track of the smallest value we find.The internal loop
jstarts ati's right neighbor and goes to the end of the array. Eacharr[j]will be inspected and ifarr[j]is less than thearr[minIndex], then theminIndexis now set toj.After the
jloop ends, if theminIndexis not equal toi, then that means we found a new smallest item, so we swaparr[i]andarr[minIndex]. - Insertion Sort
Video: Insertion Sort Visualization by Professor Painter
vector<string> InsertionSort(vector<string> arr) { size_t i = 1; while ( i < arr.size() ) { size_t j = i; while ( j > 0 && arr[j-1] > arr[j] ) { Swap( arr[j], arr[j-1] ); j--; } i++; } return arr; // Return the sorted version of the vector }
With Insertion Sort, our outer loop goes from
i=1to the end of the array. We initializejtoi's value, then our internal loop moves backwards fromj's current position while the item on the left (arr[j-1]) is greater than the current value (arr[j]). While it finds things out of order, it swaps the two (arr[j]andarr[j-1]) and then movesjto the left.
5.9. Week 9: Classes
5.9.1. 📚 Intro: Object Oriented Programming
Video - Intro to OOP:
Video:
<iframe src="https://www.youtube.com/embed/Dm8dQ-1QoTI" width="270" height="480" title="YouTube video player" frameborder="0" allowfullscreen> </iframe>
Overview:
- Terms to know: Object Oriented Programming, abstraction, encapsulation, coupling, cohesion, inheritance, composition, accessibility levels, public, private, protected, UML
- Concepts: Be able to read UML diagrams
- Programming paradigms
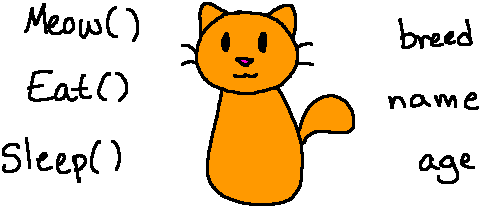
Programming paradigms (pronounced "pair-uh-dimes") are ways we can classify different programming languages based on features they have available or the style programs are written. Different paradigms have popped up over the life of computers as programming languages grow and evolve.
- Machine code:
At the beginning, computers were programmed with machine code, where you
work directly with instructions supported by the hardware - for example,
add,sub, storing data in registers, and other relatively simple commands. - Procedural Languages: Eventually, those commands were abstracted into higher-level languages, where one command in, say, C, could "translate" to several machine-code instructions. Languages like C, Fortran, Algol, BASIC, and C are known as Procedural Languages, where these programs would describe a procedure to follow and instructions are executed one-at-a-time in a specific order (top-to-bottom, or calling a function and returning).
- Object Oriented Programming: Languages like C supported our basic control flow and using functions, but did not include classes - a way to make more sophisticated data types. A class is a structure that can store its own member variables and member functions. A variable whose data type is from some defined class is known as an object.
There are other programming paradigms, but we are going to focus on Object Oriented Programming (OOP) now since it's a large part of using C++ and other languages like Java, C#, and Python.
- Introduction to Object Oriented Programming
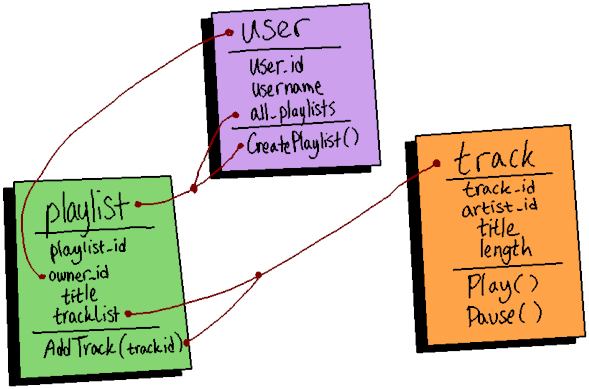
Object Oriented Programming (or "OOP") is probably one of the most popular ways to design and implement software these days. In programming, an object is some sort of structure that stores its own data (variables) and functionality (functions). We try to design our programs as a collection of objects that interact with each other to get some job done.
In C++ and many other languages functions always end with parentheses ( ), which is how you can quickly identify them. Sometimes, there is data in the parentheses - these are input parameters. Functions can also return data as well, so each interaction between objects can pass inputs between objects, and return data between objects.
- Design ideals
Designing programs in an OOP style helps us pursue certain design goals:
- Abstraction: Hiding complexity in the design, creating an "interface" for
the user, generalizing functionality to a more "digestible" form. Think of a
button on any device: If you open up the device, there's a lot actually going
on, but we just see the simple button and don't have to worry about the rest.
- Certain functions are made public that other programmers can use to interface with the object.
- The other programmers don't need to worry about the inner-workings of the object in order to use it.
- The developer of the class can modify how the internals work without breaking the public interface.
- Helps protect the data within the class from being accessed or modified by things it shouldn't.
- Encapsulation: Also goes along with creating an "interface", though in this regard we are encapsulating related pieces together. We can store data (variables) with the functions that operate on that data (functions) all within a class object.
- Loose coupling: Ideally, different objects in a program shouldn't have their functionality tied to other objects too closely; we want to reduce inter-dependence between objects. When objects are more independent from each other, they are loosely coupled.
- High cohesion: When we design our objects, we shouldn't just throw everything and the kitchen sink into one object. To design an object with high cohesion means that everything inside the object belongs in that object. Reduce the clutter.
Review 1. Following good design, a single class should represent
○ Multiple items / ○ A single item
Review 2. It is good to mark member variables as…
○ public / ○ private
…so that…
○ fewer regions of code touch that data
○ the data is accessible to all items in the program
○ we maintain job security because nobody knows what our classes do
Review 3. We want two different classes to be
○ highly dependent on each other
○ independent from each other
- Abstraction: Hiding complexity in the design, creating an "interface" for
the user, generalizing functionality to a more "digestible" form. Think of a
button on any device: If you open up the device, there's a lot actually going
on, but we just see the simple button and don't have to worry about the rest.
- Machine code:
At the beginning, computers were programmed with machine code, where you
work directly with instructions supported by the hardware - for example,
- Inheritance and composition
Sometimes we have multiple objects that are similar but still have different sets of data (member variables) - think of a File, how we might have an Image File, Sound File, Video File… Each file has a name, file extension, and size, but the actual file contents are different.
And sometimes we have an object that is best represented by being "inside" another object - think of a House with an array of Room objects. These are the two ideas between inheritance, an "is-a" relationship, and composition, a "has-a" relationship.
With inheritance:
- Variables and functions from a class can be inherited by child classes. This means that the child class will have these same variables and functions, without having to re-write it all.
- We use this to create specialized versions of some generic object, like a GameObject, PlayerObject, and NPCObject, or a Shape, Square, and Circle.
With composition:
- One class is a member variable of another class, and is generally a private member.
- Often this means that the internal class can't be accessed by outside functions, and the "containing" class needs to have some kind of interface layer to allow interactions with that internal item.
- Some people argue that you should prefer using composition over inheritance because the act of composing another class keeps it "modularized"; that class' features are encapsulated within a variable, and not more inherited variables added onto the pile-o-variables a class has.
- Accessibility levels
When we're designing our objects we don't want to give unrestricted access to every part of the program. We generally create a class and it is responsible for certain things, including modifying its own data. This helps us protect the integrity of the data. Each member variable and function belonging to a class can be marked as one of these three accessibility levels:
- public:
- Any part of the program can access these members. This is usually used for the member functions of a class.
- private:
- These members can only be accessed by the class itself, from within its functions.
- protected:
- Similar to private except that classes that inherit from the class we're defining will also have access to protected members. More on this when we cover inheritance.
- Review 4. Identify which description refers to inheritance and which
description refers to composition.
Class B has all the public/protected member variables and functions of Class A.
○ Inheritance / ○ Composition
Class B is a member variable of Class A
○ Inheritance / ○ Composition
Review 5. Why is inheritance and composition used?
○ It looks fanicer
○ It makes the codebase harder to read
○ It reduces having duplicate code
Review 6. What can access public members of a class? (Select ALL correct answers)
□ The class' functions
□ The class' childrens' functions
□ Functions that do not belong to the class' family
Review 7. What can access protected members of a class? (Select ALL correct answers)
□ The class' functions
□ The class' childrens' functions
□ Functions that do not belong to the class' family
Review 8. What can access private members of a class? (Select ALL correct answers)
□ The class' functions
□ The class' childrens' functions
□ Functions that do not belong to the class' family
- Modeling C++ classes using UML
UML (Unified Modeling Language) is a way to diagram classes, their member variables and functions (methods), and relationships between those classes. It is meant as a language-agnostic way to describe your codebase or how something should be designed.
- Describing a single object
A UML diagram for a single class looks like this:
Player - x: int- y: int- image: Texture+ Setup(): void+ Move(velX: float, velY: float): void+ BeginJump(): void+ BeginAttack(): void+ Draw(screen:Window): voidHere's how to read it:
- The TOP region is the name of the class.
- The MIDDLE region is its member variables.
- The BOTTOM region is its member methods/functions.
- The
-minus sign signifiesprivateaccessibility level, which means these members can only be accessed by this class' functions. - The
+plus sign signifiespublicaccessibility level, which means these members can be accessed by this class' functions or any functions external to it (like belonging to another class, or inmain()). - A
#pound sign signifiesprotectedaccessibility level (used with inheritance, which we will cover more later).
- Describing relationships between objects
UML diagrams are also used to show the relationship between classes.
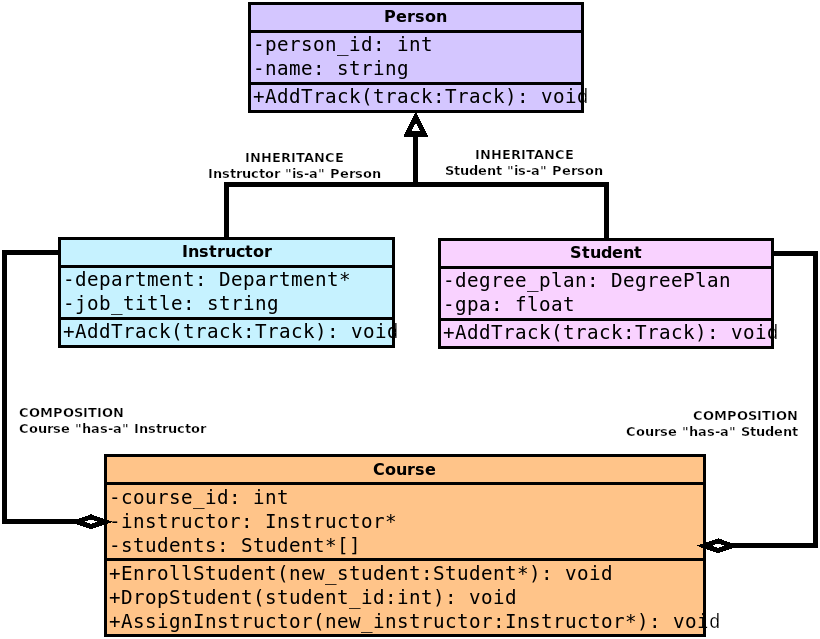
In a diagram that shows a relationship between objects you will see arrows going between classes.
- A line coming FROM a class and ending in a triangle arrow to another class shows an inheritance relationship, with the former inheriting from the latter.
- A line coming FROM a class and ending in a diamond shape to another class shows a composition relationship, with the former being contained within the latter.
Using UML diagrams can be (relatively) quick to write out and to read, compared to just giving someone a .h header file or all the code itself. Often, companies will have some kind of global UML diagram of all of the components in their codebase and how they interact - developers are expected to update this diagram as they add/remove classes or members of classes.
- Review 9. In UML…
- Variables are shown as the (○ top / ○ middle / ○ bottom) section.
- Functions are shown as the (○ top / ○ middle / ○ bottom) section.
- The (○ + / ○ -) sign denotes "public accessibility".
- The (○ + / ○ -) sign denotes "private accessibility".
- Describing a single object
5.9.2. 📚 Intro: Class basics
Overview:
- Terms to know: Struct, class, object, dot operator, member variable, member function (method), accessibility, public, private, protected, getter (accessor), setter (mutator), constructor, destructor, scope resolution operator, shallow copy, deep copy
- Concepts:
- How to declare a class and its members in a .h file.
- How to define a class' member functions (methods) in a .cpp file.
- How to declare an object-variable whose type is a class.
- How to access members via an object-variable.
- What can access public, protected, and private members?
- How to declare and define getter and setter functions.
- How to declare and define constructors and destructors
- Structs vs. Classes
Structs in C++ have all the same functionality of a Class, but are generally used design-wise to group a few variables together, maybe some functions, into a simple structure. A class, on the other hand, is usually used for much bigger and more complex objects.
In C++, the only difference between Structs and Classes are default accessibility - if you don't specify the accessibility of your variables/functions within a struct, they are
publicby default. This means that anything in the program can access those variables/functions. For Classes, everything isprivateby default - only that Class itself can use the variables/functions.- Declaring a struct
Struct declarations go in header (.h) files. Usually the file name should reflect the name of the struct itself, and the file guard labels should also match.
#ifndef _STRUCTNAME #define _STRUCTNAME struct STRUCTNAME { int var; void Func(); }; #endif
Design-wise, structs should only contain a small amount of data. While structs can contain functions, it is generally better to create a class if you find yourself needing functions.
An example of a small struct would be grouping
xandycoordinates together in a Coordinate Pair…struct CoordinatePair { float x, y; };
Sometimes we need to group some basic variables together. Structs are great for this.
struct Rectangle { float left, right, top, bottom; };
- Declaring object variables
Once a struct has been declared in a program, you can then create a variable with that data type. To access the internal variables of the struct, you use the variable's name followed by the dot operator
.and then the name of the member variable.// Declare two variables CoordinatePair point1, point2; cout << "Enter the x y coordinates for the first point: "; cin >> point1.x >> point1.y; cout << "Enter the x y coordinates for the second point: "; cin >> point2.x >> point2.y; float slope = ( point2.y - point1.y ) / ( point2.x - point1.x ); cout << "The slope is: " << slope << endl;
We will have more examples during the section on Classes, since that's mostly what we will be using. Again, structs are useful for combining a small amount of member variables together under one name, usually used for structures for math (coordinates, rectangles, etc.) but more sophisticated objects ought to be created with a class.
Best practices:
- Declaring a struct
- Classes introduction
Traditionally, a struct is used to create small objects that join a few variables together. Classes are much more heavily used in C++ and is the back-bone of Object Oriented Programming. There is a lot we can do with classes, but for now we are just going to look at the basics.
A class declaration looks just like a struct declaration except that we use the keyword
class. Take note that with a struct and class declaration, we must end the closing curly brace with a semi-colon.Best practices:
Example: Declaring a Player class
class Player { public: void SetPosition( int newX, int newY ); void Move(); private: int x, y; };
Review 1. Structs should be used for…
- ○ larger objects with variables and functions
○ small objects with just a few variables
… and Classes should be used for…
- ○ larger objects with variables and functions
- ○ small objects with just a few variables
- Member accessibility
We can define our member variables and functions with three different levels of accessibility, dictating where these members can be accessed throughout the program:
- public:
- Any part of the program can access these members. This is usually used for the member functions of a class.
- private:
- These members can only be accessed by the class itself, from within its functions.
- protected:
- Similar to private except that classes that inherit from the class we're defining will also have access to protected members. More on this when we cover inheritance.
Best practices:
Review 2. Given this snippet of code:
int main() { Button submitButton; submitButton.text = "Sign up!"; }
The Button class must have a member variable named "text", and its accessibility is…
○ public / ○ protected / ○ private
Review 3. It is good practice to make member variables private and provide public functions as a way to interface with those behind-the-scenes variables.
According C++ Core Guidelines C.9: Minimize exposure of members, what are the reason(s) for this? Select all relevant answers.
- □ Annoy fellow programmers
- □ Information hiding
- □ Minimize the chance of unintended access
- □ Simplifies maintenance
- Header and Source files
When we are creating a class, we generally will put the class declaration within its own header file. Header files end with .h or .hpp - I tend to use .hpp since we're using C++ and I like to explicitly state this is a "C++ header"; the .h extension was also used in C. However, the C++ Core Guidelines document says to use .cpp for code files and .h for interface files.
Additionally, don't forget that your header files need file guards! Microsoft likes to default to
#pragma once, but best practice is to use#ifndef ... #define ... #endbecause it's portable.Review 4. Class declarations go in _ files and the class' function definitions go in _ files.
Review 5. True or false: Other programmers will never write code that inadvertently messes up your code.
Review 6. True or false: You don't need to make sure the data in your program is safe and valid.
- Example: Rectangle class
Rectangle.h - Class declaration
#ifndef _RECTANGLE_H #define _RECTANGLE_H class Rectangle { public: void SetPosition( int newX, int newY ); void SetDimensions( int newWidth, int newHeight ); private: int x, int y, int width, int height; }; #endif
Rectangle.cpp - Class' function definitions
#include "Rectangle.h" void Rectangle::SetPosition( int newX, int newY ) { x = newX; y = newY; } void Rectangle::SetDimensions( int newWidth, int newHeight ) { width = newWidth; height = newHeight; }
In our source file (.cpp), we need to make sure to include the header that goes with our class so it knows about the class declaration. Then, we can define the member functions here. Note that when we're defining the functions outside of the class declaration, we must prefix the function name with the class name, followed by the scope resolution operator
::…void Rectangle::SetPosition( int newX, int newY )
This is the standard way C++ files are organized - for each class we create, we create a header and a source file for it.
- Example: Rectangle class
- Additional context with classes
- What is
#ifndef?- In C++, when we
#include "Rectangle.h"in a different source file, the compiler essentially copy-pastes the code from the included file into the include file. Because of this, if multiple files are#include "Rectangle.h"-ing (or any other header), the same code in that header gets copied multiple times, making the compiler think you've declared the same class over and over. #ifndef,#define, and#endifare preprocessor commands used by the compiler. We are essentially saying "if-not-defined_RECTANGLE_H, define_RECTANGLE_H, … … end-if.", preventing the compiler from copying the same file twice.
- In C++, when we
- Defining member functions inside the class declaration
- It is completely possible to define our member functions inside the class declaration, getting rid of the need for the .cpp file. However, this does end up being treated differently by the compiler - writing our class this way makes the functions inline… Basically, instead of having a separate function that the compiler will mark as "call this", it will copy the contents of the inlined function to the function call, basically replacing the call with the contents of the function. I haven't written much about how the compiler works since that's a more specialized topic and we don't need to worry about it at this stage of learning C++. This is just here for your own info.
- Should you define functions in the .h or the .cpp?
- It is standard to put class declarations and function declarations in .h files, and the function/method definitions in the .cpp files. You should follow this best practice.
- What is a Function vs. Method?
- A method is a word that means "member function". In Java and C#, the term method is used instead of function, since you physically cannot have functions defined outside of a class in those languages.
- I tend to stick with the term "member function", but if I write "method", it means that, whereas a "function" would be a standalone function elseware in the program.
Best practices:
- SF.2: A header file must not contain object definitions or non-inline function definitions
- SF.3: Use header files for all declarations used in multiple source files
- SF.5: A .cpp file must include the header file(s) that defines its interface
- SF.8: Use #include guards for all header files
- NL.27: Use a .cpp suffix for code files and .h for interface files
- What is
- Getters and Setters
In Object Oriented Programming, we generally want to hide the inner-workings of a class from the outside world (other functions and other classes). If everything were exposed, then other parts of the program could make changes to our class and it could be difficult to track down all those modifying locations (this, in particular, is a nightmare at a job with a large codebase). We generally write all our member variables as private - accessible only to the class' member functions themselves - and use public member functions to interface with those variables as needed.
For example, in our Rectangle class, we might have a function to set up the entire Rectangle all at once…
Rectangle.cpp - Defining Rectangle's Setup function
void Rectangle::Setup( int newX, int newY, int newWidth, int newHeight ) { x = newX; y = newY; width = newWidth; height = newHeight; }
… or just a couple things at a time …
Rectangle.cpp - Defining Rectangle's SetPosition function
void Rectangle::SetPosition( int newX, int newY ) { x = newX; y = newY; }
- Setter functions (mutators)
Or, we might want to just set one member variable's value. In this case, we write a member function called a setter (aka mutator) that is responsible for setting a member variable's value:
Rectangle.cpp - Defining Rectangle's SetX function
void Rectangle::SetX( int newX ) { x = newX; }
The good thing about having setters instead of directly updating the
xvariable is that we can add error checks in our setter. Say, perhaps, that we don't wantxto be negative, so we validate the input before changing it…void Rectangle::SetX( int newX ) { if ( newX >= 0 ) { x = newX; } }
If somewhere else in the program tries to set a negative value for the
xvariable, it will just ignore that command. (We could also throw an exception or display an error message or set a default value - it's up to your design.) - Getter functions (accessors)
Likewise, sometimes we want to access those member variables to see what values they store. In this case, we write Getter member functions that are responsible for returning a copy of the data (or, in some cases, a reference to it - but that's a design decision).
int Rectangle::GetX() { return x; }
Getters are also handy for formatting output prior to returning it, or doing some other operation before returning something. Let's say we have a member function for a
Studentclass, and aGetNamefunction is going to combine their names and return it together:int Student::GetFullName() { return lastName + ", " + firstName; }
To summarize…
- Setters: Sets the value of a member variable. Generally, return
type is
voidand there is one parameter for the new value.void SetThing( int newValue ); - Getters: Returns the value of a member variable. Generally,
return type matches that variable, and there are no parameters.
int GetThing();
Review 8. Having a setter/mutator function is good for…
- ○ Doing error checks before updating the data
- ○ Formatting the data before returning it
- ○ Wasting a programmer's time
Review 9. Having a getter/accessor function is good for…
- ○ Doing error checks before updating the data
- ○ Formatting the data before returning it
- ○ Making the tech writer's job harder
- Setters: Sets the value of a member variable. Generally, return
type is
- Setter functions (mutators)
- Constructors and Destructors
Constructors and Destructors are special types of member functions in a class.
- Constructor:
- Runs automatically as soon as a new object is declared.
- Can declare more than one constructor.
- No return type
- Constructor name must match name of the class.
- Destructor:
- Runs automatically as soon as a new object is destroyed.
- Can only have one destructor.
- No return type
- Destructor name \underline=must= match name of the class,
prefixed with a tilde
\~.
- Example: Text file wrapper
Let's say we're writing a class that works with a text file.
When the object is created, the constructor will open the file and get it ready to write to. With various member functions we can write to that text file as the program is running. Then, when the program ends and the object is destroyed, it will automatically close the text file for us.
Logger.h - Logger class declaration
class Logger { public: // constructors Logger( string filename ); Logger(); // destructor ~Logger(); // other method void Write( string text ); private: ofstream m_output; };
We have two constructors: one where we pass in a filename for a file to open, and one where we don't. In the second case, we can use a default file name.
Context: Why "
m_" with the variable?In some places, it is standard to prefix private member variables with an underscore (
_output) or (m_output). I tend to use the latter when writing private member variables of a class. The "m" stands for "member".The constructor definitions could look like this:
Logger::Logger( string filename ) { m_output.open( filename ); } Logger::Logger() { m_output.open( "log.txt" ); }
The
Writefunction could be used to write information to that text file, and could be implemented like this:void Logger::Write( string text ) { m_output << text << endl; }
And then the destructor would be used to close up the file at the end:
Logger::~Logger() { m_output.close(); }
Now, we don't have to manually deal with file operations since this class wraps that functionality and deals with it for us.
To use the program, we just declare the object variable:
#include "Logger.h" int main() { // This one calls the default constructor Logger logDefault; // This one calls the parameterized constructor Logger log( "logfile.txt" ); // Writing to the text file log.Write( "Hello!" ); log.Write( "How are you?" ); // Program ends here. The destructor // is called automatically when the log variable // goes out of scope and is destroyed. return 0; }
It can often be handy to overload our constructors so that we can initialize our objects in several different ways.
- Default Constructors
A default constructor is a constructor with no parameters in it. This will be called when a variable of this class type is declared with no constructor explicitly called.
Usually, a default constructor would be used to initialize variables to default values, and if your class contains pointers, this constructor should initialize those pointers to point to
nullptr.Declaring a class with a default constructor
class MyClass { public: MyClass() // Default constructor { m_value = 0; } private: int m_value; };
When we create a new object of this type like this, the default constructor will be called:
Instantiating a MyClass object variable, which will automatically call the default constructor
MyClass classVar;
- Parameterized Constructors
Parameterized Constructors take in one or more parameters to help initialize the member variables of the object. We can have 0, one, or multiple parameterized constructors for our class.
A class with a default constructor and a parameterized constructor
class MyClass { public: MyClass() { // Default m_value = 0; } MyClass( int value ) { // Parameterized m_value = value; } // etc };
When we instantiate our object, we can pass in argument(s) in order to call the parameterized version of the constructor:
Creating an object with its parameterized constructor
MyClass classVar( 100 );
If you declare a parameterized constructor but not a default constructor, then the C++ compiler will assume that you don't want an object to be declared with the default constructor. This means, you would only be able to declare the variable with an explicit call to the constructor and with arguments.
If this isn't the desired design, make sure to include a default constructor, even if you just leave it blank.
- Copy Constructors
A copy constructor takes in another object of the same type as its parameter and uses this to copy over members from the parameter to the new object.
A class with default, parameterized, and copy constructors
class MyClass { public: MyClass() // Default { m_value = 0; } MyClass( int value ) // Parameterized { m_value = value; } MyClass( const MyClass& other ) // Copy { m_value = other.m_value; } private: int m_value; };
In this case, we might already have an object of this type available, and when we are creating a new object, we want to make a copy of the old object:
First object is created with the parameterized constructor, second object is created with the copy constructor.
MyClass classVar( 100 ); MyClass anotherOne( classVar ); // Copy
- Design: When a class has multiple member variables, it is up to us to decide which variables get copied over during this operation. There could be some design cases where all information is copied over except certain fields (maybe a unique customerID or a name).
- Default copy constructor: If you don't explicitly declare a copy constructor, the C++ compiler will provide one for the class behind-the-scenes. This implicit copy constructor will only do shallow copies.
- Ways to copy
- A Shallow Copy is where values of variables are copied over. This is generally fine for any sort of non-pointer-based variables. If the class contains a pointer that is pointing to some address, the shallow-copy of the pointer will point to the same address.
- A Deep Copy is where values are copied over like with a shallow copy, but also will allocate new memory for a dynamic array (if the class has one) in order to copy over values of the element of the array to the new class copy.
- Example of a shallow copy:

With the implicit copy constructor, any pointers in the copied version will be pointing to the same address as in the original. If the class contains a dynamic array, both the copy and the original will end up pointing to the same address of the array in memory.
- Example of a deep copy:
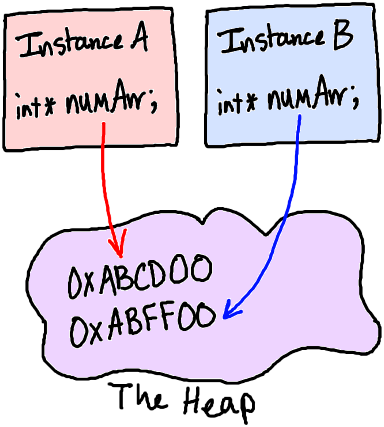
A new block of memory has been allocated for the
int * numArr. The values from InstanceA'snumArrwould be copied to InstanceB'snumArrvia a for loop during construction.Best practices:
- C.41: A constructor should create a fully initialized object
- C.43: Ensure that a copyable class has a default constructor
- C.45: Don’t define a default constructor that only initializes data members; use default member initializers instead
Review 9. Identify each of the following constructors:
class Book { public: Book(); Book( string newTitle, string newAuthor ); Book( const Book& otherBook ); ~Book(); /* ... */ };
- Copy constructor is:
- Default constructor is:
- Parameterized constructor is:
Review 10. The constructors and destructor must…
- ○ be declared as non-member functions
- ○ be Setter and Getter functions, respectively
- ○ match the name of the class
- Constructor:
When we declare a class' member function as const, we are saying that this function should not ever change any values of any member variables of this class. This can be handy for methods like a Display() where we just want to output member variables but should never change them.
class Coordinates { public: int GetX() const; // Can't change m_x or m_y int GetY() const; // Can't change m_x or m_y void SetX( int val ); void SetY( int val ); void Display() const; // Can't change m_x or m_y private: int m_x, m_y; };
The function definition will also need to have this const marked at the end of the function header as well.
int Coordinates::GetX() const { return m_x; } void Coordinates::Display() const { cout << "(" << m_x << ", " << m_y << ")"; }
Review 11. If we mark a class' member function as const (at the end of the function's header), this means that…
- ○ no class member variables can change values within this function
- ○ the return value of the function cannot be altered outside of the function
- ○ the function's definition cannot be updated by another programmer editing the code file
this pointer
Within our class methods, we can explicitly refer to the object we
are currently working with as this. this is a pointer, so it is
pointing to a memory address. Any member of the class can also be
accessed via the this pointer:
class MyClass { public: void SetVar( int var ) { // Set member var to parameter var this->var = var; } private: int var; };
In this example, the SetVar function takes in a parameter var, but
the class also has a member variable named var. In order to deal
with the ambiguity, we use this->var to explicitly mark that we
want "this" object's member variable version on the left-hand side
of our assignment statement.
Usually I get around this ambiguity by naming my parameters with something more unique, like…
void SetVar( int newVar ) { // Set member var to parameter var m_var = newVar; }
5.10. Week 10: Inheritance and composition
5.10.1. 📚 Intro: Inheritance and composition
Overview:
- Terms to know: Inheritance, composition, protected accessibility, function overriding
- Concepts:
- How to have one class inherit from another.
- How to have one class compose another.
- Reusing functionality
Inheritance is where one class inherits some or all member variables and functions from some parent class. Certain "traits" are passed on, and the child class can have additional member variables and functions defined, making it a more specialized version of the parent class.
Let's say we're designing an operating system that will store files. We can think about what all files have in common, and we can figure out what is different between different types of files. Any commonality could go in a base class (aka parent class).
So, a generic File class might have contain variables and functions like:
File - m_filename: string- m_extension: string- m_fileSize: size_t- m_creationDate: DateTime+ CreateFile(...): void+ RenameFile(...): void+ GetSize(): size_t+ GetPath(): stringThen we could have specialized file classes that inherit from the original File, such as TextFile, ImageFile, SoundFile, and so on. These would inherit all the common attributes of its parent (File), but each would have additional variables and methods that are suited specifically to its own specialization.
- TextFile:
m_textContent,Print() - ImageFile:
m_pixels[][],Draw(),EditPixel( x, y ) - SoundFile:
m_audioSample,m_length,Play(),Pause(),Stop()
Review 1. Member functions and variables that are shared between different classes should be created in the…
- ○ Child (sub) class
- ○ Function declaration
- ○ Parent (base) class
- Example: The iostream and fstream family
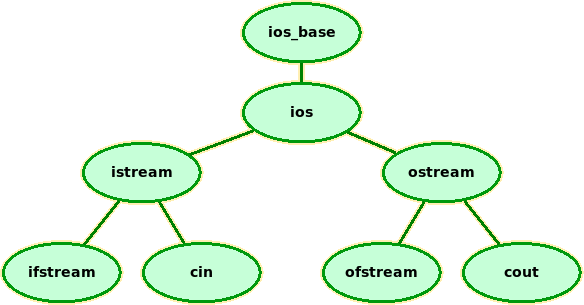
Part of the ios family. You can see the full library's family tree at http://www.cplusplus.com/reference/ios/
One family we've already been using are our console input/output streams,
cinandcout, and our file input/output streams,ifstreamandofstream. Working with each of these works largely the same way.When we overload the
<<and>>stream operators, we use a base type ofistreamandostreamso that our class can handlecin/coutANDifstream/ofstream, as well as any other streams in that family tree.
- TextFile:
- Inheritance (Is-A) vs. Composition (Has-A)
Another way we think about inheritance is that one class "is-a" type of other class.
Example: Car is-a vehicle:
class Car : public Vehicle { // etc. };
Whereas Composition, where one class contains another class as a member variable object, is known as a "has-a" relationship.
Example: Car has-an engine:
class Car { private: Engine engine; };
When is composition more appropriate than inheritance? This is a design question and it can really depend on how the designer feels about each one.
Review 2a. Composition means…
- ○ one class is a member variable of another class
- ○ one class IS another class, and then some
Review 2b. Inheritance means…
- ○ one class is a member variable of another class
- ○ one class IS another class, and then some
- Example: Game objects
For example, when writing a game, I find inheritance handy for creating game objects. A BaseObject can contain everything that's in common between all objects (characters, items, tiles, etc.), such as:
- BaseObject
Any items that don't animate, don't move, and just sit there in the level could be instantiated as a simple BaseObject and it would be fine.
BaseObject # m_position: Coordinate# m_sprite: Sprite# m_name: string+ Setup(...)+ SetTexture(...)+ Update(...)+ SetPosition(...)+ Draw(...)Then, let's say we want to build a 2D game level and each level is made up of a 2D array of tiles. Tiles will be very similar to objects, but maybe we want more information stored in a tile. We could then inherit from the BaseObject…
- Tile
The Tile class would have all the public and protected members from its parent, plus any new member variables and methods we declare within this class.
Tile Inherits from BaseObject - m_isSolid: bool- m_doesDamage: bool - Character
For the game characters, there would be two different types usually: characters that the players control and characters that the computer controls. Character could be its own base-class as well, implementing anything a character can do, with a Player and NPC (non-player-character) classes inheriting from Character.
Character Inherits from BaseObject # m_speed: int# m_direction: Direction# m_animFrame: float# m_maxFrames: float+ Move(...)+ Animate(...) - Player
Player Inherits from Character - m_score: int- m_experience: int- m_level: int+ HandleKeyboard(...)+ LevelUp(...)The Player class would be a specialized type of Character that can be controlled via the keyboard (or some other input device), as well as have information that a non-player-character generally has, such as a score or a level.
- NonPlayerCharacter
NPC Inherits from Character - m_difficulty: int- m_isFriendly: bool+ SetGoal(...)+ DecideNextAction(...)Likewise, the NPC class is a specialization of Character as well, but with special functionality and attributes of a character in the game controlled by the computer itself. This could include some form of AI to help the NPC decide how to behave.
Game object family:
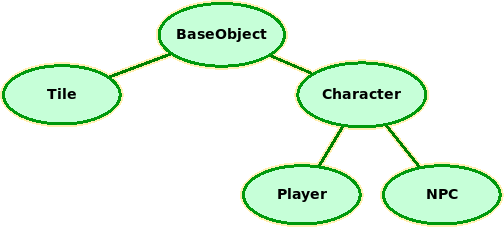
With this family of game objects, we could also write functions that work on all types of game objects, such as checking if there's a collision between items, because they all have a common parent.

- BaseObject
- Implementing inheritance
In C++ a class can inherit from one or more other classes. Note that Java and C# do not support multiple inheritance directly, if you end up switching to those languages. Design-wise, however, it can be messy to inherit from more than one parent and as an alternative, you might find a composition (has-a) approach a better design.
- Inheriting from one parent
To inherit from one other class in C++, all you need to do is add "
: public OTHERCLASS" after the "class CLASSNAME" at the beginning of your class declaration. With a public inheritance (the most common kind), the child class will inherit all public and protected members of the parent class.// File is the parent class File { protected: string name; string extension; size_t filesize; }; // TextDocument is the child class TextDocument : public File { protected: string textContents; /* Also inherits these members from File: string name; string extension; size_t filesize; */ };
Context: The Parent Class is often known as the superclass and the Child Class is often known as the subclass, particularly from the Java perspective.
- Inheriting from multiple parents
You can also have a class inherit from multiple parents, bringing in public/protected members from all parent classes, but again this can muddle your program's design somewhat and is generally pretty uncommon.
class AnimationObject // Parent A { public: void Animate(); protected: int totalFrames; int currentFrame; }; class PhysicsObject // Parent B { public: void Fall(); void Accelerate(); protected: float velocity; float acceleration; }; class PlayerCharacter : public AnimationObject, public PhysicsObject { public: void HandleKeyboard(); protected: string name; };
Review 3. A child class inherits its parents' (select all correct options):
- □ public
- □ private
- □ protected
… member … (select all correct options):
- □ variables
- □ functions
- Inheriting from one parent
- Accessibility - Private, Public, and Protected
class Child : public Parent // A public inheritance { };
Remember that we can declare our member variables and methods as private and public, but we can also make items protected. Protected members are similar to private, except that protected members will be inherited by child classes - private members do not get inherited.
Access Class' methods Childrens' methods Outside functions public Accessible Accessible Accessible protected Accessible Accessible Not accessible private Accessible Not accessible Not accessible Inheritance style
You can also use public, protected, and private when inheriting other classes. You probably won't need to ever do a protected or private inheritance.
- public inheritance: Child class inherits public and protected members from the parent.
- protected inheritance: Child class inherits public and protected members and turns them into protected members.
- private inheritance: class inherits public and protected members and turns them into private members.
This could be used if, for some reason, you want a child class to inherit certain members but don't want "grandchildren" to have access to those members as well.
Review 4. Just use
publicinheritance.- ○ OK
- ○ NEVER!!!
- Function overriding
When a child class inherits from a parent class, the parent class' public and protected methods are passed down to the child and these functions are still callable for objects of the child type. If we would like, the child class can also override any methods from the parent. This means that we write a new version of the function with the same return type and parameter list, and when that function is called from the child class, the child class' version will be called instead of the parents'.
Let's say we're writing a quizzer program that will support different question types. We can write a base "Question" class with whatever would be in common between all Questions:
class QuestionInterface { public: Question( string newQuestion ) ; void DisplayQuestion(); bool AskQuestion(); protected: string question; };
We can then inherit from our Question class to make different types of quiz questions: Multiple choice, true/false, and so on. Adding additional functionality means that we might want to rewrite how
AskQuestion()works - so we can. This also means that everything in our Question family has a similar interface – create a question, set it up, and then callAskQuestion()no matter what kind of question it is.class MultipleChoiceQuestion : public QuestionInterface { public: MultipleChoiceQuestion( string newAnswers[4], int newCorrect ); bool AskQuestion(); // Also inherits DisplayQuestion from parent protected: string answerChoices[4]; int correctIndex; };
The MultipleChoiceQuestion has an array of answers to choose from, but other question types might use different member variables - a true/false question could store
bool correctAnswer, a fill in the blank question could storestring correctAnswer, and so on.Review 5. Overriding means…
- ○ Having two functions with the same name but different parameter lists.
- ○ Using the same function signature as the parents' and then defining a new version for the child class.
- Calling the parents' version of a method
In some cases, perhaps the parent version of a method has some common functionality we will need no matter what version in the family we're using, but the child versions of the methods add on to that functionality. We can directly call the parent's version of some method from within a child's method by explicitly calling the method with the parent class name and the scope resolution operator ::.
class Lion { public: void Activities() { cout << "Hunt" << endl; cout << "Eat" << endl; cout << "Sleep" << endl; } }; class HouseCat : public Lion { public: void Activities() { Lion::Activities(); // CALL PARENT VERSION cout << "Talk to human" << endl; cout << "Use catbox" << endl; } };
For this example, the HouseCat does everything the Lion does and adds a few activities to the list. We don't have to re-write the same Activities from Lion - we can just call the parent's version of the method directly with
Lion::Activities();.Review 6. To call the parents' version of a function we have to prefix the function name with…
- ○ The child's class name and the
->arrow operator. - ○ The parent's class name and the
.dot operator. - ○ The parent's class name and then
::scope resolution operator. - ○ It is impossible to call a parents' version of a function once you've overridden it.
- ○ The child's class name and the
- Constructors and Destructors in the family
We often use constructors to initialize member variables for a class, and when a child is inheriting its parents' member variables, we want to make sure we're not forgetting to still initialize those variables.
We can call the parent's constructor from the child's constructor as well, but we do it via the initializer list of a constructor - a little bit of code after the constructor's function header that can be used to initialize variables and call the parent constructor.
class Person { public: Person( string name ) { m_name = name; } protected: string m_name; }; class Student : public Person { public: Student( string name, string major ) : Person( name ) // Calling the parent's constructor { m_major = major; } protected: string m_major; };
We can also initialize variables through the initializer list as well:
class Student : public Person { public: Student( string name, string major ) : Person( name ), m_major( major ) // Initializer { // nothing else to do now! } protected: string m_major; };
Review 7. If you put
:after the constructor's header, then you can…- ○ Call other functions and initialize variables.
- ○ Cause the program to crash.
- ○ Set member variables of child classes.
- ○ Erase all private member variables.